# Welcome to ITOC360

Never miss a critical alert again.

ITOC360 is an incident management and on-call platform for DevOps, SRE, and IT operations teams. It receives alerts from your inbound integrations, applies escalation logic, and notifies the right on-call engineer through their preferred channel — so critical issues are never missed.

***

### How ITOC360 works

{% stepper %}
{% step %}
**Ingest**

Alerts arrive from your inbound integrations via webhook-based Sources. ITOC360 supports Zabbix, Grafana, Prometheus, New Relic, PRTG, SolarWinds, ManageEngine, and 50+ additional integrations.
{% endstep %}

{% step %}
**Route**

Escalation Policies evaluate incoming alerts by severity and route them to the right team using Visual, JSON, or AI-assisted rule builders.
{% endstep %}

{% step %}
**Notify**

On-call engineers are notified through their configured channels. Each engineer chooses their own contact preference: voice call, SMS, or email.
{% endstep %}

{% step %}
**Resolve**

Engineers acknowledge and resolve incidents from the ITOC360 dashboard or directly from their notification. Every action is recorded in a full activity log.
{% endstep %}
{% endstepper %}

***

### Core capabilities

#### Multi-channel notifications

Engineers configure their own notification preferences. Voice, SMS, and email channels are verified independently before they can be used in escalation policies. Critical alerts reach on-call engineers even when they are away from their screens.

#### On-call scheduling

Build on-call rotations with daily and weekly recurrence, multi-user coverage, and shift swap capabilities. Schedules connect directly into escalation policies so the right person is always reachable.

#### Escalation policies

Define exactly what happens when an alert goes unacknowledged. Set a timeout, then escalate to a backup engineer, a different team, or a manager. Each source can have its own dedicated policy with multiple levels. Notification targets at each level can be a user, a team, or a schedule.

#### Inbound integrations

ITOC360 connects to any tool that supports outbound webhooks. The Alert Display Builder maps JSON fields from incoming payloads to alert fields without writing code — so on-call engineers see the right context immediately.

#### Incident management

Alerts that match an active escalation policy are promoted to incidents automatically. Each incident has a tracked lifecycle: open, acknowledged, and resolved. AI-assisted features support alert grouping, root cause analysis, and automated post-mortem creation.

#### Enterprise security

Two-factor authentication via TOTP or SMS, domain verification, and role-based access controls are available for all organizations.

***

### Get started

<table data-view="cards"><thead><tr><th></th><th></th><th></th></tr></thead><tbody><tr><td><strong>Quick Start</strong></td><td>Set up your first on-call rotation and route a live alert in under 15 minutes.</td><td><a href="/getting-started/quickstart">Quickstart</a></td></tr><tr><td><strong>Channels</strong></td><td>Add and verify your voice, SMS, and email contact details.</td><td><a href="/communication-and-shift-management/channels">Channels</a></td></tr><tr><td><strong>Sources</strong></td><td>Connect your inbound integrations and configure alert field mapping.</td><td><a href="/incidents-and-alerts/sources">Sources</a></td></tr><tr><td><strong>Escalations</strong></td><td>Define who gets notified, in what order, and when.</td><td><a href="/on-call-management-and-escalations/escalations">Escalations</a></td></tr></tbody></table>


# Quickstart Guide

Set up ITOC360 in 15 minutes. Connect your inbound integration tool, configure on-call notifications, create an escalation policy, and validate your first incident end to end.

{% hint style="info" %}
**What you will have after this guide:** a verified notification channel, a team with an on-call schedule, a connected inbound integration, an active escalation policy, and a confirmed incident notification.
{% endhint %}

***

{% stepper %}
{% step %}
**Create your account**

There are two ways to get started with ITOC360:

**Invited by a teammate** If you received an invitation email from an existing ITOC360 user, click the invitation link, complete your registration, and accept the invite. You will be added to their organization automatically.

**New organization** If you are setting up a new tenant, go to <https://itoc360.app> register with your work email, and complete the onboarding steps including payment. Your organization will be created and ready to configure.

After registration, confirm your email address to activate your account.

[Prefer to sign in with Google, Microsoft, or Slack instead of a password? See **Single sign-on / SSO**.](/users-and-access-management/single-sign-on-sso)
{% endstep %}

{% step %}
**Invite your team members**

Open **Management > Organization** and invite teammates by email.

| Role       | Access                                                       |
| ---------- | ------------------------------------------------------------ |
| **Admin**  | Full access to configuration, billing, and member management |
| **Member** | Manages schedules and responds to incidents                  |
| **Viewer** | Read-only access to dashboards and incident history          |

Invited users receive an email to complete their own registration. Each member should verify their notification channels (Step 3) before going on-call.
{% endstep %}

{% step %}
**Confirm notification channels**

Each on-call engineer must add and verify at least one notification channel before they can receive alerts.

1. Go to **Management > Channels** and click **Create Channel**.
2. Select the channel type: voice call, SMS, or email.
3. Enter your contact details and complete verification:
   * **SMS / Voice:** enter the OTP sent to your phone.
   * **Email:** click the confirmation link in your inbox.

Repeat for each channel you want active. Each engineer configures their own channel preferences.

{% hint style="warning" %}
Unverified channels cannot be used in escalation policies. Complete verification before moving to the next steps.
{% endhint %}

{% content-ref url="<https://docs.itoc360.com/communication-and-shift-management/channels>" %}
<https://docs.itoc360.com/communication-and-shift-management/channels>
{% endcontent-ref %}
{% endstep %}

{% step %}
**Create your first team**

1. Go to **Management > Teams** and click **Create Team**.
2. Give your team a name (for example, "DevOps Team").
3. Add members to the team.

{% content-ref url="<https://docs.itoc360.com/communication-and-shift-management/teams>" %}
<https://docs.itoc360.com/communication-and-shift-management/teams>
{% endcontent-ref %}
{% endstep %}

{% step %}
**Set up an on-call schedule**

A schedule defines who is on-call and when. Escalation policies can reference a schedule directly to determine who to notify.

1. Go to **Management > Schedules** and click **Create Schedule**.
2. Highlight the date and time range on the calendar.
3. Assign users to the selected time range.

{% content-ref url="<https://docs.itoc360.com/communication-and-shift-management/schedules>" %}
<https://docs.itoc360.com/communication-and-shift-management/schedules>
{% endcontent-ref %}
{% endstep %}

{% step %}
**Connect an inbound integration**

A Source is the connection point between your inbound integration and ITOC360.

1. Go to **Management > Sources** and click **Create Source**.
2. Give the source a name and select your inbound integration from the provider list.
3. Copy the generated webhook URL or integration token.
4. Paste it into your inbound integration's alert notification settings.

ITOC360 will receive alerts as soon as your inbound integration fires one to that endpoint.

<details>

<summary>Supported inbound integrations</summary>

Grafana, Zabbix, Prometheus Alertmanager, Datadog, and any tool that supports outbound HTTP webhooks. Use the **Custom Webhook** option for integrations not listed.

</details>

{% content-ref url="<https://docs.itoc360.com/incidents-and-alerts/sources>" %}
<https://docs.itoc360.com/incidents-and-alerts/sources>
{% endcontent-ref %}
{% endstep %}

{% step %}
**Create an escalation policy**

An escalation policy connects your Source to your on-call team and defines what happens when an alert is not acknowledged.

1. Go to **Management > Escalations** and click **Create Escalation**.
2. Select the Source you created in Step 6.
3. Add a rule using the Visual Builder:
   * Set the **notification target**: select a user, a team, or a schedule.
   * Set the **timeout**: how long ITOC360 waits before escalating to the next level.
4. Add additional escalation levels if needed.
5. Save the policy.

{% hint style="info" %}
An alert that reaches a level with no available on-call engineer will escalate to the next level immediately. Make sure at least one level always has coverage.
{% endhint %}

{% content-ref url="<https://docs.itoc360.com/on-call-management-and-escalations/escalations>" %}
<https://docs.itoc360.com/on-call-management-and-escalations/escalations>
{% endcontent-ref %}
{% endstep %}

{% step %}
**Trigger a test alert from your inbound integration**

Send a test alert from your inbound integration using the webhook URL or integration token configured in Step 6.

1. Open **Monitoring > Alerts** — the alert should appear within a few seconds.
2. If the alert matches an active escalation policy, ITOC360 automatically creates an incident.
3. Open **Monitoring > Incidents** and confirm the incident was created.

{% hint style="info" %}
No incident created? The alert may not have matched any escalation policy. Verify that the Source selected in your escalation policy matches the Source that received the alert.
{% endhint %}
{% endstep %}

{% step %}
**Validate incident notifications**

Confirm that notifications were delivered correctly.

1. Check the notification channels you configured in Step 3.
2. Open the incident in ITOC360 and review the **Activity Log** — it shows every notification sent, the channel used, and the delivery status.

{% hint style="warning" %}
**Notifications not arriving?** Check the following:

* Channel verification status in **Management > Channels**
* Escalation policy assignment in **Management > Escalations**
* Alert routing rules on the Source detail page
  {% endhint %}

{% hint style="success" %}
If the activity log shows the notification was sent and you received it, your on-call setup is working correctly.
{% endhint %}

{% content-ref url="<https://docs.itoc360.com/communication-and-shift-management/channels>" %}
<https://docs.itoc360.com/communication-and-shift-management/channels>
{% endcontent-ref %}
{% endstep %}
{% endstepper %}

***

### 🎉 You are ready!

Your first on-call rotation is fully configured. From here you can:

<table data-view="cards"><thead><tr><th></th><th></th><th></th></tr></thead><tbody><tr><td><strong>On-call schedules</strong></td><td>Add recurrence, multi-team rotations, and shift swaps.</td><td><a href="https://docs.itoc360.com/communication-and-shift-management/schedules">schedules</a></td></tr><tr><td><strong>Sources</strong></td><td>Connect additional inbound integrations and customize alert field mapping.</td><td><a href="https://docs.itoc360.com/incidents-and-alerts/sources">sources</a></td></tr><tr><td><strong>Escalations</strong></td><td>Build multi-level escalation logic for different alert severities.</td><td><a href="https://docs.itoc360.com/on-call-management-and-escalations/escalations">escalations</a></td></tr><tr><td><strong>Alerts</strong></td><td>Monitor all incoming alerts from your integrations in real time.</td><td><a data-mention href="/incidents-and-alerts/alerts">Alerts</a></td></tr><tr><td><strong>Incidents</strong></td><td>Track escalation executions and your team's response activity.</td><td><a data-mention href="/incidents-and-alerts/incidents">Incidents</a></td></tr><tr><td><strong>Maintenances</strong></td><td>Suppress notifications during planned downtime or deployments.</td><td><a data-mention href="/incidents-and-alerts/maintenances">Maintenances</a></td></tr><tr><td><strong>Silences</strong></td><td>Mute a specific alert fingerprint for a defined time window.</td><td><a data-mention href="/incidents-and-alerts/silences">Silences</a></td></tr><tr><td><strong>Integrations</strong></td><td>Connect your monitoring, observability, and DevOps tools via webhook.</td><td><a data-mention href="/integrations/inbound-integrations">INTEGRATIONS</a></td></tr></tbody></table>

<br>


# Channels

Channels are the contact methods ITOC360 uses to notify you when an incident occurs or an alert is triggered.

{% hint style="info" %}
Before you can be assigned to a team or placed on a schedule, you must define how you want to be reached.
{% endhint %}

This page allows you to manage your personal contact information, ensuring critical alerts reach you through the most effective medium, whether via a phone call, SMS, or email.

#### Supported Channel Types

ITOC360 supports multiple communication methods to ensure redundancy:

* **Voice (Phone Call):** The system places a call to your mobile or landline and uses text-to-speech to read the alert details.
  * *Best for:* Critical/High-severity alerts, waking up on-call engineers at night.
* **SMS:** Sends a text message containing the alert summary and a link to the incident details.
  * *Best for:* Quick context when you are away from a computer.
* **E-mail:** Sends a detailed notification including logs, charts, and extended descriptions.
  * *Best for:* Low-severity alerts or archiving incident details.

#### Adding a New Channel

To add a new contact method to your profile:

1. Navigate to Management > Channels.
2. Click the "Create Channel" button in the top right corner.
3. In the configuration modal, fill in the following fields:
   * User: Select the related user.
   * Type: Select the communication method (e.g., Phone Number, SMS, E-mail).
   * Label: Give this channel a recognizable label (e.g., "Personal Mobile", "Work Email").
   * Value: Enter the phone number or email address.
   * Locale: Select the language to use when contacting you through this channel.
   * *Note: For phone numbers, always include the Country Code (e.g., +1 for US, +90 for TR).*
4. Click Save to confirm.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FFFsCa8ogWewz9Ka32KwJ%2FScreenshot%202026-01-30%20at%2015.47.59.png?alt=media&amp;token=6f84d68f-0662-4618-b2ad-8feb9950e973" alt=""><figcaption></figcaption></figure>

#### Verifying Your Channels

To ensure reliability, ITOC360 requires you to verify every new channel before it can be used in notification rules or teams.

* **For E-mail:** Check your inbox for a verification email from ITOC360 and click the confirmation link.
* **For SMS & Voice:** You will receive a 6-digit One-Time Password (OTP) via text or call. Enter this code in the verification prompt on the screen.

> **Warning:** Unverified channels will appear as "Pending" and will not receive alerts.

#### Best Practices

* **Redundancy is Key:** Do not rely on a single channel. We strongly recommend adding at least one Voice number and one E-mail address. Internet connectivity issues might delay emails, but voice calls often get through.
* **Clear Naming:** Use descriptive names for your channels (e.g., instead of just "Phone", use "Primary Mobile" or "Home Landline"). This helps when setting up specific notification policies later.


# Teams

In ITOC360, Teams are logical groups of users responsible for specific services, applications, or infrastructure components (e.g., "DevOps Team", "Database Admins", "Backend Support").

Creating a Team is the essential bridge between individual users and the on-call schedule. Instead of assigning alerts to a single person, you assign them to a Team, ensuring that if one person is unavailable, others in the group can step in.

#### Why Create a Team?

* **Centralized Management:** Manage responders for specific services in one place.
* **Collaboration:** Members within a team can view shared schedules and acknowledge alerts assigned to their group.
* **Visibility:** Easily see who is on duty for a specific department.

#### Creating a New Team

To organize your responders into a group:

1. Navigate to Management > Teams.
2. Click the "**Create Team**" button.
3. Enter the **Team Name** (e.g., "Network Operations").
4. Add a Description to help others understand the scope of this team.
5. Select if it is active or not.
6. Click **Create** to initialize the group.

#### Adding Members to a Team

Once the team is created, you need to add users. ITOC360 uses the Channels configured by each user to deliver notifications.

1. Find your team in the list.
2. Click the **three-dots** menu on the far right.
3. Click **Manage Members**.
4. Select the **User** you want to add.
5. Select which of the user’s **Channels** will be included in this team.
   * Example: include only "Work Email" and "Personal Mobile".
6. Click **Save**.

> Note on Channels: Team notifications are sent only through the Channels you select here. These Channels must already exist in the user’s profile (Management > Channels).

#### Best Practices

* Service-Based Grouping: It is best practice to create teams based on the services they support (e.g., "Billing Service Team") rather than generic titles. This makes it easier to route alerts correctly later.
* Keep Members Updated: If an employee leaves the company or changes departments, remember to remove them from the Team list to prevent "Ghost Paging" (alerts going to inactive users).


# Schedules

Schedules are the time-based engines of ITOC360. They determine strictly who is on-call at what specific time.

While a **Team** groups your responders together, the **Schedule** defines the rotation logic (e.g., "User A is on duty this week, User B is on duty next week"). When an incident occurs, ITOC360 checks the active Schedule to find the current on-call person and notifies them via their defined Channels.

#### Creating a New Schedule

To set up an on-call schedule for your team:

1. Navigate to Management > **Schedules**.
2. Click the **Create Schedule** button.
3. **Name:** Give the schedule a clear name (e.g., "DBA - Primary On-Call").
4. **Description:** Add context about what this schedule covers.
5. **Time Zone:** Select the operational time zone.
   * *Critical:* All shift start/end times will be calculated based on this setting.
6. **Active:** Enable this to make the schedule eligible for alert routing. Disable it to keep the schedule as a draft or temporarily stop notifications.
7. Click **Create** to finish.

#### Managing a Schedule

After you create a schedule, you can assign who is on-call for a specific time range.

1. Navigate to Management > **Schedules**.
2. Find the schedule you created and click it.
3. On the calendar, highlight the date/time range you want to configure.
4. In the modal that opens, select the **users** for this schedule.
5. Select which of their **Channels** will be included for this schedule.
6. Click **Save** to apply the assignment.


# Escalations

Escalations are the decision engines of ITOC360. While "Sources" bring the data in, Escalations decide what to do with it.

An Escalation Policy allows you to filter incoming alerts based on specific rules (e.g., "Only alerts with severity 'Disaster'") and define a step-by-step notification path (e.g., "Notify the On-Call Engineer first; if they don't answer in 5 minutes, notify the Manager").

#### Creating an Escalation Policy

To set up your routing logic:

1. Navigate to Management > **Escalations**.
2. Click the **Create Escalation** button.
3. **Name:** Give your policy a clear name (e.g., "Database Critical Incidents").
4. **Description:** Optional. Add a short summary of what this policy routes and why (e.g., “Escalate Zabbix DB `DISASTER` alerts to DBA on-call”).
5. **Source:** Select the Source you created in the previous step (e.g., "Zabbix Prod"). This links the policy to a specific data stream.

#### Rule Engine

This is where you define which alerts trigger this policy. ITOC360 provides a flexible Rule Builder with three modes:

* **Visual:** A point-and-click interface to build logic without code. You can group conditions using `AND` / `OR` logic.
  * *Example:* IF `$.status` EQUALS `PROBLEM` AND `$.severity` EQUALS `DISASTER`.
* **JSON:** For advanced users who prefer writing raw query logic.
* **AI (Coming Soon):** An intelligent assistant that helps you generate rules using natural language.

Once your conditions are set, toggle the Active switch to ON and click **Create**.

{% hint style="info" %}
**Pro Tip:** To streamline your setup, you don't have to start from scratch. You can quickly apply a pre-configured Rule Template or Import an existing JSON rule structure.
{% endhint %}

#### Defining Escalation Levels

After creating the policy, you must define the notification steps. This is done via **Levels**.

1. Click on the name of the Escalation Policy you just created.
2. Switch to the **Levels** tab.
3. Click **Create Level**.

**Level Configuration**

A "Level" represents a step in the chain of command.

* **Level Number:** The order of execution (e.g., Level 1 runs first).
* **Timeout:** The duration (in seconds) the system waits before escalating to the next level. (e.g., `300` for 5 minutes).
* **Stop on Acknowledge:** If checked, the escalation process stops immediately if a user acknowledges the alert. (Highly Recommended).
  * <mark style="color:$info;">**For more information ->**</mark> [<mark style="color:$primary;">**Acknowledge System**</mark>](/incidents-and-alerts/incidents/acknowledge-system)
* **Stop on Recovery:** If checked, the escalation stops if the monitoring tool sends a "Resolved/OK" signal.

#### Assigning Recipients to Levels

Once a level is created, you define who gets notified at that step. You can assign:

* **A Specific User:** For direct notification.
* **A Team:** To notify all members or use the team's internal logic.
* **A Schedule:** To automatically route the alert to whoever is currently on-call according to the shift calendar.

Example Scenario:

* **Level 1:** Notify "Database Schedule" (On-Call Engineer). Wait 5 minutes.
* **Level 2:** Notify "Team Lead". Wait 10 minutes.
* **Level 3:** Notify "CTO".


# Escalation Grouping

When a system starts having problems, it rarely fires a single alert. A database going down might trigger dozens of alerts within seconds, one for each dependent service, check, or threshold.

Without grouping, each of those alerts would kick off its own escalation chain and wake up your on-call engineer multiple times for what is fundamentally the same incident.

Escalation Grouping solves this by collecting related alerts into a single incident window before the escalation process begins.

### Configuring Grouping

To set up grouping for an escalation policy:

1. Navigate to **Management > Escalations** and open the policy you want to configure.
2. Switch to the **Settings** tab and find the **Grouping** section.
3. Click **Configure**.

The modal that opens lets you choose a grouping mode and set the timing parameters.

### Grouping Modes

There are three modes to choose from, depending on how your alert patterns behave.

#### Disabled

No grouping is applied. Each incoming alert triggers its own escalation independently, without being merged into a shared window. This works well for low-volume, isolated incidents where every alert is expected to be distinct.

#### Fixed

The grouping window opens when the first alert arrives and runs for a set duration (the **Group Interval**). Alerts that come in during this window are added to the same incident. New alerts do not extend the window; the timer was set at the start and doesn't move. When it runs out, the group closes and escalation proceeds.

Use Fixed when you know your alert bursts are short-lived and predictable. It gives you a hard boundary on how long alerts are held before someone gets notified.

#### Sliding

Similar to Fixed, but each new alert resets the countdown. As long as alerts keep coming in, the window keeps sliding forward. The group only closes once there's been a quiet period with no new alerts for the full Group Interval duration.

Use Sliding when your incidents tend to produce waves of alerts with short gaps in between. It keeps everything under one incident until the situation actually settles down.

### Window and Timing

#### Group Interval

Defined in seconds. This is the core timer for both Fixed and Sliding modes:

* In **Fixed** mode, it's the total duration of the grouping window from the moment the first alert arrives.
* In **Sliding** mode, it's the quiet period required before the group closes. Each new alert restarts this wait.

Adjust this based on how long your typical alert bursts last.

#### Upper Limits

**Max group duration** (Sliding only) sets the hard ceiling on how long a group can stay open in total, in seconds. Without it, a continuous stream of alerts could keep sliding the window indefinitely.

#### Max Group Size

The maximum number of alerts that can be collected into a single group. Once this count is reached, the group closes immediately with no waiting for the interval to expire. Escalation kicks off right away.

This acts as a safety valve for unusually large incidents where waiting for the timer would delay the response too long.

### Choosing the Right Mode

A few practical guidelines:

* If you receive highly critical alerts from your monitoring tool and don't want to wait for any grouping window before getting notified, **Disabled** is the right choice.
* If you see short bursts of alerts during incidents, **Fixed** is usually the right call. It's simpler and more predictable.
* If your incidents roll in waves, with alerts firing, pausing, then firing again, **Sliding** keeps them grouped until things actually calm down.

When in doubt, start with **Fixed** and adjust the interval based on what you see in practice.


# Sources

Sources are the ingestion points for your monitoring data. They act as the bridge between your external monitoring tools (like Zabbix, Grafana, or New Relic) and ITOC360.

By creating a Source, you generate a unique endpoint (Webhook) that allows ITOC360 to receive, parse, and route alerts from your infrastructure.

#### Creating a New Source

To start receiving alerts, you must first configure a source:

1. Navigate to Management > **Sources**.
2. Click the **Create Source** button.
3. **Name:** Enter a descriptive name for this source (e.g., "Production Zabbix Server").
4. **Provider:** Select the integration type from the dropdown menu.
   * ***Supported Providers include:*** Zabbix, Grafana, Manage Engine, New Relic, Prometheus, PRTG, Solarwinds, and an expanding library of 100+ integrations.

#### Configuring the Alert Display

Once a provider is selected, ITOC360 presents the **Alert Display Builder**. This powerful tool allows you to map the incoming data fields from your monitoring tool to the alert format displayed in ITOC360.

* Customize Fields: You can select specific fields (e.g., Hostname, Severity, Error Message) available from the provider's payload.
* Preview: Configure how the alert title and description will appear to your on-call engineers. This ensures that the most critical information is visible at a glance without needing to parse raw JSON.

#### Source Settings

Before finalizing, you can configure the lifecycle and status of the source:

* **Expires At (Optional):** If this source is temporary (e.g., for a specific POC, migration project, or penetration test), you can set an expiration date. The source will automatically stop accepting alerts after this date.
* **Active:** Toggle this ON to enable the source immediately. If switched OFF, the source is created but will reject any incoming data (useful for maintenance modes).

Click **Create** to finish the setup.

#### Retrieving the Webhook Token

After creating the source, you need to connect your external tool to ITOC360.

1. On the **Sources** page, click on the name of the source you just created.
2. Locate the Token section.
3. Copy this Token.
4. Paste this into the notification/webhook configuration settings of your external monitoring tool (e.g., paste it into the Zabbix Media Type script or Grafana Notification Channel).

> Security Tip: Treat your Webhook Token like a password. Anyone with this token can send alerts to your system.


# Alerts

The Alerts page is the central operational dashboard of ITOC360. It provides a real-time, unified view of all incidents flowing into the system from your various monitoring tools.

This screen is designed for high observability, allowing your team to quickly identify, prioritize, and respond to critical issues across your infrastructure.

#### The Alert List

The main dashboard displays a grid of all active and historical alerts. Here is a breakdown of the information provided in each column:

* **Provider:** Indicates the technology ecosystem the alert originated from (e.g., Zabbix, Grafana). This helps in quickly identifying the layer of the stack affected.
* **Source:** The specific user-defined integration name (configured in the ***Sources*** section). This tells you exactly which server group, region, or environment sent the alert (e.g., "Prod-DB-Cluster-01").
* **Alert:** The core message or title of the incident. This text is typically parsed from the monitoring payload to show the most relevant error description.
* **Severity:** A visual indicator of urgency (e.g., `Critical`, `Warning`, `Info`). Use this to prioritize which fires to put out first.
* **Status:** The current lifecycle state of the alert (e.g., `Firing`, `Acknowledged`, `Resolved`). This status updates in real-time as the system processes the event or as engineers take action.
* **Created At:** The exact timestamp when the alert was received by ITOC360.

#### Working with Alerts

**1. Triage & Prioritization:** Use the **Severity** column to sort the grid. High-severity incidents (like "Disaster" or "Critical") are typically highlighted to grab immediate attention.

**2. Alert Details:** Clicking on any row in the list will open the Alert Detail View.

**3. Filtering:** You can filter the list by Status to focus only on "Active" issues, removing the noise of resolved incidents from your immediate view.


# Incidents

While the Alerts page displays the incoming signals from your monitoring tools, the Incidents page tracks the execution of the response.

An "Incident" in ITOC360 represents an active or past execution of an Escalation Policy. This is where you audit the system's attempts to notify your team, seeing exactly which policy was triggered and the current status of that notification chain.

#### Incident List

This dashboard provides a timeline of your team's response activities.

* **Alert:** The reference to the original triggering event. This links the incident back to the specific raw data received on the **Alerts** page.
* **Escalation:** The name of the specific Escalation Policy that matched the alert rules. This tells you *which* set of notification rules represents this incident (e.g., "Critical DB Policy" vs. "General Warning Policy").
* **Status:** The current state of the notification workflow.
  * *Running/Active:* The system is currently executing the levels (e.g., waiting for a timeout, calling the next person).
  * *Completed/Resolved:* The escalation chain has finished, either because someone acknowledged the alert or all steps were exhausted.
* **Started At:** The exact timestamp when the escalation policy was triggered.
* **Completed At:** The timestamp when the incident workflow ended.
  * *Pro Tip:* The difference between *Started At* and *Completed At* is effectively your MTTA (Mean Time to Acknowledge) for that specific incident.
* **Created At:** The record creation time in the system.

#### Understanding the Lifecycle

Unlike a static log, an Incident is dynamic.

1. **Trigger:** An alert matches a Rule in an Escalation Policy.
2. **Creation:** An Incident record is created, and the Status is set to Active/Running.
3. **Execution:** ITOC360 begins processing "Level 1", then "Level 2", notifying users via their defined Channels.
4. **Completion:** Once a user acknowledges the incident (or the policy runs out of steps), the Status updates to Completed, and the *Completed At* timestamp is stamped.

#### Why use this page?

* **Real-Time Auditing:** If you are wondering, "Is the system currently calling anyone regarding the server outage?", check the rows with Status: Running.
* **Post-Mortem Analysis:** Use the *Started At* and *Completed At* times to analyze how long it typically takes for your policies to find an available responder.


# Acknowledge System

The Acknowledge action is the signal that tells ITOC360: "I have seen this issue and I am working on it."

Acknowledging an incident is crucial because it triggers the **Stop on Acknowledge** logic defined in your Escalation Policies. Once acknowledged, the system **stops notifying** other team members or escalating to the next level, preventing unnecessary noise.

ITOC360 offers two convenient ways to acknowledge an incident.

#### Method 1: Instant Acknowledge (via Public Link)

This is the fastest method, designed for responders who are on the go or away from their dashboard.

When you receive a notification via SMS or Email, it includes a unique, secure link.

1. **Click the Link:** Open the URL provided in the notification message.
2. **No Login Required:** You will be directed to a public acknowledgement page. You do not need to log in to the ITOC360 dashboard to perform this action.
3. **Confirm:** Review the brief summary and click the Acknowledge button.

*By clicking acknowledge, you confirm that you have received the alert and taken ownership of the incident.*

> **Security Note:** The link generated is unique to the incident and secure. It allows only for the acknowledgement action and does not expose sensitive internal system data.

#### Method 2: Dashboard Acknowledge

If you are already logged into the ITOC360 portal or triaging multiple issues, you can acknowledge incidents directly from the interface.

1. Navigate to the Monitoring > **Alerts** page.
2. Click on the specific alert to open the **Detail View**.
3. Locate the **Acknowledge** button in the top-right corner of the detail panel.
4. A**dd a Note (Optional):** You can enter a brief message (e.g., "Checking the database logs now") to provide context to your team.
5. Click **Confirm**.

#### What happens after Acknowledgement?

Once an incident is successfully acknowledged (via either method):

1. **Escalation Stops:** The countdown for the next escalation level is cancelled immediately. No further phone calls or SMS messages will be sent for this specific incident.
2. **Status Update:** The status of the incident changes from **Triggered/Open** to **Acknowledged** on the dashboard.
3. **Audit Log:** The system records *who* acknowledged the alert and *when* (and via which method), providing a clear timeline for post-mortem analysis.


# Maintenances

Maintenances let you suppress alert notifications for a defined time window — so planned downtime, deployments, or scheduled restarts don't trigger false on-call pages.

When an active maintenance window is in place, incoming alerts that match the associated escalation policy are received but not escalated. No voice calls, SMS messages, or emails are sent until the window ends.

### How maintenances work

1. **Create a window** — Define a name, select a tenant and escalation policy, then set start and end times for the window.
2. **Alerts are silenced** — While the window is active, alerts routed through the selected escalation policy are suppressed. They are still recorded in the dashboard but do not trigger notifications.
3. **Window expires** — Once the end time is reached, the maintenance window moves to **Expired** status. Normal escalation resumes automatically — no manual action needed.

### Creating a maintenance window

Navigate to **Monitoring → Maintenances** and click **Create Maintenance** in the top-right corner.

Fill in the following fields:

| Field       | Description                                                                     |
| ----------- | ------------------------------------------------------------------------------- |
| Name        | A short label to identify this window (e.g. `weekly-patching`, `db-migration`). |
| Description | Optional. Add context about the reason for the maintenance.                     |
| Escalation  | The escalation policy to silence during this window.                            |
| Starts At   | Date and time the window begins.                                                |
| Ends At     | Date and time the window ends. Must be after **Starts At**.                     |

Click **Create** to activate the window immediately if the start time has already passed, or to schedule it for the future.

### Maintenance statuses

| Status    | Meaning                                                      |
| --------- | ------------------------------------------------------------ |
| Active    | The window is currently in effect. Notifications are paused. |
| Scheduled | The window is configured but has not started yet.            |
| Expired   | The window has ended. Escalation is fully restored.          |

### Viewing and managing windows

Navigate to **Monitoring → Maintenances** to see all windows across your tenants. Use the **Search** field to filter by name, or use the **Status** filter to narrow results to active, scheduled, or expired windows.

Each row displays:

* **Name** — the label you assigned
* **Escalation** — the policy being silenced
* **Status** — current state of the window
* **Created At** — when the window was created

Click the **⋯** menu on any row to view details or delete the window.

> **Warning:** Deleting an active maintenance window immediately restores escalation for the affected policy. Any alerts that arrive after deletion will trigger notifications normally.

### Best practices

* **Name windows descriptively.** Use names that reflect the actual change event (e.g. `k8s-node-drain-prod`) rather than generic labels like `test`.
* **Set the tightest window possible.** Overly wide windows increase the risk of missing real incidents. Adjust **Ends At** to match your expected downtime closely.
* **Scope to a single escalation.** Avoid silencing a broad policy if only one service is affected. Create a dedicated escalation for that service and target it specifically.
* **Review expired windows.** Periodically clean up old entries to keep the list readable.


# Silences

Alert silences let you suppress incident creation for a specific alert during a defined time window, preventing unnecessary on-call escalations when a known issue or planned activity is already being handled.

When a silence is active, matching alerts are received but not escalated. They remain recorded in the Alerts list, but no incident is opened and no notifications are sent until the silence expires.

### How silences work

1. **Create a silence** — Open the alert you want to suppress, click **Silence**, and set a description and end time. The silence activates immediately.
2. **Alerts are suppressed** — During the active window, any incoming alert with a matching fingerprint is logged but does not trigger an incident. On-call responders are not notified.
3. **Silence expires** — When the end time arrives, the silence becomes **Inactive**. Incident creation and escalation resume automatically for that alert fingerprint.

### Creating a silence

Navigate to **Monitoring → Alerts** and open the alert you want to silence. Click the **Silence** button in the top-right corner of the alert detail page.

Complete these fields:

| Field       | Description                                                                                                           |
| ----------- | --------------------------------------------------------------------------------------------------------------------- |
| Description | Optional note explaining why the alert is being silenced (e.g., `scheduled disk cleanup`, `fix pending until Apr 11`) |
| Ends At     | Date and time when the silence expires and escalation resumes                                                         |

Click **Silence** to activate.

> **Note:** A silence is matched to incoming alerts by fingerprint — a unique hash of the alert name, host, and tags. Only alerts with an identical fingerprint are suppressed. Alerts from a different host or with different tags are not affected.

### Silence statuses

| Status   | Meaning                                                                                      |
| -------- | -------------------------------------------------------------------------------------------- |
| Active   | Silence is running. Matching alerts are suppressed and no incidents are created.             |
| Inactive | Silence has expired or was manually deactivated. Matching alerts trigger incidents normally. |

### Viewing and managing silences

Navigate to **Monitoring → Silences** to see all silences across your account.

Each row shows:

* **Fingerprint** — the alert fingerprint this silence matches
* **Description** — the note entered at creation
* **Status** — current state: Active or Inactive
* **Ends At** — scheduled expiry time
* **Created At** — when the silence was created

Use the **Search** field to filter by fingerprint or description. Use the **Status** filter to show only active or inactive silences.

Click any row to open the silence detail page. From there you can:

* **Edit** — update the description, tenant, or end time of an active silence without interrupting it
* **Deactivate** — end the silence immediately, before the scheduled expiry

> **Warning:** Clicking **Deactivate** ends the silence instantly. Any matching alert that arrives after deactivation will trigger an incident and notify on-call responders.

### Silences tab on the alert detail page

When viewing an alert, the **Silences** tab (next to Overview) lists all silences currently linked to that alert. Check this tab before creating a new silence to avoid duplicates.

### Alerts panel on the silence detail page

The right-side **Alerts** panel on a silence detail page lists every alert that was suppressed by that silence, along with each alert's status and creation time. If the silence has not matched any incoming alert yet, it shows **"No alerts found."**

### Best practices

* **Set the tightest window possible.** Overly long silences increase the risk of missing real incidents. Set **Ends At** to match the expected resolution time closely.
* **Write a clear description.** Include the reason and a reference if applicable (e.g., `JIRA-1234 - disk cleanup in progress`). This helps teammates understand active silences at a glance.
* **Deactivate early when the issue is resolved.** If the situation clears before the silence expires, deactivate it immediately so the alert resumes normal escalation.
* **Check the Silences tab before creating a new one.** If a silence already exists for an alert, avoid creating a duplicate.


# Inbound Integrations

ITOC360 receives alerts from your existing monitoring, observability, security, and DevOps tools through inbound integrations. Each integration connects to ITOC360 via a webhook-based Source, allowing alerts to flow into your escalation policies automatically.

***

### Integration categories

Browse integrations by category to find setup instructions for your tools:

<table data-view="cards"><thead><tr><th></th><th></th><th></th></tr></thead><tbody><tr><td><strong>Infrastructure Monitoring</strong></td><td>Zabbix, PRTG, SolarWinds, ManageEngine OpManager, CheckMK, Instana</td><td>infrastructure-and-network-monitoring.md</td></tr><tr><td><strong>Observability and APM</strong></td><td>Grafana, Prometheus, Datadog, New Relic, Dynatrace, AppDynamics, and more</td><td>observability-and-apm.md</td></tr><tr><td><strong>Cloud Monitoring</strong></td><td>AWS CloudWatch, AWS Budget, Google Cloud Monitor, Azure Monitor, Alibaba CloudMonitor</td><td>cloud-monitoring.md</td></tr><tr><td><strong>Log Management</strong></td><td>Grafana Loki, Grafana Mimir, Graylog, InfluxDB</td><td>log-management.md</td></tr><tr><td><strong>Security</strong></td><td>AWS GuardDuty, Azure Sentinel, Google Security Command Center, CrowdStrike</td><td>security.md</td></tr><tr><td><strong>DevOps and CI/CD</strong></td><td>ArgoCD, Azure DevOps, GitHub, GitLab, Jenkins, Terraform Cloud</td><td>devops-and-cicd.md</td></tr><tr><td><strong>Error Tracking and Uptime</strong></td><td>Sentry, Rollbar, Pingdom, StatusCake, Postman, Statuspage.io</td><td>error-tracking-and-uptime.md</td></tr><tr><td><strong>Workflow and Automation</strong></td><td>Zapier, n8n, Jira, Twilio, MongoDB Atlas, Salesforce</td><td>workflow-and-automation.md</td></tr></tbody></table>

***

### How inbound integrations work

Every inbound integration connects to ITOC360 through a Source. When you create a Source in **Management > Sources**, ITOC360 generates a unique webhook URL and token. You paste this into your external tool's notification or alerting settings. From that point, alerts are sent to ITOC360 automatically whenever your tool fires one.

Incoming alerts are matched against your active escalation policies. If a match is found, ITOC360 creates an incident and notifies the assigned on-call engineer.

{% hint style="info" %}
Any tool that supports outbound HTTP webhooks can connect to ITOC360, even if it is not listed in the categories above. Use the **Custom Webhook** option when creating a Source.
{% endhint %}


# Infrastructure Monitoring

This category covers tools that monitor the health of physical and virtual infrastructure: servers, network devices, bandwidth, disk usage, and service availability. When a threshold is breached, these tools send alerts to ITOC360 to trigger on-call notifications.

***

### Integrations in this category

| Integration                | What it monitors                                   | Alert delivery |
| -------------------------- | -------------------------------------------------- | -------------- |
| **Zabbix**                 | Servers, network devices, applications, databases  | Webhook        |
| **PRTG Network Monitor**   | Network bandwidth, uptime, hardware sensors        | Webhook        |
| **SolarWinds Orion**       | Network performance, server health, flow analysis  | Webhook        |
| **ManageEngine OpManager** | Network devices, servers, virtual machines         | Webhook        |
| **CheckMK**                | Hosts, services, containers, cloud resources       | Webhook        |
| **Instana**                | Microservices, Kubernetes, application performance | Webhook        |
| **Salesforce**             | CRM cases, support tickets, workflow alerts        | Apex Trigger   |

***

### How it works

Infrastructure monitoring tools continuously check your hosts and services against defined thresholds. When a threshold is exceeded — a server goes down, CPU spikes, or a network device becomes unreachable — the tool sends an alert payload to your ITOC360 Source webhook URL. ITOC360 parses the payload, matches it against your escalation policies, and notifies the on-call engineer responsible for that infrastructure.

{% hint style="info" %}
ITOC360 generates a unique webhook URL per Source. Go to **Management > Sources**, create a Source, and copy the webhook URL or token to paste into your monitoring tool's notification settings.
{% endhint %}

***

### Get started


# Checkmk Integration

[Checkmk](https://checkmk.com/) is an enterprise-grade monitoring platform used to monitor servers, applications, networks, and cloud infrastructure. By installing a custom notification script on your Checkmk site, you can forward host and service alerts directly to ITOC360 and trigger your on-call escalation policies in real time.

### Provider Configuration & Mapping

ITOC360 uses the `notification_type` field from the Checkmk payload to determine the alert type.

| Checkmk Notification Type | ITOC360 Type |
| ------------------------- | ------------ |
| `PROBLEM`                 | ALERT        |
| `RECOVERY`                | RESOLVE      |

Priority is read from the `severity` field, which maps to the Checkmk host severity environment variable.

| Checkmk Severity | ITOC360 Priority |
| ---------------- | ---------------- |
| `OK`             | LOW              |
| `WARNING`        | MEDIUM           |
| `CRITICAL`       | CRITICAL         |

### Setup Instructions

#### Step 1: Get Your Webhook URL and Token

1. Log in to your ITOC360 platform.
2. Go to **Sources → Add Source**.
3. Select **Checkmk** as your provider.
4. Save the configuration and copy the generated **Token**.

#### Step 2: Install the Notification Script

The ITOC360 notification script must be placed in the Checkmk notifications directory on your Checkmk server.

Create the file at the following path:

```
~/local/share/check_mk/notifications/itoc360.sh
```

Paste the following content into the file:

```bash
#!/bin/bash
curl -s -X POST "https://api.itoc360.app/functions/v1/events?token=$NOTIFY_PARAMETER_1" \
  -H "Content-Type: application/json" \
  -d "{
    \"host\": \"$NOTIFY_HOSTNAME\",
    \"service\": \"$NOTIFY_SERVICEDESC\",
    \"state\": \"$NOTIFY_SERVICESTATE\",
    \"host_state\": \"$NOTIFY_HOSTSTATE\",
    \"notification_type\": \"$NOTIFY_NOTIFICATIONTYPE\",
    \"output\": \"$NOTIFY_SERVICEOUTPUT\",
    \"host_output\": \"$NOTIFY_HOSTOUTPUT\",
    \"severity\": \"$NOTIFY_HOSTSEVERITY\",
    \"timestamp\": \"$NOTIFY_SHORTDATETIME\"
  }"
```

Then make the script executable:

```bash
chmod +x ~/local/share/check_mk/notifications/itoc360.sh
```

#### Step 3: Create a Notification Rule

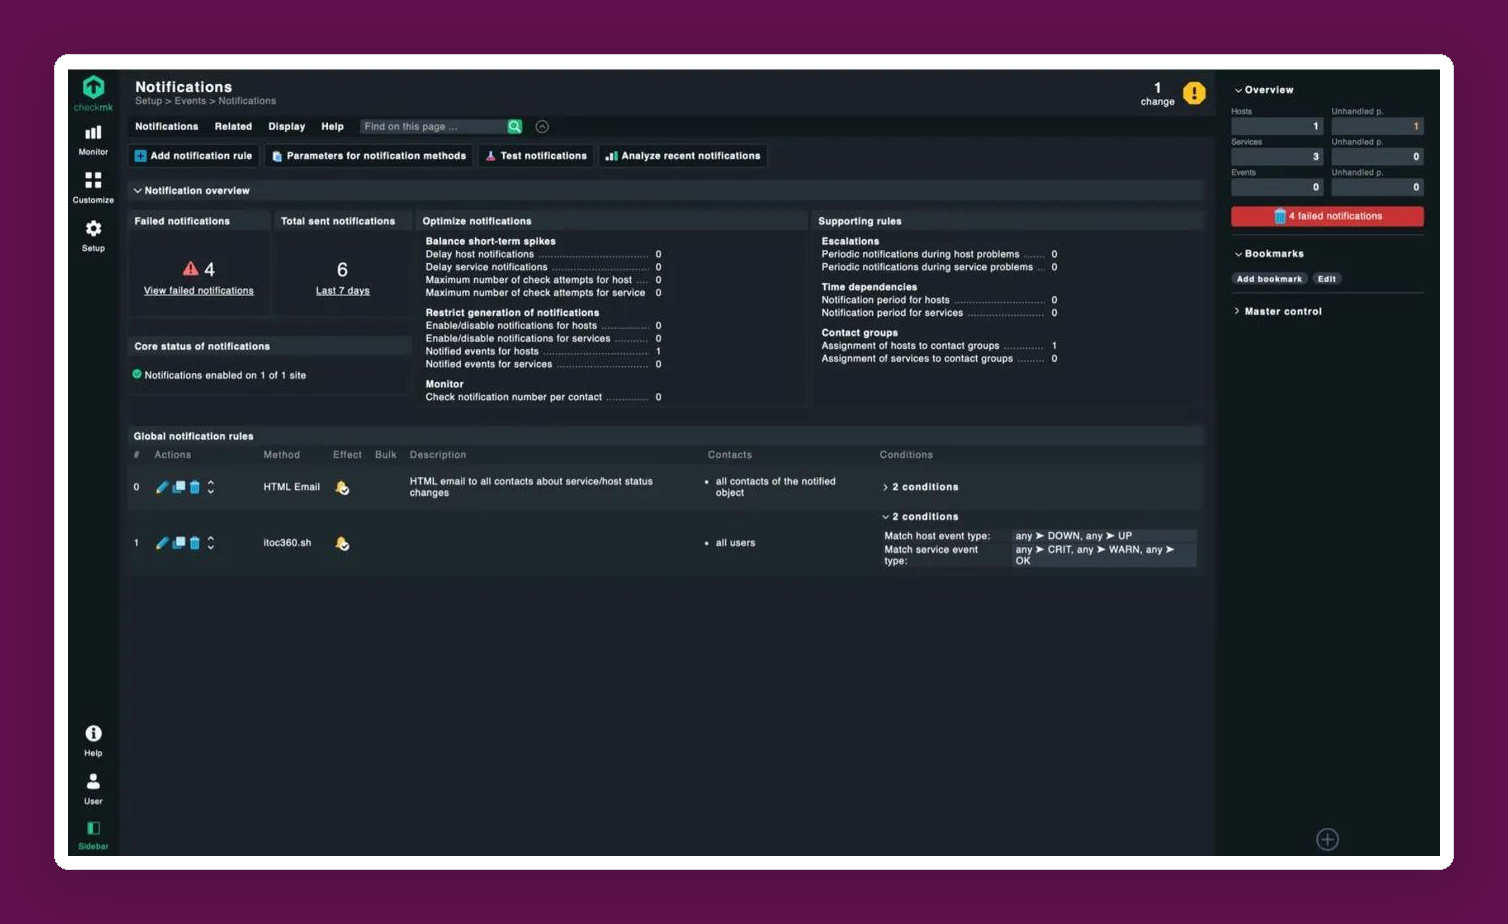
1. In Checkmk, go to **Setup → Events → Notifications**.
2. Click **Add notification rule**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FJ4OrqwTLEQacQTSs5cOp%2FWhatsApp%20Image%202026-04-07%20at%2001.36.24.png?alt=media&amp;token=c19996b5-65d8-4055-a2b6-bb68305fac99" alt=""><figcaption></figcaption></figure>

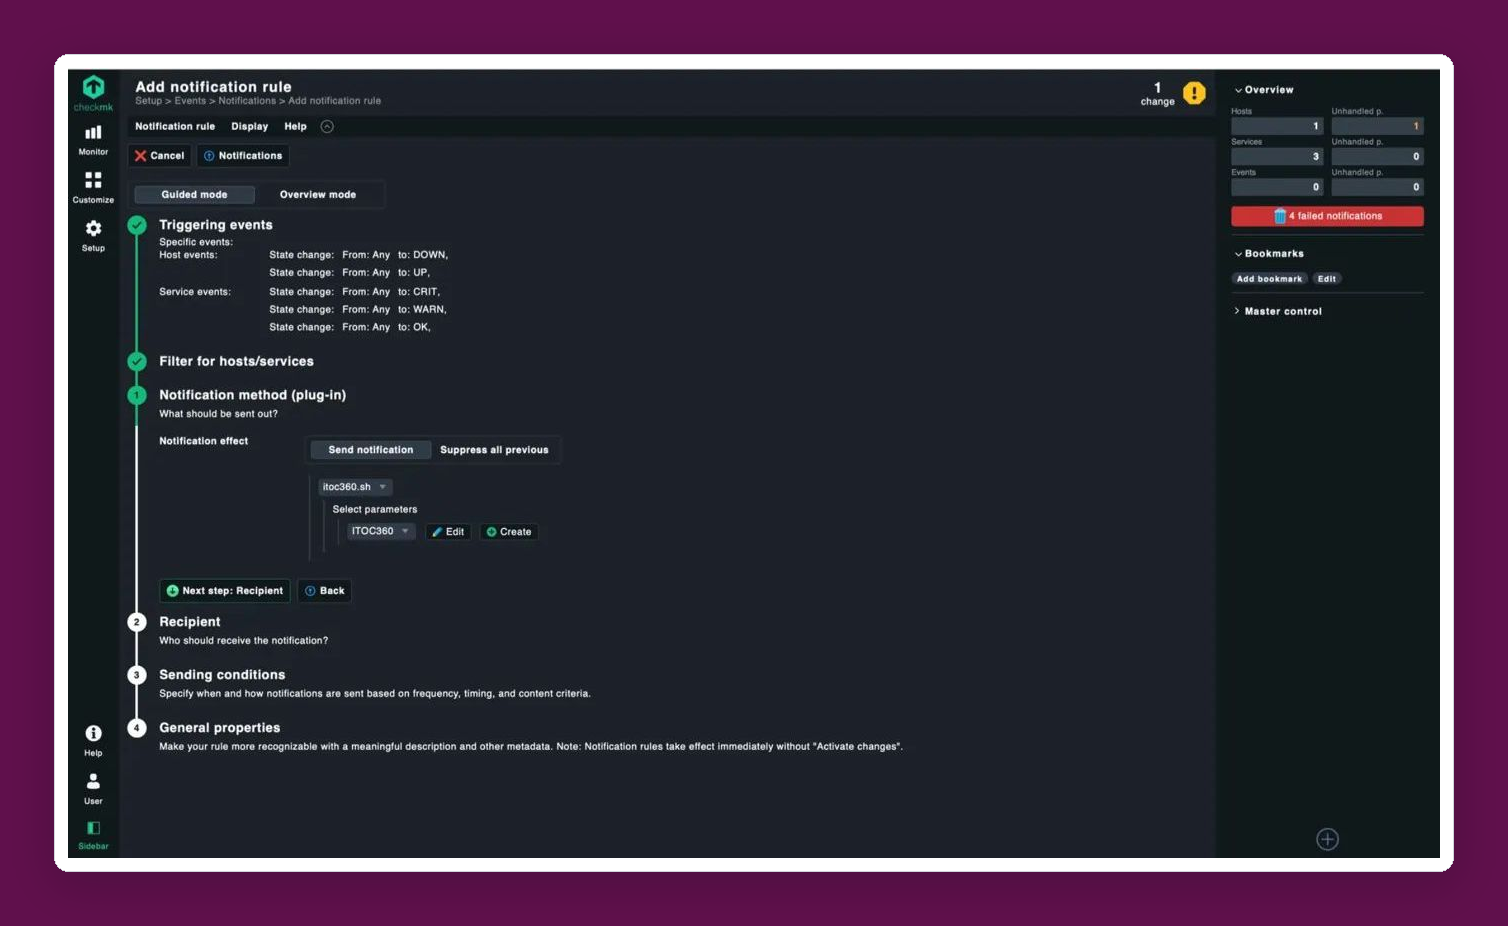
3. In **Triggering events**, leave the defaults (host DOWN/UP, service CRIT/WARN/OK).
4. In **Notification method (plug-in)**, select `itoc360.sh` from the dropdown.
5. Click **Create** next to the parameters field.
6. In the **New itoc360.sh parameter** dialog:
   * **Description:** Enter a name (e.g. `ITOC360`)
   * **Parameters:** Paste your ITOC360 token copied from Step 1
   * Click **Save**
7. Select the saved parameter from the dropdown.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FHnfmZyvGxaWJH2w6HlSx%2FWhatsApp%20Image%202026-04-07%20at%2001.37.21.png?alt=media&amp;token=dbdcb884-3cce-43e6-8d30-a25b73334932" alt=""><figcaption></figcaption></figure>

8. In **Recipient**, select **All users** or the specific users you want to notify.
9. Click through the remaining steps and save the rule.

#### Step 4: Test the Integration

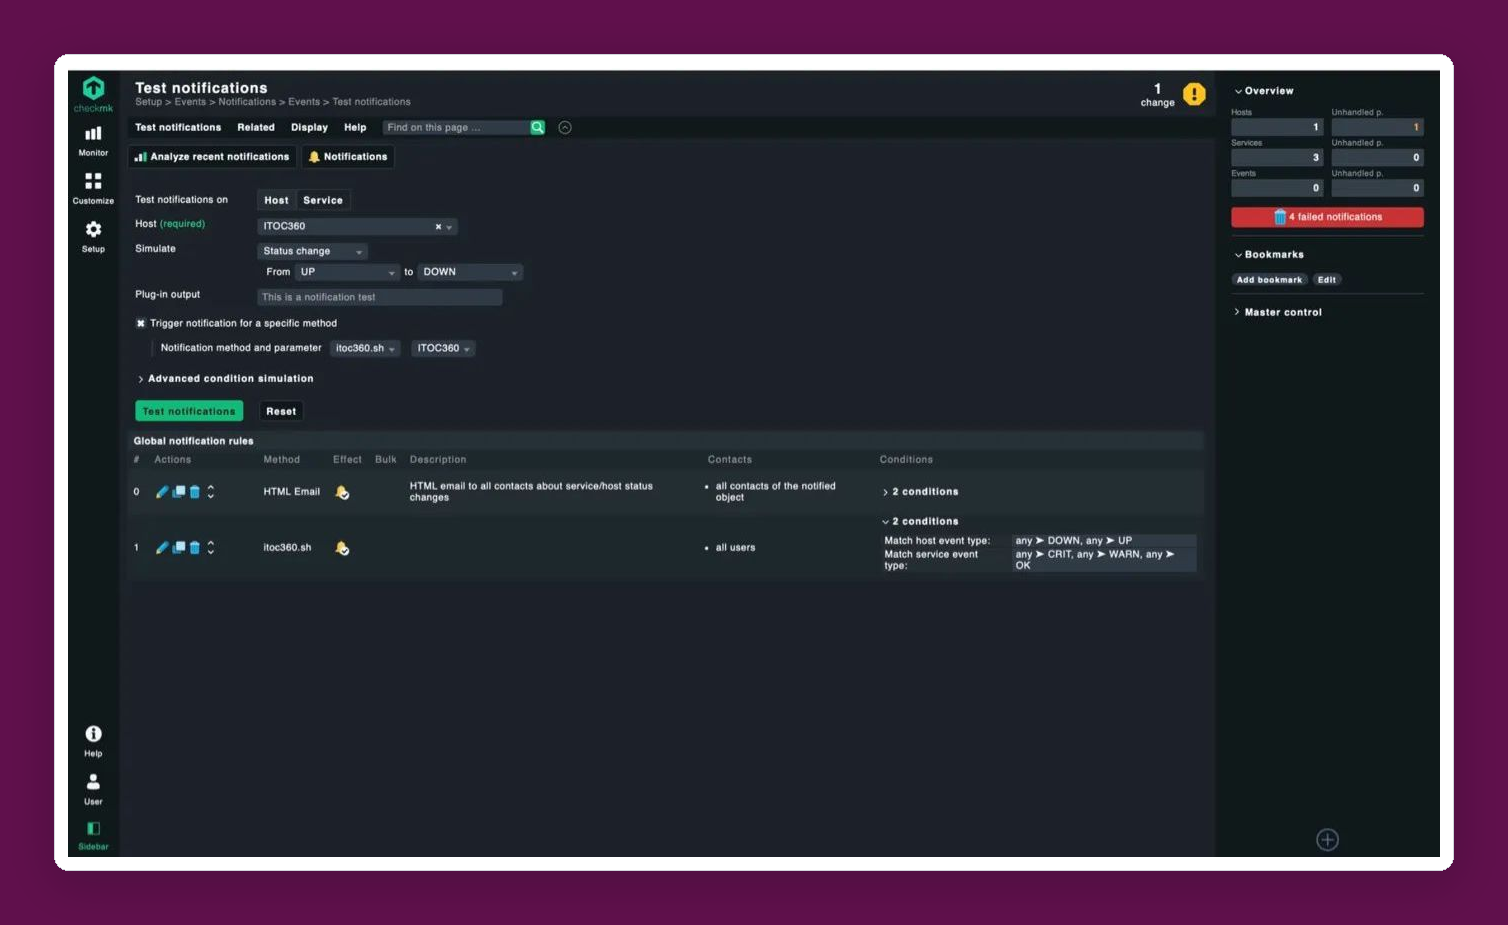
1. Go to **Setup → Events → Notifications → Test notifications**.
2. Select a **Host** from your monitored devices.
3. Set **Simulate** to **Status change → From UP to DOWN**.
4. Check **Trigger notification for a specific method** and select `itoc360.sh` with your parameter.
5. Click **Test notifications**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FdhrRJI9ZLGTBS1PyvToo%2FWhatsApp%20Image%202026-04-07%20at%2001.37.10.png?alt=media&amp;token=170c3c51-a098-44d7-b837-a4cd1c36f920" alt=""><figcaption></figcaption></figure>

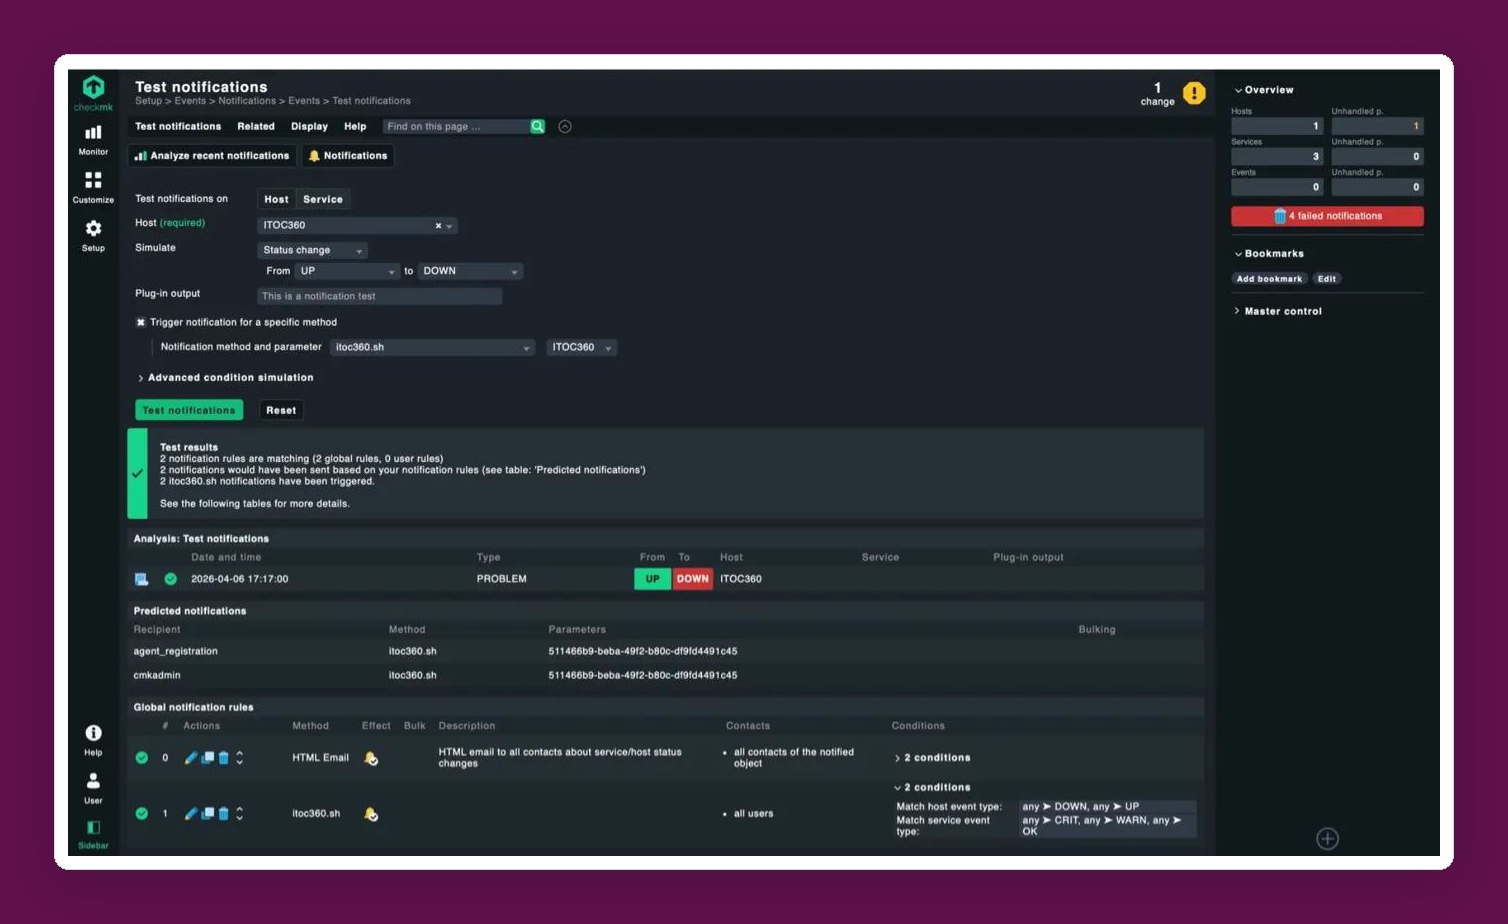
6. A green **Test results** box will confirm that the notifications were triggered.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fm5hrdYmml9sDUt0KUkSv%2FWhatsApp%20Image%202026-04-07%20at%2001.36.54.png?alt=media&amp;token=8143eb50-7757-45f0-9ccf-dfe0eb9a4b00" alt=""><figcaption></figcaption></figure>

7. Log in to ITOC360 and go to **Alerts** to verify the alert was received.


# Instana Integration

IBM [Instana](https://www.ibm.com/products/instana) is a fully automated observability platform built for cloud-native environments. It continuously monitors applications, infrastructure, and services in real time, surfacing issues before they affect users. This integration lets Instana push its alerts directly into ITOC360 via a generic webhook, so your on-call team gets notified through a single pane of glass regardless of where the issue originated.

### In Instana

#### Creating an alert channel

Navigate to **Settings** from the left sidebar, then open **Global settings** and go to **Events & alerts → Alert channels**. Click **Add alert channel** in the top right corner.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fx5rsfbx1FnxGlDMWtGsI%2Fimage%20(133).png?alt=media&amp;token=a8e7fdaf-125d-4fda-a75f-45aadaa96634" alt=""><figcaption></figcaption></figure>

In the dialog that appears, select **Generic webhook** from the list of unidirectional channel types and click **Add alert channel**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FbF1JZH3kbdXIX1Nt5kJM%2Fimage%20(135).png?alt=media&amp;token=e6fc3c94-bc8b-4247-ad19-3cc112bc7e8c" alt=""><figcaption></figcaption></figure>

Give the channel a name, paste your ITOC360 webhook URL into the **Webhook URLs** field, and click **Test channel** to verify the connection. You should see a confirmation that the test alert was delivered successfully.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FWbgz0xKYLULqiWgvYxci%2Fimage%20(136).png?alt=media&amp;token=28e0725d-b6ae-47d6-9fce-ea48edc0c3f1" alt=""><figcaption></figcaption></figure>

Your webhook URL follows this format:

```
https://api.itoc360.app/functions/v1/events?token=<x-itoc360-token>
```

Click **Create** to save the channel.

#### Creating a Smart Alert

With the alert channel in place, head to **Events** in the left sidebar and switch to the **Smart Alerts** tab. Click **Create Smart Alert**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fm9xrYUJjm2LpLY4m5yRs%2Fimage%20(137).png?alt=media&amp;token=f3cd7f56-c153-423b-af32-c30e6eaf69dd" alt=""><figcaption></figcaption></figure>

In the trigger section, select **Erroneous calls** as the blueprint. This instructs Instana to fire an alert whenever the error rate on your monitored services exceeds the threshold you define.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fefd67mkvC9f2IpidPdRP%2Fimage%20(138).png?alt=media&amp;token=bb693ba4-ee89-4623-be1c-d6b203926de7" alt=""><figcaption></figcaption></figure>

On the scope step, leave the defaults as they are — alerts will be scoped per application perspective across inbound calls.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FnaxcNdQdWXpWIqmn15qj%2Fimage%20(139).png?alt=media&amp;token=bb82e6a6-9116-4831-9c72-3f811e1dad01" alt=""><figcaption></figcaption></figure>

On the threshold step, check **Warning** and set the value to your desired error rate percentage. Any value above zero will cause Instana to fire as soon as errors appear, which is useful for testing the integration.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F576pEprAeVQ1muoACPPm%2Fimage%20(140).png?alt=media&amp;token=775b8c95-14de-41f9-8819-98094102cf6a" alt=""><figcaption></figcaption></figure>

Scroll down to the **Alert channels** section and click **Select alert channels**. Find the channel you created earlier, check it, and confirm the selection.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FynsGiAUuglp3WyCSZwFI%2Fimage%20(141).png?alt=media&amp;token=eb3aead5-371f-457d-9389-914557fc357b" alt=""><figcaption></figcaption></figure>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FYfuj3Orl5XovWjHYhUh5%2Fimage%20(142).png?alt=media&amp;token=866ccac8-14ab-4481-ac58-3893a108bafd" alt=""><figcaption></figcaption></figure>

Click **Create** to save the Smart Alert. It will immediately appear in the Smart Alerts list with its triggering condition and enabled state.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F8mSdHvJHK0ejgeZ8EKjE%2Fimage%20(143).png?alt=media&amp;token=7caee443-09d8-43e6-a604-c9547d6b8a7e" alt=""><figcaption></figcaption></figure>

***

### In ITOC360

Go to **Sources**, click **Create Source**, and select **Instana** from the list. Copy the webhook URL shown on the source detail page and use it as the Webhook URL when configuring your alert channel in Instana, as described above.

itoc360 handles all Instana event types automatically. Issues and incidents trigger an alert when their state is `OPEN` and resolve it when the state reaches `CLOSED`. Presence events resolve when the entity comes back online. The severity field maps directly to priority — a severity of `5` (Warning) becomes Medium, while `10` (Critical) becomes Critical. Events that carry no severity, such as change events, default to Medium priority.


# Manage Engine OpManager Integration

This guide walks you through integrating ManageEngine [OpManager](https://www.manageengine.com/network-monitoring/?network=g\&device=c\&keyword=opmanager\&campaignid=22722897346\&creative=760460347650\&matchtype=e\&adposition=\&placement=\&adgroup=181193681709\&targetid=kwd-314902078465\&gad_source=1\&gad_campaignid=22722897346\&gbraid=0AAAAAChplNAb6YKjYXDvX-PwCBaPAqMts\&gclid=Cj0KCQjwy_fOBhC6ARIsAHKFB7-iXS1vvWWjpwR4gX_Hn4ppGmqb0gxzKUrU3L_eCPDCxGRAuA9TTL4aAqA5EALw_wcB) with our alert management platform. OpManager delivers alert notifications through its **Notification Profile** system using the **Invoke a Webhook** profile type. When a device threshold is violated or a device becomes unreachable, OpManager sends an HTTP POST payload to the configured webhook URL. When the alarm clears (condition returns to normal), OpManager sends a separate payload with `severity: "Clear"` for recovery.

### Integration Flow

1. OpManager continuously monitors device health, performance metrics, and availability via SNMP/WMI/CLI.
2. When a threshold is violated or a device becomes unreachable, OpManager generates an alarm.
3. The Notification Profile evaluates its criteria (severity, category, device) and sends an HTTP POST webhook payload to the configured endpoint.
4. When the condition returns to normal, OpManager sends a **Clear** alarm using the same `alarm_id` for lifecycle correlation.

### Webhook Payload Schema

OpManager does **not** provide a predefined webhook payload format. A custom JSON structure must be manually configured inside the Notification Profile's body content using OpManager's built-in message variables.

Below is the recommended payload template to paste into the webhook body content:

```json
{
  "alarm_id": "$alarmid",
  "severity": "$stringseverity",
  "device_name": "$displayName",
  "ip_address": "$DeviceField(ipAddress)",
  "message": "$message",
  "category": "$category",
  "event_type": "$eventType",
  "entity": "$entity",
  "last_polled_value": "$lastPolledValue",
  "device_type": "$DeviceField(type)",
  "timestamp": "$strModTime"
}
```

#### Payload Fields

| Field               | Variable                  | Type   | Required | Description                                                      |
| ------------------- | ------------------------- | ------ | -------- | ---------------------------------------------------------------- |
| alarm\_id           | `$alarmid`                | string | Yes      | Unique alarm identifier for lifecycle correlation                |
| severity            | `$stringseverity`         | string | Yes      | Alarm severity level (Critical, Trouble, Attention, Clear, etc.) |
| device\_name        | `$displayName`            | string | Yes      | Display name of the affected device                              |
| ip\_address         | `$DeviceField(ipAddress)` | string | No       | IP address of the affected device                                |
| message             | `$message`                | string | Yes      | Human-readable alarm description                                 |
| category            | `$category`               | string | Yes      | Alarm category (e.g., Server, Router, Switch, Firewall)          |
| event\_type         | `$eventType`              | string | Yes      | Event type indicating trigger or recovery (see table below)      |
| entity              | `$entity`                 | string | No       | Specific monitored entity (e.g., CPU, Disk, Interface name)      |
| last\_polled\_value | `$lastPolledValue`        | string | No       | Last polled metric value that triggered the alarm                |
| device\_type        | `$DeviceField(type)`      | string | No       | Device type classification in OpManager                          |
| timestamp           | `$strModTime`             | string | Yes      | Alarm timestamp in OpManager's configured format                 |

> **Note:** All values are resolved at the time OpManager sends the webhook. When using **Test Action** in the Notification Profile, message variables will be sent as literal strings (e.g., `$message`) since there is no real alarm context.

***

### Severity Mapping

| OpManager Severity | Platform Status | Description                                    |
| ------------------ | --------------- | ---------------------------------------------- |
| Critical           | PROBLEM         | Major outage or serious service degradation    |
| Trouble            | PROBLEM         | Performance degradation requiring action       |
| Attention          | PROBLEM         | Warning condition close to threshold violation |
| Service Down       | PROBLEM         | Device or service is completely unreachable    |
| Clear              | RECOVERY        | Alarm has recovered, service is back to normal |

> **Note:** The `Unmanaged` device status does not generate webhook alarms. A device must be in `Managed` state for alarms to be raised. Reference: [Alarm Severity Levels in OpManager](https://pitstop.manageengine.com/portal/en/kb/articles/alarm-severity-levels-in-opmanager)

### Event Types

OpManager uses the `eventType` field to indicate what triggered the alarm:

| Event Type     | Direction | Description                                            |
| -------------- | --------- | ------------------------------------------------------ |
| Threshold Down | Trigger   | A performance metric exceeded its configured threshold |
| Threshold Up   | Recovery  | A performance metric returned to normal                |
| Device Down    | Trigger   | Device stopped responding (availability failure)       |
| Device Up      | Recovery  | Device is back online and responding                   |

### Alert Payload Examples

#### Performance Alarm — CPU Utilization

**Raised (Critical)**

This payload is sent when a performance metric (e.g., CPU utilization) exceeds its configured threshold.

```json
{
  "alarm_id": "2",
  "severity": "Critical",
  "device_name": "prod-web-server-01",
  "ip_address": "10.0.1.40",
  "message": "CPU Utilization is 100%, threshold value for this monitor is 90%: Top 3 Processes:-stress - 99.8%;stress - 99.8%;stress - 99.8%",
  "category": "Server",
  "event_type": "Threshold Down",
  "entity": "CPU Utilization",
  "last_polled_value": "100",
  "device_type": "Server",
  "timestamp": "27 Oct 2025 02:36:21 PM"
}
```

**Cleared**

This payload is sent when the CPU utilization returns below the threshold. The `severity` is `Clear` and the `event_type` is `Threshold Up`.

```json
{
  "alarm_id": "2",
  "severity": "Clear",
  "device_name": "prod-web-server-01",
  "ip_address": "10.0.1.40",
  "message": "CPU Utilization is now back to normal, current value is 0%",
  "category": "Server",
  "event_type": "Threshold Up",
  "entity": "CPU Utilization",
  "last_polled_value": "0",
  "device_type": "Server",
  "timestamp": "27 Oct 2025 02:37:20 PM"
}
```

#### Availability Alarm — Device Down

**Raised (Attention)**

This payload is sent when a device stops responding to health checks.

```json
{
  "alarm_id": "1",
  "severity": "Attention",
  "device_name": "prod-web-server-01",
  "ip_address": "10.0.1.40",
  "message": "Device not responding: Probably down or busy",
  "category": "Server",
  "event_type": "Device Down",
  "entity": "",
  "last_polled_value": "",
  "device_type": "Server",
  "timestamp": "27 Oct 2025 02:43:59 PM"
}
```

**Cleared**

This payload is sent when the device comes back online.

```json
{
  "alarm_id": "1",
  "severity": "Clear",
  "device_name": "prod-web-server-01",
  "ip_address": "10.0.1.40",
  "message": "Device Active and Responding",
  "category": "Server",
  "event_type": "Device Up",
  "entity": "",
  "last_polled_value": "",
  "device_type": "Server",
  "timestamp": "27 Oct 2025 02:53:54 PM"
}
```

### Installation & Configuration

#### Step 1: Create an Alert Source in the Platform

1. Log in to the alert management platform.
2. Navigate to **Integrations** → **Add Integration**.
3. Select **OpManager** as the provider.
4. Name the integration (e.g., `Production OpManager Alerts`).
5. Save and copy the generated **Webhook URL** and **Token**.

#### Step 2: Create a Webhook Notification Profile in OpManager

1. Log in to your **OpManager** web console.
2. Navigate to **Settings** → **Notifications** → **Notification Profiles**.
3. Click **Add** to create a new notification profile.
4. Select **Invoke a Webhook** as the profile type.

#### Step 3: Configure the Webhook Settings

1. Set the following fields:
   * **HTTP Method**: `POST`
   * **Hook URL**: <https://api.itoc360.app/functions/v1/events>
   * **Data Type**: `raw`
   * **Payload Type**: `JSON`
   * **Content-Type**: `application/json`
2. Add a custom HTTP header for authentication:
   * **Header Name**: `x-itoc-360`
   * **Header Value**: `Bearer <your-token>`
3. In the **Body Content** field, paste the following JSON payload template:

```json
{
  "alarm_id": "$alarmid",
  "severity": "$stringseverity",
  "device_name": "$displayName",
  "ip_address": "$DeviceField(ipAddress)",
  "message": "$message",
  "category": "$category",
  "event_type": "$eventType",
  "entity": "$entity",
  "last_polled_value": "$lastPolledValue",
  "device_type": "$DeviceField(type)",
  "timestamp": "$strModTime"
}
```

4. Click **Next**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FnLih8fQ3f2P7aNWUJkRy%2Fimage%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=cb9c780c-fad4-45d7-b9a0-517029c79406" alt=""><figcaption></figcaption></figure>

#### Step 4: Configure Notification Criteria

1. Select the alarm criteria that should trigger this webhook:
   * ✅ **Device Down alarms**
   * ✅ **Threshold-based alarms** (performance monitors)
   * ✅ Any other relevant alarm categories
2. **⚠️ CRITICAL:** Check the **"Notify when the alarm is cleared"** checkbox. Without this, recovery (Clear) payloads will not be sent and alerts will never auto-resolve.<br>
3. Select all **Severity** levels you want to be notified for:
   * ✅ Critical
   * ✅ Trouble
   * ✅ Attention
   * ✅ Service Down
4. Click **Next**.![](https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FlfhWM6DP5vdjszeaC3wT%2Fimage%20\(2\)%20\(1\)%20\(1\)%20\(1\)%20\(1\)%20\(1\)%20\(1\)%20\(1\)%20\(1\)%20\(1\)%20\(1\)%20\(1\)%20\(1\)%20\(1\)%20\(1\)%20\(1\)%20\(1\)%20\(1\).png?alt=media\&token=b1ff11bf-0d67-4a63-8aee-cbcbe09e8b0f)<br>

   <figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fi5YzEBVqR1xXugAhoPwj%2Fimage%20(2)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=a5ab09f4-962d-47e7-a3ee-276ad41b813d" alt=""><figcaption></figcaption></figure>

#### Step 5: Associate Devices

1. Under **Available Devices**, select the devices you want to monitor with this webhook.
2. Move them to the **Selected Devices** column using the right arrow.
3. Click **Next**.

> **Tip:** You can also associate the profile with **Device Groups** or **Interface Groups** instead of individual devices.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FxNl3bQEAZt18lMIbgPUc%2Fimage%20(3)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=9d8966d0-0228-4452-bd51-8bf10bcaaf37" alt=""><figcaption></figcaption></figure>

#### Step 6: Configure Time Window

1. Choose when this profile should be active:
   * **Apply this profile 24x7** (recommended for production monitoring)
   * Or specify a custom time window (e.g., business hours only)
2. Click **Next**.\ <br>

   <figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FG5Tz51X443lJx3xqTAP6%2Fimage%20(4)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=30c77218-189d-4c2a-ae3e-21fdf7b4cae2" alt=""><figcaption></figcaption></figure>

#### Step 7: Save and Test

1. Enter a **Profile Name** (e.g., `OnCall Platform Webhook`).
2. Click **Test Action** to verify the webhook is reachable.

> **Note:** When using Test Action, OpManager sends the payload with message variables as literal strings (e.g., `$message` instead of the actual alarm message). This is expected behavior — variables are only resolved during real alarm events.

3. Click **Save** to enable the notification profile.\ <br>

   <figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FLk5BInsSW8yxwLUrKD0r%2Fimage%20(5)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=328a59ff-2d31-446b-a58e-8a06265d1c89" alt=""><figcaption></figcaption></figure>

### Testing

#### Trigger a Performance Alarm

To validate the integration, trigger a test alarm:

1. Force a CPU or memory threshold breach on a monitored device (e.g., run a stress test).
2. Verify that a webhook payload with `severity: "Critical"` (or `"Trouble"`) and `event_type: "Threshold Down"` is received at your platform endpoint.

#### Trigger a Device Down Alarm

1. Disconnect a monitored device from the network or stop responding to SNMP/ICMP.
2. Verify that a webhook payload with `event_type: "Device Down"` is received.

#### Verify Recovery (Clear)

1. Resolve the threshold breach or bring the device back online.
2. Verify that a webhook payload with `severity: "Clear"` and the matching `alarm_id` is received.

#### Verification Checklist

Verify that:

1. A **raised** alarm payload is received by the platform (status: PROBLEM).
2. The `alarm_id`, `severity`, `device_name`, and `message` fields are populated correctly.
3. A **Clear** alarm payload is received after recovery (status: RECOVERY).
4. The `alarm_id` matches between raised and cleared payloads for proper lifecycle correlation.
5. The `event_type` correctly reflects the alarm type (`Threshold Down`/`Threshold Up`, `Device Down`/`Device Up`).

#### Webhook Delivery Logs

To check delivery status within OpManager:

Navigate to **Settings** → **Notifications** → **Notification Profiles** → Click the **View Report** icon (in the Actions column) for your webhook profile.

### Troubleshooting

| Issue                          | Possible Cause                              | Resolution                                                                                       |
| ------------------------------ | ------------------------------------------- | ------------------------------------------------------------------------------------------------ |
| No alerts received             | Webhook profile not enabled or not assigned | Verify the profile is saved and associated with the correct devices                              |
| No alerts received             | Criteria not matching                       | Check that the correct alarm types and severity levels are selected in the notification criteria |
| Clear/recovery alerts missing  | "Notify when alarm is cleared" not checked  | Edit the notification profile and enable the **Notify when the alarm is cleared** checkbox       |
| Incorrect payload structure    | Missing or incorrect variables              | Apply the exact payload template provided in this document with correct OpManager variables      |
| Authentication error (401/403) | Authorization header missing or incorrect   | Verify the `Authorization: Bearer <token>` header is set correctly in the webhook profile        |
| No alarms during downtime      | Device state is Unmanaged                   | Change the device back to **Managed** state in OpManager                                         |
| Variables sent as literal text | Using Test Action                           | This is expected — variables are only resolved during real alarm events, not during test actions |
| Delayed notifications          | Time window restricting delivery            | Verify the notification profile is set to **Apply this profile 24x7** or adjust the time window  |
| Duplicate notifications        | Multiple profiles matching same device      | Review notification profiles and ensure each device is assigned to only one webhook profile      |

### FAQ

**Are alerts automatically resolved?**

Yes, when an alarm clears in OpManager, a payload with `severity: "Clear"` and the same `alarm_id` is sent automatically, provided the **"Notify when the alarm is cleared"** option is enabled in the notification profile.

**Can I monitor different device groups with different webhook endpoints?**

Yes, create separate webhook Notification Profiles for each group and associate them with the appropriate devices or device groups.

**Which operating systems does OpManager support?**

OpManager **server** (the management console) runs on Windows and Linux. However, OpManager can **monitor** devices running any operating system — including macOS, Windows, Linux, and network appliances — via SNMP, WMI, SSH/CLI, and other protocols.

**What happens if the webhook endpoint is unreachable?**

OpManager will log a delivery failure. You can check the delivery status in the Notification Profile's View Report section. OpManager does not retry failed webhook deliveries by default, so ensure your endpoint is highly available.


# Netdata Integration

### Overview

[Netdata](https://www.netdata.cloud/) is an open-source, real-time infrastructure monitoring tool that tracks thousands of metrics per second with per-second resolution across servers, containers, databases, and applications.

This integration listens for alerts dispatched by the Netdata Agent via its **custom webhook notification** method and turns them into actionable alerts on the platform. Alerts are automatically resolved when Netdata sends a `CLEAR` notification for the same alarm.

### Integration Flow

1. The Netdata Agent continuously evaluates health rules against the metrics it collects.
2. When an alarm's state transitions (for example `CLEAR → WARNING`, `WARNING → CRITICAL`, or `CRITICAL → CLEAR`), the Agent invokes `alarm-notify.sh`.
3. `alarm-notify.sh` calls the `custom_sender()` function that you configure in `health_alarm_notify.conf`.
4. That function builds a JSON payload from the alarm context and posts it to the platform endpoint.
5. The platform classifies the event by `status` — any value other than `CLEAR` opens or updates an alert, and `CLEAR`resolves it.

### Webhook Payload Schema

```json
{
  "name": "string",
  "chart": "string",
  "family": "string",
  "status": "WARNING | CRITICAL | CLEAR | UNDEFINED | UNINITIALIZED",
  "old_status": "string",
  "value": "string",
  "old_value": "string",
  "value_string": "string",
  "old_value_string": "string",
  "units": "string",
  "info": "string",
  "when": "unix timestamp",
  "host": "string",
  "unique_id": "string",
  "alarm_id": "string",
  "event_id": "string",
  "duration": "string",
  "non_clear_duration": "string",
  "classification": "string",
  "component": "string",
  "type": "string",
  "severity": "string",
  "calc_expression": "string",
  "total_warnings": "string",
  "total_critical": "string",
  "src": "string",
  "goto_url": "string",
  "image_url": "string"
}
```

### Setup

#### Step 1 — Create an Alert Source on the Platform

1. Navigate to **Sources → Add Source**.
2. Search for **Netdata** and select it.
3. Give the source a name and click **Save**.
4. Copy the **ITOC360 URL** and **Token** — you will need them in Step 3. The full webhook URL has the form:

```
https://api.itoc360.app/functions/v1/events?token=<x-itoc360-token>
```

#### Step 2 — Access the Netdata Configuration

Netdata's notification settings live in `health_alarm_notify.conf`. How you reach this file depends on how you run Netdata.

**If Netdata runs in Docker:**

Copy the default configuration out of the container so you can edit it on your host:

```bash
docker exec netdata cat /usr/lib/netdata/conf.d/health_alarm_notify.conf > ./health_alarm_notify.conf
```

Open the file in your preferred editor. You will push the edited file back into the container in Step 4.

**If Netdata runs on a host (apt/yum install):**

Use the `edit-config` helper so the file ends up in the right location:

```bash
cd /etc/netdata 2>/dev/null || cd /opt/netdata/etc/netdata
sudo ./edit-config health_alarm_notify.conf
```

#### Step 3 — Add the Custom Sender Block

Append the following block to the **end** of `health_alarm_notify.conf`. Replace the webhook URL with the one you copied in Step 1.

```bash
#------------------------------------------------------------------------------
# itoc360 custom webhook notifications
#------------------------------------------------------------------------------

SEND_CUSTOM="YES"
DEFAULT_RECIPIENT_CUSTOM="sysadmin"

custom_sender() {
    local webhook_url="https://api.itoc360.app/functions/v1/events?token=<x-itoc360-token>"

    local payload=$(cat <<EOF
{
  "name": "${name}",
  "chart": "${chart}",
  "family": "${family}",
  "status": "${status}",
  "old_status": "${old_status}",
  "value": "${value}",
  "old_value": "${old_value}",
  "src": "${src}",
  "duration": "${duration}",
  "non_clear_duration": "${non_clear_duration}",
  "units": "${units}",
  "info": "${info}",
  "when": "${when}",
  "host": "${host}",
  "unique_id": "${unique_id}",
  "alarm_id": "${alarm_id}",
  "event_id": "${event_id}",
  "calc_expression": "${calc_expression}",
  "total_warnings": "${total_warnings}",
  "total_critical": "${total_critical}",
  "classification": "${classification}",
  "component": "${component}",
  "type": "${type}",
  "severity": "${severity}",
  "value_string": "${value_string}",
  "old_value_string": "${old_value_string}",
  "image_url": "${image_url}",
  "goto_url": "${goto_url}"
}
EOF
)

    httpcode=$(docurl \
        --request POST \
        --header "Content-Type: application/json" \
        --data "${payload}" \
        "${webhook_url}")

    if [ "${httpcode}" = "200" ] || [ "${httpcode}" = "201" ] || [ "${httpcode}" = "204" ]; then
        info "sent custom webhook notification for: ${host} ${chart}.${name} is ${status}"
        sent=$((sent + 1))
    else
        error "failed to send custom webhook notification for: ${host} ${chart}.${name} is ${status}, http code ${httpcode}"
    fi

    return 0
}
```

`SEND_CUSTOM="YES"` turns on the custom notification method, and `DEFAULT_RECIPIENT_CUSTOM="sysadmin"` ensures alerts routed to the `sysadmin` role reach this integration. Adjust the recipient role if your setup routes alerts elsewhere.

Save the file.

#### Step 4 — Apply the Configuration

**If Netdata runs in Docker:**

```bash
docker cp ./health_alarm_notify.conf netdata:/etc/netdata/health_alarm_notify.conf
docker exec netdata chown netdata:netdata /etc/netdata/health_alarm_notify.conf
docker restart netdata
```

**If Netdata runs on a host:**

Changes made via `edit-config` take effect on the next alarm evaluation, but a restart forces a clean reload:

```bash
sudo systemctl restart netdata
```

#### Step 5 — Verify the Integration

Netdata ships with a built-in test command that dispatches three sample alarms in sequence (`WARNING`, `CRITICAL`, and `CLEAR`):

```bash
# Docker
docker exec -u netdata netdata bash -c \
  'export NETDATA_ALARM_NOTIFY_DEBUG=1 && /usr/libexec/netdata/plugins.d/alarm-notify.sh test'

# Host install
sudo su -s /bin/bash netdata
export NETDATA_ALARM_NOTIFY_DEBUG=1
/usr/libexec/netdata/plugins.d/alarm-notify.sh test
```

You should see three `# OK` lines in the output, one per alarm. On the platform, under the source you created in Step 1, a single alert should open on the `WARNING` event, stay open through the `CRITICAL` event, and automatically resolve when the `CLEAR` event arrives.

### Sample Payloads

The following payloads were captured during integration testing.

**ALERT — WARNING state:**

```json
{
  "name": "test_alarm",
  "chart": "test.chart",
  "family": "",
  "status": "WARNING",
  "old_status": "CLEAR",
  "value": "100",
  "old_value": "90",
  "src": "/usr/libexec/netdata/plugins.d/alarm-notify.sh",
  "duration": "1",
  "non_clear_duration": "1",
  "units": "units",
  "info": "this is a test alarm to verify notifications work",
  "when": "1776694259",
  "host": "3b60a2cac47d",
  "unique_id": "1",
  "alarm_id": "1",
  "event_id": "1",
  "severity": "WARNING",
  "classification": "Test",
  "value_string": "new value",
  "old_value_string": "old value",
  "goto_url": "https://registry.my-netdata.io/registry-alert-redirect.html?host=3b60a2cac47d&chart=test.chart&alarm=test_alarm&alarm_status=WARNING"
}
```

**RESOLVE — CLEAR state:**

```json
{
  "name": "test_alarm",
  "chart": "test.chart",
  "family": "",
  "status": "CLEAR",
  "old_status": "CRITICAL",
  "value": "100",
  "old_value": "90",
  "src": "/usr/libexec/netdata/plugins.d/alarm-notify.sh",
  "duration": "1",
  "non_clear_duration": "3",
  "units": "units",
  "info": "this is a test alarm to verify notifications work",
  "when": "1776694259",
  "host": "3b60a2cac47d",
  "unique_id": "1",
  "alarm_id": "1",
  "event_id": "3",
  "severity": "Recovered from CRITICAL",
  "classification": "Test",
  "value_string": "new value",
  "old_value_string": "old value",
  "goto_url": "https://registry.my-netdata.io/registry-alert-redirect.html?host=3b60a2cac47d&chart=test.chart&alarm=test_alarm&alarm_status=CLEAR"
}
```

### Field Mapping Reference

| Payload Field                           | Description                                                                                      |
| --------------------------------------- | ------------------------------------------------------------------------------------------------ |
| `status`                                | Alarm state — any value other than `CLEAR` opens or updates an alert, `CLEAR` resolves it        |
| `host`                                  | Hostname of the Netdata Agent — combined with `alarm_id` and `name` to fingerprint the alert     |
| `alarm_id`                              | Stable identifier for the alarm across state transitions                                         |
| `name`                                  | Name of the alarm rule — shown in the alert title                                                |
| `chart`                                 | Chart the alarm is attached to — shown in the alert title                                        |
| `info`                                  | Human-readable description of why the alarm fired                                                |
| `value` / `units`                       | Current metric value and its unit of measurement                                                 |
| `old_value` / `old_status`              | Previous metric value and alarm state                                                            |
| `severity`                              | Descriptive severity string, which may include escalation context (e.g. `Escalated to CRITICAL`) |
| `classification` / `component` / `type` | Alarm taxonomy fields set in the alarm definition                                                |
| `when`                                  | Unix timestamp of the state change                                                               |
| `duration` / `non_clear_duration`       | How long the alarm has been in its current state, and since it was last clear                    |
| `calc_expression`                       | Expression that was evaluated to produce the current value                                       |
| `total_warnings` / `total_critical`     | Total warning and critical alarms currently active on the host                                   |
| `goto_url`                              | Direct link to the alarm in the Netdata dashboard                                                |
| `unique_id` / `event_id`                | Identifiers used internally by Netdata for this specific transition                              |

### Priority Mapping

The platform maps Netdata's `status` field to an internal priority level.

| Netdata `status` | Platform Priority                                           |
| ---------------- | ----------------------------------------------------------- |
| `CRITICAL`       | CRITICAL                                                    |
| `WARNING`        | MEDIUM                                                      |
| `UNDEFINED`      | LOW                                                         |
| `UNINITIALIZED`  | LOW                                                         |
| `CLEAR`          | LOW (this event resolves the alert rather than opening one) |

The `severity` field in the payload (for example `Escalated to CRITICAL` or `Recovered from CRITICAL`) is a human-readable description that Netdata composes at notification time. The platform does not use it for priority routing — `status` is the authoritative field.

### RESOLVE Detection

The platform resolves an alert when the Netdata Agent sends a payload with `"status": "CLEAR"`. This is the standard notification that `alarm-notify.sh` emits when an alarm's condition no longer holds.

The resolve event is matched to the original alert using a fingerprint derived from `host`, `alarm_id`, and `name`. As long as those three fields stay the same across the firing and resolving notifications — which is the default Netdata behavior — the fingerprint will match and the alert will be closed.

### Troubleshooting

**No payload arrives on the platform after a test:**

Check the Netdata error log for delivery failures:

```bash
# Docker
docker exec netdata tail -50 /var/log/netdata/error.log

# Host
sudo tail -50 /var/log/netdata/error.log
```

Look for `failed to send custom webhook notification` lines — they include the HTTP status code returned by the platform endpoint.

**Test runs but no `# OK` for the custom sender:**

Confirm the configuration was reloaded. For Docker, make sure you ran `docker restart netdata` after copying the file in. For host installs, confirm `SEND_CUSTOM="YES"` appears in the active file and that the file belongs to the `netdata` user:

```bash
sudo ls -la /etc/netdata/health_alarm_notify.conf
```

**Alerts are created but never resolve:**

The most common cause is a custom alarm that does not transition back to `CLEAR` cleanly — for example, if the alarm rule is deleted before the condition recovers. Check the Netdata dashboard's alerts view to confirm the alarm itself is actually clearing.


# PRTG Network Monitor Integration

[PRTG Network Monitor](https://www.paessler.com/prtg) is a network monitoring tool by Paessler AG. It watches servers, routers, switches, bandwidth, and disk usage across your infrastructure.

PRTG connects to ITOC360 through its built-in **Execute HTTP Action** notification method, which fires a POST request whenever a sensor changes state. ITOC360 handles the rest — validation, deduplication, priority mapping, and escalation.

> **Note:** PRTG does not send JSON. It sends `application/x-www-form-urlencoded`, the same format used by classic HTML forms. It also cannot set a custom `Authorization` header, so the source token goes in the URL as a query parameter. This is a PRTG limitation and ITOC360 handles it without any extra configuration.

### Integration Flow

```
PRTG Sensor State Change
│
│ Notification Trigger fires
▼
Execute HTTP Action
│
│ POST application/x-www-form-urlencoded
│ URL: /functions/v1/events?token=<source-token>
▼
ITOC360 Webhook Endpoint
│
│ URL-encoded body parsed → schema validated
│ Fingerprint: md5(device::sensor::sensorid)
▼
Alert opened or resolved → On-call team notified
```

### Provider Configuration & Mapping

PRTG dumps everything into flat key-value pairs, so priority extraction is simple — we just read the `status` field directly. No JSONPath needed.

#### Priority Mapping Config

```json
{
  "priority": {
    "field": "$.status",
    "options": [
      { "value": "Down", "label": "Down" },
      { "value": "Warning", "label": "Warning" },
      { "value": "Unusual", "label": "Unusual" },
      { "value": "Up", "label": "Up" },
      { "value": "Paused", "label": "Paused" },
      { "value": "Unknown", "label": "Unknown" }
    ],
    "mapping": {
      "Down": "CRITICAL",
      "Warning": "MEDIUM",
      "Unusual": "LOW",
      "Up": "LOW",
      "Paused": "LOW",
      "Unknown": "LOW"
    }
  }
}
```

**Fingerprinting:** ITOC360 uses `md5(device::sensor::sensorid)` to tie alerts to their recovery events. Sensor identifiers never change in PRTG, so the resolve always lands on the right alert without any manual work.

#### Status → Priority

| PRTG Status | Platform Priority | What it means                                          |
| ----------- | ----------------- | ------------------------------------------------------ |
| Down        | CRITICAL          | Sensor failed, unreachable, or breached an error limit |
| Warning     | MEDIUM            | Crossed a warning threshold                            |
| Unusual     | LOW               | Behaviour looks off but not confirmed down             |
| Up          | LOW               | Sensor recovered — triggers a resolve                  |
| Paused      | LOW               | Monitoring paused intentionally                        |
| Unknown     | LOW               | Can't determine state                                  |

#### Event Type Mapping

| PRTG Status                                 | Event Type | Result                              |
| ------------------------------------------- | ---------- | ----------------------------------- |
| Down / Warning / Unusual / Paused / Unknown | ALERT      | Alert opened or updated             |
| Up / Recovering                             | RESOLVE    | Existing alert closed automatically |

### Setup Instructions

#### Step 1: Get Your Webhook URL

1. Log in to the platform and go to **Sources → Add Source**.
2. Choose **PRTG Network Monitor** and give the source a name.
3. Save it. You'll get a webhook URL that looks like this:

```
https://api.itoc360.app/functions/v1/events?token=<x-itoc360-token>
```

Copy this — you'll need it in the next step.

#### Step 2: Create a Notification Template in PRTG

1. Head to **Setup → Account Settings → Notification Templates**.<br>

   <figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F5PUaSqlwJX9g32Sizivo%2Fimage%20(3)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=e5c945bf-f236-4704-bb45-cba615a404e7" alt=""><figcaption></figcaption></figure>

2. Click **Add Notification Template** and give it a name like `OnCall Platform Webhook`.

3. In **Basic Settings**, a couple of things to set:

   | Setting                                      | Value                                          |
   | -------------------------------------------- | ---------------------------------------------- |
   | Monitoring Status                            | Started                                        |
   | Schedule                                     | None                                           |
   | Notification Handling during Scheduled Pause | Discard notifications during paused status     |
   | Notification Summarization                   | **Always notify immediately, never summarize** |

   > **Important:** Change **Notification Summarization** from its default. When PRTG summarizes notifications it merges several state changes into one message, and the `%sensorid` placeholder can arrive empty. Since `sensorid`is a required field, ITOC360 rejects the payload with `400 Invalid payload` and the alert is never opened.

   <figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F6nRSZy784aFnjeYd6Gr3%2F41_Ekran%20Resmi%202026-08-13%2017.12.22.png?alt=media&amp;token=98f0003d-4468-4a14-8430-8eaea469d666" alt=""><figcaption></figcaption></figure>

4. Scroll down, find **Execute HTTP Action**, and enable it.

5. Fill it in like this:

   <table><thead><tr><th>Field</th><th width="355.420166015625">Value</th></tr></thead><tbody><tr><td>URL</td><td><a href="https://api.itoc360.app/functions/v1/events">https://api.itoc360.app/functions/v1/events</a></td></tr><tr><td>HTTP Method</td><td>POST</td></tr><tr><td>HTTP Version</td><td>HTTP 1.1</td></tr><tr><td>SNI Handling</td><td>Do not send SNI (default)</td></tr></tbody></table>

6. In the **Payload** field, paste this:

```
sensorid=%sensorid&device=%device&sensor=%sensor&status=%status&message=%message&since=%since&lastup=%lastup&lastdown=%lastdown&downtime=%downtime&group=%group&probe=%probe&host=%host&linkdevice=%linkdevice&linksensor=%linksensor&deviceid=%deviceid
```

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FBUSPTqSSWgwdefSRu65g%2F42_Ekran%20Resmi%202026-08-13%2017.12.55.png?alt=media&amp;token=f3ad2825-c166-46c6-9029-e7d2ec6cc8fb" alt=""><figcaption></figcaption></figure>

7. Hit **Save**.

#### Step 3: Attach the Template to a Trigger

The notification template does nothing on its own — it needs to be connected to a trigger.

1. In the device tree, open the **Root** group (or whichever group you want to cover).
2. Go to the **Notification Triggers** tab.
3. Add three **State Triggers**, configured like this:

| Trigger | Row                                                     | Template        |
| ------- | ------------------------------------------------------- | --------------- |
| Down    | When sensor state is Down for at least **0 seconds**    | ITOC360 Webhook |
| Down    | Repeat every **5 minutes**                              | ITOC360 Webhook |
| Warning | When sensor state is Warning for at least **0 seconds** | ITOC360 Webhook |
| Up      | When sensor state is Up for at least **0 seconds**      | ITOC360 Webhook |

> **Watch the row you attach the template to.** Each State Trigger has three rows: entering the state, repeating while in the state, and *leaving* the state. Attach the template to the **entering** row. If you attach it to *"when sensor state is no longer X"*, the alert is never opened — only the recovery fires. Leave every other row set to **no notification**.

Enabling **repeat every 5 minutes** on the Down trigger is safe: repeated notifications carry the same fingerprint, so ITOC360 updates the existing alert instead of opening duplicates. Don't enable repeat on Warning or Up.

#### Step 4: Set Sensors to Down Immediately

By default PRTG holds a failing sensor in **Warning** for one scanning interval before marking it **Down**. The first webhook therefore arrives with `status=Warning` and opens a **MEDIUM** alert. Once the alert exists its priority stays as it was created, so a genuine failure never escalates to CRITICAL.

For sensors that matter, open the sensor's **Settings → Scanning Interval** and set **If a Sensor Query Fails** to *Set sensor to "down" immediately*.

Error-limit breaches are not affected — those go straight to Down and arrive as CRITICAL.

#### Step 5: Test It

You don't need to wait for a real outage.

**Option 1 — Simulate Error Status.** Open any Up sensor and choose **Simulate Error Status** from its context menu. Note that with default settings this arrives as `status=Warning` first (see Step 4). Use **Resume** to recover it.

**Option 2 — Breach an error limit.** Open a sensor with a numeric channel (a disk-space sensor works well), set **Lower Error Limit** above the current value, and save. The sensor drops straight to Down and the webhook arrives with `status=Down`. Restore the original limit to resolve it.

**Option 3 — Send Test Notification.** Open your notification template, scroll to the bottom, and click **Send Test Notification**. This confirms connectivity but does not populate real sensor values.

To verify the result: in PRTG check **Logs → System Events → Notifications** for the HTTP response code, and in ITOC360 open **Alerts** to confirm the alert opened with the expected priority.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FIaFq6eu4X2BMmEfgRuTH%2Fimage%20(2)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=6a91723b-d80e-4c70-877a-10692d8eb730" alt=""><figcaption></figcaption></figure>

> The screenshot above shows exactly how PRTG's payload looks when it arrives — flat key-value pairs, not JSON. The platform parses this automatically before running validation.

### Acknowledging Alerts

Acknowledging a sensor in PRTG does **not** close the corresponding ITOC360 alert.

PRTG state triggers fire on state *changes*. Acknowledging marks the sensor inside PRTG but does not change its state, so no webhook is sent and ITOC360 never learns about it. The alert stays open at its original priority until the sensor returns to **Up**.

Acknowledge alerts in ITOC360 instead, where the acknowledgement feeds into escalation policies.

### Payload Examples

#### Alert — Sensor Down

```
sensorid=1004
device=Probe Device
sensor=Disk Free (WMI Free Disk Space (Multi Disk))
status=Down
message=73 % (Free Space C:) is below the error limit of 90 % in Free Space C:
since=13.08.2026 17:19:31
lastup=13.08.2026 17:18:31
lastdown=13.08.2026 17:19:31
downtime=0,0004% [61 s]
group=Local Probe
probe=Local Probe
host=127.0.0.1
deviceid=40
linkdevice=https://prtg.example.com/device.htm?id=40
linksensor=https://prtg.example.com/sensor.htm?id=1004
```

Opens a CRITICAL alert.

#### Resolve — Sensor Back Up

```
sensorid=1004
device=Probe Device
sensor=Disk Free (WMI Free Disk Space (Multi Disk))
status=Up
message=OK
since=13.08.2026 17:23:31
lastup=13.08.2026 17:23:31
lastdown=13.08.2026 17:22:31
downtime=0,0016% [4 m 1 s]
group=Local Probe
probe=Local Probe
host=127.0.0.1
deviceid=40
linkdevice=https://prtg.example.com/device.htm?id=40
linksensor=https://prtg.example.com/sensor.htm?id=1004
```

Closes the alert opened above. Note that `lastdown` may arrive empty on the first alert of a sensor's lifetime; this does not affect validation.

### Troubleshooting

| Symptom                                            | Cause                                                               | What to do                                                                                           |
| -------------------------------------------------- | ------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------- |
| No alerts arrive at all                            | The template is attached to the *"no longer X"* row of the trigger. | Attach it to the **for at least 0 seconds** row instead. See Step 3.                                 |
| `400 Invalid payload` in the PRTG notification log | Notification summarization merged messages and dropped `sensorid`.  | Set **Notification Summarization** to *Always notify immediately, never summarize*.                  |
| Real failures arrive as MEDIUM instead of CRITICAL | PRTG held the sensor in Warning for one interval before Down.       | Set **If a Sensor Query Fails** to *Set sensor to "down" immediately*. See Step 4.                   |
| Alert stays open after acknowledging in PRTG       | Acknowledging does not change sensor state, so no webhook is sent.  | Acknowledge the alert in ITOC360. See **Acknowledging Alerts**.                                      |
| Recovery never closes the alert                    | The Up trigger is missing or attached to the wrong row.             | Add a State Trigger for **Up** at 0 seconds.                                                         |
| Paused sensors open alerts                         | The Paused state maps to ALERT.                                     | Set **Notification Handling during Scheduled Pause**to *Discard notifications during paused status*. |


# Salesforce Integration

### Overview

[Salesforce](https://www.salesforce.com/eu/products/) is the world's leading CRM platform, used by sales, support, and operations teams to manage customer relationships, cases, and workflows. By adding a lightweight Apex Class and Apex Trigger to your Salesforce org, you can automatically forward Case alerts to ITOC360 whenever a case is created or updated — and resolve them automatically when the case is closed.

This integration uses Salesforce's native Apex callout mechanism to send a structured JSON payload to the ITOC360 webhook endpoint.

### Provider Configuration & Mapping

ITOC360 uses the `event_type` field in the payload to determine the alert type.

| Payload Value | ITOC360 Type |
| ------------- | ------------ |
| `ALERT`       | ALERT        |
| `RESOLVE`     | RESOLVE      |

Priority is mapped from the `priority` field on the Salesforce Case object:

| Salesforce Case Priority | ITOC360 Priority |
| ------------------------ | ---------------- |
| `Low`                    | LOW              |
| `Medium`                 | MEDIUM           |
| `High`                   | HIGH             |
| `Critical`               | CRITICAL         |

***

### Setup Instructions

#### Step 1: Get Your Webhook URL and Token

1. Log in to your ITOC360 platform.
2. Go to **Sources → Add Source**.
3. Select **Salesforce** as your provider.
4. Save the configuration and copy the generated **Token**.

Your webhook URL will be in the following format:

```
https://api.itoc360.app/functions/v1/events?token<x-itoc360-token>
```

***

#### Step 2: Add ITOC360 as a Remote Site in Salesforce

Salesforce blocks outbound HTTP calls to external domains by default. You must allowlist the ITOC360 domain before the Apex trigger can send requests.

1. In Salesforce, click the **gear icon** (⚙️) in the top right and select **Setup**.
2. In the Quick Find search box, type **Remote Site Settings** and open it.
3. Click **New Remote Site**.
4. Fill in the fields:
   * **Remote Site Name:** `ITOC360`
   * **Remote Site URL:** `https://api.itoc360.app`
5. Click **Save**.

***

#### Step 3: Create the Apex Class

The Apex Class handles the outbound HTTP callout to ITOC360. It runs asynchronously to avoid blocking Salesforce transactions.

1. Click the **gear icon** and select **Developer Console**.
2. In the Developer Console, go to **File → New → Apex Class**.
3. Name the class `ITOC360Class` and click **OK**.
4. Replace the contents with the following code and click **Save**:

```java
global class ITOC360Class {

    @future(callout=true)
    global static void sendAlert(String endpoint, String payload) {
        HttpRequest req = new HttpRequest();
        req.setEndpoint(endpoint);
        req.setMethod('POST');
        req.setBody(payload);
        req.setHeader('Content-Type', 'application/json');
        req.setHeader('Accept', 'application/json');
        Http http = new Http();
        HTTPResponse res = http.send(req);
        System.debug('ITOC360 Response: ' + res.getStatusCode() + ' ' + res.getBody());
    }

    global static String sanitize(String value) {
        if (value == null) return 'null';
        return '"' + value.replaceAll('[\\\\"]', '') + '"';
    }
}
```

***

#### Step 4: Create the Apex Trigger

The Apex Trigger fires on Case insert and update events. It builds the JSON payload and calls the Apex Class to send it to ITOC360.

1. In the Developer Console, go to **File → New → Apex Trigger**.
2. Name the trigger `ITOC360CaseTrigger`, set the **sObject** to `Case`, and click **Submit**.
3. Replace the contents with the following code.
4. Replace `YOUR_TOKEN` with the token you copied in Step 1, then click **Save**:

```java
trigger ITOC360CaseTrigger on Case (after insert, after update) {

    String token = 'YOUR_TOKEN';
    String endpoint = 'https://api.itoc360.app/functions/v1/events?token=' + token;

    Case obj = Trigger.new[0];

    String eventType = obj.IsClosed ? 'RESOLVE' : 'ALERT';
    String caseNumber = obj.CaseNumber == null ? '' : obj.CaseNumber;
    String subject = obj.Subject == null ? '' : obj.Subject;
    String description = obj.Description == null ? '' : obj.Description;
    String priority = obj.Priority == null ? 'Medium' : obj.Priority;
    String status = obj.Status == null ? '' : obj.Status;
    String accountName = obj.Account == null ? '' : obj.Account.Name;

    String payload = '{' +
        '"event_type": '   + ITOC360Class.sanitize(eventType)   + ',' +
        '"case_number": '  + ITOC360Class.sanitize(caseNumber)  + ',' +
        '"subject": '      + ITOC360Class.sanitize(subject)      + ',' +
        '"description": '  + ITOC360Class.sanitize(description)  + ',' +
        '"priority": '     + ITOC360Class.sanitize(priority)     + ',' +
        '"status": '       + ITOC360Class.sanitize(status)       + ',' +
        '"account_name": ' + ITOC360Class.sanitize(accountName)  +
    '}';

    System.debug('ITOC360 Payload: ' + payload);
    ITOC360Class.sendAlert(endpoint, payload);
}
```

***

#### Step 5: Test the Integration

1. In Salesforce, go to the **Cases** object and create a new Case:
   * **Subject:** Any descriptive title
   * **Priority:** High
   * **Status:** New
2. Save the case.
3. Log in to ITOC360 and go to **Alerts** — the new case should appear as an active alert with the correct priority.
4. To test automatic resolution, open the case in Salesforce and change its **Status** to **Closed**, then save.
5. The corresponding alert in ITOC360 should automatically resolve.

***

### Troubleshooting

**Alerts are not appearing in ITOC360**

* Verify that the Remote Site Settings entry for `https://api.itoc360.app` is saved and active.
* Check the Salesforce Debug Logs: go to **Setup → Environment → Logs → Debug Logs**, add your user as a traced entity, and recreate the case. Look for `ITOC360 Response` in the log output.
* Make sure the token in the trigger matches the one generated in your ITOC360 source.

**Debug Logs are empty**

* In Debug Logs, check that the **Expiration Date** for your traced user is set in the future. Edit and extend it if needed, then recreate the case.


# SolarWinds Integration

[SolarWinds Orion](https://www.solarwinds.com/solutions/orion) is a network and infrastructure monitoring platform that tracks the health, performance, and availability of nodes, interfaces, applications, and volumes across your environment. When something goes wrong — a node goes down, a threshold is breached — Orion fires an alert.

### How It Works

SolarWinds uses an alert action called **Send a GET or POST Request to a Web Server** to push alert data outbound. You'll configure two of these actions per alert:

* **Trigger Action** — fires when the alert condition is met, opening an incident&#x20;
* **Reset Action** — fires when the condition clears, resolving the incident&#x20;

The `event_type` field in the payload (`TRIGGER` or `RESET`) tells ITOC360 what to do.

### In SolarWinds Orion

#### Step 1 — Open Alert Manager

Log in to SolarWinds, then navigate to **Alerts & Activity → Alerts**. On the top right, click **Manage Alerts**.

You'll land on the active alerts page, which lists all currently firing alerts in your environment.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FS9JTWf4dNzOlxRIHPkGU%2Fimage%20(82).png?alt=media&amp;token=f25d3e42-2af8-4740-9102-a57fc83e8b09" alt=""><figcaption></figcaption></figure>

#### Step 2 — Create a New Alert

Click **Add New Alert**. On the **Alert Properties** screen, fill in the following:

* **Name of alert definition** — give it something descriptive, like `itoc360 - Node Down`
* **Severity of alert** — set this to match the criticality you want (e.g. Critical)
* Leave **Enabled** toggled on
* Everything else can stay at its default

Click **Next** when you're done.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fe7I0oAP5w8zuW2T8k5oj%2Fimage%20(83).png?alt=media&amp;token=af9bb9af-f091-4468-b2f3-b0f6c4f54f16" alt=""><figcaption></figcaption></figure>

#### Step 3 — Set the Trigger Condition

On the **Trigger Condition** tab, define what should cause the alert to fire.

For a basic node monitoring setup:

* **I want to alert on:** Node
* **The scope of alert:** All objects in my environment
* **Trigger alert when:** Node → Status → is equal to → Up (then negate, or use "is not equal to Up")

You can adjust this to match whatever you're actually monitoring — the integration works with any alert type in SolarWinds.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FSikz1uwdlkmr0qxXy8HI%2Fimage%20(84).png?alt=media&amp;token=5d307297-733e-422b-90a9-2f0517cda7da" alt=""><figcaption></figcaption></figure>

#### Step 4 — Set the Reset Condition

On the **Reset Condition** tab, select **Reset this alert when trigger condition is no longer true**. This is the recommended option and it's what makes auto-resolution work — when the node comes back up, SolarWinds will fire the reset action automatically.

Click **Next**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F0YBJmVmAqQ7ajR8pX6Ki%2Fimage%20(85).png?alt=media&amp;token=eae48e76-4dd1-4f96-9085-1b9fb8fb424a" alt=""><figcaption></figcaption></figure>

#### Step 5 — Time of Day

On the **Time of Day** tab, leave it set to **Alert is always enabled, no schedule needed** unless you specifically want to suppress alerts during maintenance windows.

Click **Next**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FujZUuAmMdBNGRnm9Chr8%2Fimage%20(86).png?alt=media&amp;token=5b1175ed-89f4-4350-8d79-2795d3d828fc" alt=""><figcaption></figcaption></figure>

#### Step 6 — Add the Trigger Action

On the **Trigger Actions** tab, click **Add Action**. A dialog will pop up listing all available action types.

Scroll down and select **Send a GET or POST Request to a Web Server**, then click **Configure Action**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FG0CKbOtyHk8kgi0AwWUd%2Fimage%20(87).png?alt=media&amp;token=60f1b6f6-3887-4647-aa21-0f566f96ab7e" alt=""><figcaption></figcaption></figure>

In the configuration form, fill in the following:

| Field          | Value                                         |
| -------------- | --------------------------------------------- |
| Name of action | `itoc360`                                     |
| URL            | <https://api.itoc360.app/functions/v1/events> |
| Method         | Use HTTP/S POST                               |
| ContentType    | `application/json`                            |
| Authentication | None                                          |

Paste the following into the **Body to POST** field — keep it as a single line with no line breaks:

```
{"AlertID":"${N=Alerting;M=AlertID}","AlertName":"${N=Alerting;M=AlertName}","AlertStatus":"Triggered","AlertDescription":"${N=Alerting;M=AlertDescription}","Severity":"${N=Alerting;M=Severity}","TriggerTime":"${N=Alerting;M=AlertTriggerTime;F=DateTime}","ObjectType":"${N=Alerting;M=ObjectType}","ObjectName":"${N=SwisEntity;M=Caption}","NodeName":"${N=SwisEntity;M=Caption}","NodeIP":"${N=SwisEntity;M=IP_Address}","AlertDetailsUrl":"${N=Alerting;M=AlertDetailsUrl}","AcknowledgeUrl":"${N=Alerting;M=AcknowledgeLink}"}
```

Click **Save Changes**, then **Add Action**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FiIUhHlSqPRDr3NPxWMsd%2FEkran%20Resmi%202026-03-09%2017.58.08.png?alt=media&amp;token=ebe295a9-b494-4204-92cd-93cd9d9df208" alt=""><figcaption></figcaption></figure>

#### Step 7 — Add the Reset Action

Navigate to the **Reset Actions** tab and repeat the same process — click **Add Action**, select **Send a GET or POST Request to a Web Server**, and click **Configure Action**.

Use the exact same URL, method, and content type. The only change is in the body: swap `TRIGGER` for `RESET`.

```
{"AlertID":"${N=Alerting;M=AlertID}","AlertName":"${N=Alerting;M=AlertName}","AlertStatus":"Reset","AlertDescription":"${N=Alerting;M=AlertDescription}","Severity":"${N=Alerting;M=Severity}","TriggerTime":"${N=Alerting;M=AlertTriggerTime;F=DateTime}","ObjectType":"${N=Alerting;M=ObjectType}","ObjectName":"${N=SwisEntity;M=Caption}","NodeName":"${N=SwisEntity;M=Caption}","NodeIP":"${N=SwisEntity;M=IP_Address}","AlertDetailsUrl":"${N=Alerting;M=AlertDetailsUrl}","AcknowledgeUrl":"${N=Alerting;M=AcknowledgeLink}"}
```

Click **Save Changes**, then **Add Action**.

#### Step 8 — Save the Alert

Click through to the **Summary** page, review everything looks right, and hit **Submit**. The alert is now active.

### Payload Reference

| Field               | SolarWinds Variable                           | Description                                      |
| ------------------- | --------------------------------------------- | ------------------------------------------------ |
| `event_type`        | Static                                        | `TRIGGER` opens an incident, `RESET` resolves it |
| `alert_id`          | `${N=Alerting;M=AlertID}`                     | ID of the alert definition                       |
| `alert_active_id`   | `${N=Alerting;M=AlertActiveID}`               | ID of the active alert instance                  |
| `alert_object_id`   | `${N=Alerting;M=AlertObjectID}`               | ID of the object that triggered the alert        |
| `alert_name`        | `${N=Alerting;M=AlertName}`                   | Alert name as defined in SolarWinds              |
| `alert_description` | `${N=Alerting;M=AlertDescription}`            | Alert description text                           |
| `severity`          | `${N=Alerting;M=Severity}`                    | Critical, High, Warning, or Informational        |
| `trigger_time`      | `${N=Alerting;M=AlertTriggerTime;F=DateTime}` | Timestamp of when the alert fired                |
| `object_type`       | `${N=Alerting;M=ObjectType}`                  | Node, Interface, Volume, Application, etc.       |
| `entity_name`       | `${N=SwisEntity;M=Caption}`                   | Display name of the affected entity              |
| `entity_ip`         | `${N=SwisEntity;M=IP_Address}`                | IP address of the node                           |
| `node_id`           | `${N=SwisEntity;M=NodeID}`                    | Internal SolarWinds Node ID                      |
| `details_url`       | `${N=Alerting;M=AlertDetailsUrl}`             | Direct link to the alert in SolarWinds           |

### Priority Mapping

| SolarWinds Severity | itoc360 Priority |
| ------------------- | ---------------- |
| Critical            | critical         |
| High                | high             |
| Warning             | warning          |
| Medium              | warning          |
| Informational       | low              |
| Low                 | low              |

### Troubleshooting

**No incidents are being created**

Double-check that the webhook URL is pasted correctly in the action configuration with no trailing spaces. Make sure the ContentType is set to `application/json` and the method is POST. Use the Simulate button to send a test request and check the itoc360 logs for any errors.

**Incidents aren't resolving automatically**

Make sure the Reset Action is configured on the **Reset Actions** tab, not Trigger Actions, and that `"event_type":"RESET"` is in the payload body. Also confirm the Reset Condition is set to fire when the trigger condition is no longer true.

**Some fields come through empty**

Fields like `entity_ip` can be empty for non-node alerts (e.g. volume or application alerts), since those object types don't always have an IP address. This is expected and won't affect how incidents are created or resolved.


# Zabbix Integration

[Zabbix](https://www.zabbix.com/) is an enterprise-class open-source monitoring solution for networks, servers, applications, and cloud infrastructure. By importing the ITOC360 Watcher media type into your Zabbix instance, you can automatically forward problem and recovery alerts to ITOC360 and trigger your on-call escalation policies in real time.

### Provider Configuration & Mapping

ITOC360 uses the `status` field from the Zabbix payload to determine the alert type.

| Zabbix Status | ITOC360 Type |
| ------------- | ------------ |
| `PROBLEM`     | ALERT        |
| `RECOVERY`    | RESOLVE      |

Priority is mapped from the Zabbix event severity:

| Zabbix Severity  | ITOC360 Priority |
| ---------------- | ---------------- |
| `NOT_CLASSIFIED` | LOW              |
| `INFORMATION`    | LOW              |
| `WARNING`        | MEDIUM           |
| `AVERAGE`        | MEDIUM           |
| `HIGH`           | HIGH             |
| `DISASTER`       | CRITICAL         |

***

### Setup Instructions

#### Step 1: Get Your Webhook URL and Token

1. Log in to your ITOC360 platform.
2. Go to **Sources → Add Source**.
3. Select **Zabbix** as your provider.
4. Save the configuration and copy the generated **Token**.

#### Step 2: Import the ITOC360 Watcher Media Type

1. Download the ITOC360 Watcher media type file: **ITOC360\_Watcher\_7.0.yaml**

{% file src="/files/JyS90XpnitqMIyY1olLw" %}

1. In Zabbix, go to **Alerts → Media types**.
2. Click the **Import** button in the top right corner.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FYpcC3NdlmsGXYRV3DDai%2Fimage.png?alt=media&amp;token=8c66f0aa-7be2-4ff9-9a6a-5d4257bb2cbd" alt=""><figcaption></figcaption></figure>

4. Select the downloaded **ITOC360\_Watcher\_7.0.yaml** file and click **Import**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F3th0flDuw8N08lxTOcMy%2Fimage%20(1).png?alt=media&amp;token=f39103b0-da59-4b8a-a3d8-db311c11ad63" alt=""><figcaption></figcaption></figure>

5. The media type will be imported and opened automatically. Find the **token** parameter and replace `<PLACE TOKEN>`with the token you copied in Step 1.
6. Click **Update** to save.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FxPBQLmBcX6shuVd43Ytc%2Fimage%20(2).png?alt=media&amp;token=f01b3494-b6b7-4531-9ed5-36e10ba34f92" alt=""><figcaption></figcaption></figure>

***

#### Step 3: Create a User Group

1. Go to **Users → User groups**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FKJ9HXqanZGdubiDG0gKK%2Fimage%20(3).png?alt=media&amp;token=2147d2b1-84ee-4ff7-beff-54c595c18934" alt=""><figcaption></figcaption></figure>

2. Click **Create user group**.
3. Set the **Group name** to `ITOC360`.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FSIclXD6GQ7isUNrb6tv2%2Fimage%20(4).png?alt=media&amp;token=5c324c93-19c2-453c-ae06-307b8ac699e6" alt=""><figcaption></figcaption></figure>

4. Switch to the **Host permissions** tab.
5. Click **Select**, choose the host groups you want ITOC360 to receive alerts for, and set permission to **Read**.
6. Click **Update** to save.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FZMSPHO4rMkqpQccExgHl%2Fimage%20(5).png?alt=media&amp;token=8d3f2950-0983-4444-a2a3-b419e974b403" alt=""><figcaption></figcaption></figure>

#### Step 4: Create a User

1. Go to **Users → Users**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F4uXhHmqeIWXa9diog6de%2Fimage%20(6).png?alt=media&amp;token=531b7fd8-789d-4468-adc2-3929f15ca9fc" alt=""><figcaption></figcaption></figure>

2. Click **Create user** and fill in the form:
   * **Username:** `ITOC360`
   * **Groups:** Add the `ITOC360` group you created above.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FC2tbMjfkvIrJEWPyPCSn%2Fimage%20(7).png?alt=media&amp;token=f8703bbf-4155-43e0-9857-e1b06b0f8c0e" alt=""><figcaption></figcaption></figure>

3. Switch to the **Media** tab and click **Add**:
   * **Type:** `ITOC360 Watcher`
   * **Send to:** `ITOC360`
   * Leave all severity checkboxes enabled.
   * Click **Add**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FycdQQfYnplxs3GWFU9ad%2Fimage%20(8).png?alt=media&amp;token=901e0f0c-38ea-41fa-ad36-043406adfed0" alt=""><figcaption></figcaption></figure>

4. Switch to the **Permissions** tab and set **Role** to `Super admin role`.
5. Click **Add** to save the user.

#### Step 5: Create a Trigger Action

1. Go to **Alerts → Actions → Trigger actions**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FjBsbzSDsU1hVyiDxXzkh%2Fimage%20(9).png?alt=media&amp;token=7ce93383-be08-4ce3-8c40-a137151ec5bd" alt=""><figcaption></figcaption></figure>

2. Click **Create action**
3. Switch to the **Operations** tab:
   * Click **Add** under Operations.
   * Set **Send to user groups** to `ITOC360`.
   * Click **Add**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F30nMYbJK9Dv2DZ99vNa3%2Fimage%20(10).png?alt=media&amp;token=1e29206a-8cbd-47ae-866f-1cbf7c731236" alt=""><figcaption></figcaption></figure>

4. Switch to the **Recovery operations** tab and repeat the same configuration.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FT1mRnFoYa7CY08QRxFxj%2Fimage%20(11).png?alt=media&amp;token=2006e092-9265-42dd-b432-9e556351ee54" alt=""><figcaption></figcaption></figure>

5. Click **Add** to save the action.

***

#### Step 6: Verify the Integration

Once a problem is detected in Zabbix, it will automatically be sent to ITOC360 as an alert. When the problem is resolved in Zabbix, the corresponding alert in ITOC360 will be automatically closed.

To test the integration, you can add a host with an unreachable IP address — Zabbix will detect it as down and trigger an alert to ITOC360.


# Observability and APM

This category covers observability platforms and application performance monitoring tools. These tools collect metrics, traces, and logs across your application stack and send alert notifications to I

### Integrations in this category

| Integration     | What it monitors                                         | Alert delivery         |
| --------------- | -------------------------------------------------------- | ---------------------- |
| **Grafana**     | Metrics, logs, traces across any data source             | Webhook                |
| **Prometheus**  | Time-series metrics, service health                      | Webhook (Alertmanager) |
| **Datadog**     | Infrastructure, APM, logs, synthetics                    | Webhook                |
| **New Relic**   | Application performance, infrastructure, browser         | Webhook                |
| **Dynatrace**   | Full-stack observability, AI-powered anomaly detection   | Webhook                |
| **AppDynamics** | Application performance, business transaction monitoring | Webhook                |
| **SignalFX**    | Real-time infrastructure and application metrics         | Webhook                |
| **SigNoz**      | Distributed tracing, metrics, and logs (open source)     | Webhook                |
| **Elastic**     | Logs, metrics, APM, and SIEM alerts                      | Webhook                |
| **Site24x7**    | Servers, applications, websites, cloud resources         | Webhook                |
| **Cortex**      | Multi-tenant Prometheus metrics at scale                 | Webhook                |

***

### How it works

Observability and APM tools continuously evaluate metrics and trace data against alert rules. When a rule fires — an error rate crosses a threshold, a service latency degrades, or an anomaly is detected — the tool sends an alert to your ITOC360 Source webhook URL. ITOC360 maps the incoming payload fields to alert properties, matches the alert against your escalation policies, and routes the incident to the correct on-call engineer.

{% hint style="info" %}
ITOC360 generates a unique webhook URL per Source. Go to **Management > Sources**, create a Source, and copy the webhook URL or token to paste into your tool's alerting configuration.
{% endhint %}

***

### Get started


# AppDynamics Integration

### Overview

[AppDynamics](https://www.cisco.com/c/en_au/solutions/data-center/appdynamics-application-performance-monitoring.html) provides deep application performance monitoring (APM) and infrastructure visibility.

To integrate AppDynamics with our platform, we use an HTTP Request Template. Instead of sending AppDynamics' default complex payload, we use Velocity Template Language (VTL) to extract only the necessary variables. This formats the outgoing webhook to perfectly match our Event ➔ Alert ➔ Incident workflow.

### Provider Configuration & Mapping

AppDynamics sends event severity as `ERROR`, `WARN`, or `INFO`. We map these specific text values to our platform's internal priorities.

Priority Mapping Config:

JSON

```
{
  "priority": {
    "field": "$.Severity",
    "options": [
      { "value": "ERROR", "label": "Error" },
      { "value": "WARN", "label": "Warning" },
      { "value": "INFO", "label": "Info" }
    ],
    "mapping": {
      "ERROR": "CRITICAL",
      "WARN": "MEDIUM",
      "INFO": "LOW"
    }
  }
}
```

Correlation (Fingerprint): We use `$.IncidentNumber`, which pulls from the AppDynamics `${latestEvent.id}`. This unique ID allows our platform to track the alert and automatically resolve it when AppDynamics sends a recovery signal.

### Setup Instructions

#### Step 1: Get Your Webhook URL

1. Log in to your alert management platform.
2. Go to Sources → Add Source.
3. Select AppDynamics as your provider.
4. Save the configuration and copy the <https://api.itoc360.app/functions/v1/events> URL.

#### Step 2: Create the HTTP Request Template

1. Log in to your AppDynamics Controller.
2. From the top navigation bar or left menu, click Alert & Respond.
3. Click HTTP Request Templates.
4. Click New to create a fresh template.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F3gQZMoUNGSnPanlKmYBn%2Fimage%20(11)%20(1).png?alt=media&amp;token=bb5152a6-5d7e-48c3-bd5b-8abb94d9901e" alt=""><figcaption></figcaption></figure>

#### Step 3: Configure the Request Settings

Fill out the configuration form with your webhook details:

1. Name: Type a clear name (e.g., `OnCall Platform Webhook`).
2. Method: Select `POST`.
3. Raw URL: <https://api.itoc360.app/functions/v1/events>
4. Authentication: Leave this as `NONE`.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FtQS7kK7K5yKoRylutShB%2Fimage%20(10)%20(1).png?alt=media&amp;token=9bf34376-f8f4-40f5-af43-d71a301c632b" alt=""><figcaption></figcaption></figure>

Under the Custom Request Headers section, click Add Header:

* Header Name: `Content-Type`
* Header Value: `application/json`

Under the Payload section:

1. MIME Type: Select `application/json`.
2. Paste the following VTL-formatted JSON into the text area:

JSON

```
{
  "incident_name": "${latestEvent.displayName} – ${latestEvent.node.name}",
  "severity":      "${latestEvent.severity}",
  "description":   "${latestEvent.summaryMessage}",
  "app_name":      "${latestEvent.application.name}",
  "node_name":     "${latestEvent.node.name}",
  "event_id":      "${latestEvent.id}",
  "event_guid":    "${latestEvent.guid}",
  "event_type":    "${latestEvent.eventType}",
  "monitor_url":   "${latestEvent.deepLink}",
  "policy_name":   "${policy.name}",
  "time":          "${latestEvent.eventTime}",
  "message":       "${latestEvent.eventMessage}"
}
```

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FJURp2wTNREHBp3tsiDEG%2Fimage%20(9)%20(1).png?alt=media&amp;token=f7296016-fc48-4503-b71a-533ede0cd08f" alt=""><figcaption></figcaption></figure>

Under the Settings section:

1. Check the box for One Request Per Event. This ensures alerts are sent individually and not batched together.
2. Click Save.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FfKZ4XdhMobBn9YKUuqET%2Fimage%20(8)%20(1)%20(1)%20(1).png?alt=media&amp;token=902099e2-cf95-459b-9b64-8248f6d9662a" alt=""><figcaption></figcaption></figure>

#### Step 4: Test the Template

1. Scroll to the bottom of your saved template and click Test.
2. Click Add Event Type and select an event like Health Rule Violation Started - Warning.
3. Click Run Test.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FU3oIhOBq1pOGYwsJuxWr%2Fimage%20(7)%20(1)%20(1)%20(1).png?alt=media&amp;token=f0ea2283-5f2b-495f-b6f9-2360062966fe" alt=""><figcaption></figcaption></figure>

4. A green SUCCESS status indicates the payload was successfully delivered to your platform.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FiFcTrFum7KZEiaikTwFq%2Fimage%20(6)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=c2a84fdf-a4df-40ef-91d9-f48d923d3cee" alt=""><figcaption></figcaption></figure>

#### Step 5: Create an Action

After testing the template, you must save it as an executable Action.

1. Go back to the Alert & Respond menu and click Actions on the left sidebar.
2. Click Create Action.
3. Select Make an HTTP Request and click OK.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FwzzaeYxZRplDQgiVpPBp%2Fimage%20(5)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=6f6a44fb-81db-4764-a70d-bcaa78ab3768" alt=""><figcaption></figcaption></figure>

4. Name: Type a name for this action (e.g., `OnCall Platform Webhook`).
5. HTTP Request Template: Select the template you created in Step 3 from the dropdown menu. The URL and Payload will auto-populate.
6. Click Save.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F52gHyCiIQFfVtQYD0xOk%2Fimage%20(4)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=341ca051-ac4b-4107-aa83-de60ab24ace8" alt=""><figcaption></figcaption></figure>

#### Step 6: Link the Action to a Policy

To automate the webhook, you need to attach this Action to a monitoring Policy. When the policy triggers an alert, it will execute the webhook.

1. In the Alert & Respond menu, click Policies.
2. Click Create Policy. *(If a setup wizard appears, click Create Policy Manually under Quick Links).*

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FvIpwwL0xj2Hpdbq7UFR8%2Fimage%20(3)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=ebe36a03-9724-4ddd-86d4-7b0bb2e179cb" alt=""><figcaption></figcaption></figure>

3. In the Trigger tab, define which events should trigger the alert. For example, check the boxes for Health Rule Violation Events (Warning, Critical, etc.).

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F1UGJP1jkqtrcgB1l5Se1%2Fimage%20(2)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=726f58b5-fdb1-4590-bca0-a9ec201144ad" alt=""><figcaption></figcaption></figure>

You should choose;

* &#x20;Health Rule Violation Started - Critical
* &#x20;Health Rule Violation Started - Warning
* &#x20;Health Rule Violation **Ended** - Critical
* &#x20;Health Rule Violation **Ended** - Warning<br>

4. Go to the Actions tab at the top.
5. Click the + button to select an action. Choose your newly created `OnCall Platform Webhook` action and click Select.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fj7uRBr5aQxCkSLGsXezJ%2Fimage%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=75b5a261-c784-464e-83f8-376d76b21377" alt=""><figcaption></figcaption></figure>

6. Click Save to activate the policy. You will now see your active policy properly linked to the webhook action.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F3lfbAwm73TykaXwBTNCE%2Fimage%20(6)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=e9f4e34b-c9d4-41f0-8c00-ae7cf302abe6" alt=""><figcaption></figcaption></figure>

***

<a class="button secondary"></a>


# Cortex Integration

### Overview

[Cortex](https://cortexmetrics.io/) is a CNCF incubation project that provides horizontally scalable, highly available, multi-tenant, long-term storage for Prometheus metrics. It is compatible with the Prometheus API and is used in production systems including Amazon Managed Service for Prometheus (AMP).

Since Cortex uses the same Alertmanager webhook format as Prometheus, the integration flow is identical: Cortex evaluates alert rules and routes firing alerts through Prometheus Alertmanager, which delivers structured webhook payloads to the platform.

This integration supports automatic alert creation on firing events and automatic resolution when Alertmanager sends a resolved notification.

### Integration Flow

1. Cortex scrapes metrics from configured targets at a defined interval.
2. Cortex evaluates alert rules continuously. When a condition is met, it sends the alert to Alertmanager.
3. Alertmanager groups the alerts and delivers a webhook POST request to the platform endpoint.
4. When the alert condition clears, Alertmanager sends a resolved notification and the platform automatically closes the alert.

The payload delivered to the platform follows the standard Prometheus Alertmanager webhook format (version 4).

### Webhook Payload Schema

```json
{
  "receiver": "string",
  "status": "firing | resolved",
  "alerts": [
    {
      "status": "firing | resolved",
      "labels": {
        "alertname": "string",
        "severity": "string"
      },
      "annotations": {
        "summary": "string",
        "description": "string"
      },
      "startsAt": "ISO8601 timestamp",
      "endsAt": "ISO8601 timestamp",
      "generatorURL": "string",
      "fingerprint": "string"
    }
  ],
  "groupLabels": {},
  "commonLabels": {
    "alertname": "string",
    "severity": "string"
  },
  "commonAnnotations": {
    "summary": "string",
    "description": "string"
  },
  "externalURL": "string",
  "version": "4",
  "groupKey": "string",
  "truncatedAlerts": 0
}
```

***

### Setup

#### Step 1 — Create an Alert Source on the Platform

1. Navigate to **Sources → Add Source**.
2. Search for **Cortex** and select it.
3. Give the source a name and click **Save**.
4. Copy <https://api.itoc360.app/functions/v1/events> URL and **Token**.

#### Step 2 — Install and Configure Alertmanager

Cortex does not deliver alerts directly to external systems. You must run a Prometheus Alertmanager instance and point Cortex at it.

Install Alertmanager using your preferred method (binary, Docker, Helm). Then configure it to forward alerts to the platform:

```yaml
# alertmanager.yml
global:
  resolve_timeout: 5m

route:
  receiver: itoc360-webhook
  group_wait: 10s
  group_interval: 1m
  repeat_interval: 4h

receivers:
  - name: itoc360-webhook
    webhook_configs:
      - url: "https://api.itoc360.app/functions/v1/events?token=<x-itoc360-token>"
        send_resolved: true
```

`send_resolved: true` is required for automatic alert resolution on the platform.

***

#### Step 3 — Configure Cortex Ruler

Point the Cortex ruler to your Alertmanager and define your rule files:

```yaml
# cortex-config.yaml
ruler:
  alertmanager_url: http://alertmanager:9093
  enable_api: true

ruler_storage:
  backend: local
  local:
    directory: /etc/cortex/rules
```

***

#### Step 4 — Create Alert Rules

Create rule files in the configured rules directory. Each file defines one or more alert groups.

Example: `rules/production.yaml`

```yaml
groups:
  - name: production-critical
    interval: 1m
    rules:
      - alert: HighCPUUsage
        expr: |
          100 - (avg by (instance)
          (rate(node_cpu_seconds_total{mode="idle"}[5m])) * 100) > 90
        for: 5m
        labels:
          severity: critical
        annotations:
          summary: "High CPU usage detected"
          description: "Instance {{ $labels.instance }} CPU usage is above 90% for more than 5 minutes."
```

The `severity` label in `labels` is used by the platform for priority mapping (see table below).

***

#### Step 5 — Verify the Integration

After starting Cortex and Alertmanager:

1. Open Alertmanager UI at `http://<alertmanager-host>:9093` — confirm the alert is routed to the webhook receiver.
2. Confirm the alert appears on the platform under the source you created.

***

### Sample Payload

**ALERT (firing):**

```json
{
  "receiver": "itoc360-webhook",
  "status": "firing",
  "alerts": [
    {
      "status": "firing",
      "labels": {
        "alertname": "HighCPUUsage",
        "instance": "server-01:9100",
        "severity": "critical"
      },
      "annotations": {
        "summary": "High CPU usage detected",
        "description": "Instance server-01:9100 CPU usage is above 90% for more than 5 minutes."
      },
      "startsAt": "2026-04-07T09:46:06.815Z",
      "endsAt": "0001-01-01T00:00:00Z",
      "generatorURL": "http://cortex:9090/graph?g0.expr=...",
      "fingerprint": "34e164e9af873ac1"
    }
  ],
  "groupLabels": {},
  "commonLabels": {
    "alertname": "HighCPUUsage",
    "severity": "critical"
  },
  "commonAnnotations": {
    "summary": "High CPU usage detected"
  },
  "externalURL": "http://alertmanager:9093",
  "version": "4",
  "groupKey": "{}:{}",
  "truncatedAlerts": 0
}
```

**RESOLVE (resolved):**

```json
{
  "receiver": "itoc360-webhook",
  "status": "resolved",
  "alerts": [
    {
      "status": "resolved",
      "labels": {
        "alertname": "HighCPUUsage",
        "severity": "critical"
      },
      "annotations": {
        "summary": "High CPU usage detected"
      },
      "startsAt": "2026-04-07T09:46:06.815Z",
      "endsAt": "2026-04-07T10:01:00.000Z",
      "fingerprint": "34e164e9af873ac1"
    }
  ],
  "status": "resolved",
  "version": "4"
}
```

***

### Field Mapping Reference

| Payload Field                       | Description                                                           |
| ----------------------------------- | --------------------------------------------------------------------- |
| `status`                            | Top-level event type: `firing` → ALERT, `resolved` → RESOLVE          |
| `alerts[0].fingerprint`             | Unique identifier per alert label set — used for fingerprint matching |
| `alerts[0].labels.alertname`        | Name of the alert rule that fired                                     |
| `alerts[0].labels.severity`         | Severity label from the rule definition — used for priority mapping   |
| `alerts[0].annotations.summary`     | Short human-readable alert title                                      |
| `alerts[0].annotations.description` | Detailed description of the alert condition                           |
| `alerts[0].startsAt`                | ISO 8601 timestamp when the alert started firing                      |
| `alerts[0].endsAt`                  | ISO 8601 timestamp when resolved (`0001-...` means still active)      |
| `commonLabels`                      | Labels shared across all alerts in this group                         |
| `commonAnnotations`                 | Annotations shared across all alerts in this group                    |
| `groupKey`                          | Alertmanager group key used for deduplication                         |

### Priority Mapping

| Cortex `severity` Label | Platform Priority |
| ----------------------- | ----------------- |
| `critical`              | CRITICAL          |
| `error`                 | HIGH              |
| `warning`               | MEDIUM            |
| `info`                  | LOW               |
| (not set)               | MEDIUM (default)  |

You control the `severity` label in your alert rule definitions. Use consistent values across your rule files for predictable priority routing.

### RESOLVE Detection

The platform automatically resolves an alert when Alertmanager sends a payload with `"status": "resolved"`. This requires `send_resolved: true` in your Alertmanager webhook configuration (set in Step 2).

The resolved event is matched to the original alert using the `fingerprint` field, which Alertmanager generates deterministically from the alert's label set. As long as the labels do not change between firing and resolution, the fingerprint will match and the alert will be closed.


# Datadog Integration

Connecting [Datadog](https://app.datadoghq.eu/account/login?next=%2F) to itoc360 means every monitor alert automatically opens an incident — and when the monitor recovers, the incident closes on its own. Setup takes about five minutes and requires no additional agent installation. You only need to point a Datadog webhook at your itoc360 source URL and drop in a token.

### Prerequisites

* Admin or Standard role in your Datadog account
* A Datadog source created in itoc360 (the token is generated at this step)

### Setup

#### Step 1 — Create a Source in itoc360

1. In itoc360, go to **Sources → New Source**.
2. Select **Datadog** as the provider.
3. Once the source is saved, a token is generated. Copy it — you'll need it in the next step.

#### Step 2 — Add the Webhook in Datadog

1. In Datadog, go to **Integrations → Integrations** and search for **Webhooks**.
2. Open the Webhooks tile and click **+ New**.
3. Fill in the following fields:

**Name:** `itoc360` (this name is used when mentioning the webhook in monitors, e.g. `@webhook-itoc360`)

**URL:**

```
https://api.itoc360.app/functions/v1/events
```

**Payload:** Clear the default content and paste the following:

```json
{
  "alert_id": "$ALERT_ID",
  "alert_title": "$ALERT_TITLE",
  "alert_type": "$ALERT_TYPE",
  "alert_transition": "$ALERT_TRANSITION",
  "alert_metric": "$ALERT_METRIC",
  "alert_query": "$ALERT_QUERY",
  "alert_scope": "$ALERT_SCOPE",
  "alert_status": "$ALERT_STATUS",
  "hostname": "$HOSTNAME",
  "body": "$EVENT_MSG",
  "link": "$LINK",
  "tags": "$TAGS",
  "priority": "$PRIORITY",
  "date": "$DATE",
  "id": "$ID",
  "org": {
    "id": "$ORG_ID",
    "name": "$ORG_NAME"
  }
}
```

4. Check the **Custom Headers** box and enter:

```json
{"x-itoc360-token": "<your-source-token>"}
```

5. Click **Save**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FGzTmfSoYCC0tyZA4h31G%2FEkran%20Resmi%202026-03-13%2000.02.25.png?alt=media&amp;token=3d5daee1-2802-4772-b355-3b6a8de707f7" alt=""><figcaption></figcaption></figure>

#### Step 3 — Attach the Webhook to a Monitor

With the webhook in place, you decide which monitors send notifications to itoc360.

1. Open any monitor and click **Edit**.
2. Scroll to the **Configure notifications & automations** section.
3. In the message box, type `@webhook-itoc360` — Datadog will suggest it via autocomplete.
4. Save the monitor.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fc4R1GmCsGgqCGOeMvGYL%2FEkran%20Resmi%202026-03-13%2000.03.32.png?alt=media&amp;token=37d10a2a-1967-48f4-93e8-f12ca4b9bdb0" alt=""><figcaption></figcaption></figure>

From this point, every state change on that monitor will be forwarded to itoc360.

### How Alerts Map to Incidents

itoc360 reads the `alert_transition` field from the Datadog payload to decide whether to open or close an incident:

| Datadog `alert_transition` | itoc360 Action  |
| -------------------------- | --------------- |
| Triggered                  | Opens incident  |
| Re-Triggered               | Opens incident  |
| Warn                       | Opens incident  |
| No Data                    | Opens incident  |
| Renotify                   | Opens incident  |
| Recovered                  | Closes incident |

If the same monitor fires again after recovering, a new incident is opened since the previous one is already closed.

### Priority Mapping

itoc360 uses the `alert_type` field to determine incident priority:

| Datadog `alert_type` | itoc360 Priority |
| -------------------- | ---------------- |
| error                | High             |
| warning              | Medium           |
| info                 | Low              |
| success              | Low              |

To customize this mapping per source, go to **Sources → Edit → Priority Mapping**.

### Troubleshooting

**Webhook fires but no incident appears in itoc360** Check the Supabase Edge Function logs. The most common cause is a missing required field — make sure the payload template was pasted correctly and includes `alert_id`, `alert_title`, and `alert_transition`.

**Monitor triggers but webhook never fires** Verify that `@webhook-itoc360` is present in the monitor's notification message. Without the mention, Datadog won't call the webhook.

**401 Unauthorized** The token in Datadog's Custom Headers must exactly match the token shown on the itoc360 source page. If you regenerate the token in itoc360, update the Datadog webhook header as well.


# Dynatrace Integration

This guide explains how to automatically send Dynatrace problems to ITOC360 using a webhook.

**1.** Create the workflow Head over to the Workflows menu on the left panel. The list will be empty if you haven't made one before. Just click the button at the top right to start a new one.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FfRm5D0jP1UPS7oW472at%2FEkran%20Resmi%202026-03-01%2018.15.49.png?alt=media&amp;token=fda70c11-a1c9-48a2-81f7-683eb9e244e7" alt=""><figcaption></figcaption></figure>

**2.** Set up the trigger We want this to run whenever an alert pops up, so grab the Davis problem trigger. In the configuration panel on the right, set it up like this:

* Event state: Keep it as `active or closed`&#x20;
* Event category: Add the ones you need. Usually, it's `Availability`, `Custom`, `Error`, `Monitoring unavailable`, `Resource`, `Slowdown`, and `Info`.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fe6hZURylPr6lvy8fGvrz%2F28_Ekran%20Resmi%202026-07-14%2015.36.37.png?alt=media&amp;token=a1035afc-bbcf-42f4-9ced-c94a10f9dcb7" alt=""><figcaption></figcaption></figure>

**3.** Configure the HTTP Request Now drop an HTTP Request action right below your trigger. This is what actually sends the payload out.

* Method: `POST`
* URL: [https://api.itoc360.app/functions/v1/events?token](https://api.itoc360.app/functions/v1/events?token=YOUR_TOKEN)\<x-itoc360-token>
* Payload: You can just copy and paste the JSON block below. It basically maps the Dynatrace variables to the format ITOC360 expects.

JSON

```
{
  "ProblemID": "{{ event().get('display_id', event().get('event.id', 'unknown')) }}",
  "ProblemTitle": "{{ event().get('title', event().get('event.name', 'No title')) }}",
  "State": "{{ event().get('event.status', 'ACTIVE') }}",
  "Severity": "{{ event().get('severity', 'CUSTOM') }}",
  "ImpactedEntity": "{{ event().get('affected_entity_types', '') }}",
  "ProblemURL": "{{ event().get('problemUrl', '') }}",
  "Timestamp": "{{ event().get('timestamp', '') }}"
}
```

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FBC33n8vBxgVafy6k9bRg%2F29_Ekran%20Resmi%202026-07-14%2015.38.39.png?alt=media&amp;token=52350ec5-a102-4107-9667-f77bccd10fb1" alt=""><figcaption></figcaption></figure>

**Using legacy Dynatrace?**

The payload above only works on the current Dynatrace platform, which uses Workflows and Jinja-style expressions. On legacy environments the `{{ event().get(...) }}` syntax is not evaluated and the placeholders arrive as literal text.

If your environment shows **Settings → Integration → Problem notifications** instead of **Workflows**, you are on the legacy generation. Set up a **Custom Integration** notification there, point the Webhook URL at the same ITOC360 endpoint, add a `Content-Type: application/json` header, and use this payload instead:

json

```json
{
  "ProblemID": "{ProblemID}",
  "ProblemTitle": "{ProblemTitle}",
  "State": "{State}",
  "Severity": "{ProblemSeverity}",
  "ImpactedEntity": "{ImpactedEntity}",
  "ProblemURL": "{ProblemURL}",
  "Timestamp": ""
}
```

Legacy placeholders use **single** curly braces. Don't mix the two syntaxes — they are not interchangeable. `Timestamp` is intentionally left empty because legacy Dynatrace has no equivalent placeholder; ITOC360 uses its own receive time instead.

> **Note:** Use `{ProblemID}`, not `{PID}`. `ProblemID` is the human-readable problem number shown in the Dynatrace UI; `PID` is a long internal identifier. ITOC360 builds the alert fingerprint from `ProblemID`, so `PID` produces alerts that are hard to match back to Dynatrace.

On legacy Dynatrace, `State` arrives as `OPEN` or `RESOLVED` — both are handled automatically.

**4.** Allowlist the domain (Don't skip this)\
By default, Dynatrace blocks external outgoing requests. If this step is skipped, the webhook request may fail. Go to Settings > General > External requests. Open the Allowlist tab and click + New host pattern. Add the following host:

[api.itoc360.app](https://api.itoc360.app)

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FxdKJpQLpDMnruH6CpcCG%2F27_Ekran%20Resmi%202026-07-14%2015.33.41.png?alt=media&amp;token=551ea0b1-fc78-43f5-ab26-29c47ded66a9" alt=""><figcaption></figcaption></figure>

**5.** Deploy Once everything looks good, click Deploy at the top right. It’ll prompt you to save, so just hit Save and deploy to push it live.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F3gRlIDBVBEsw294qj8Np%2FEkran%20Resmi%202026-03-01%2018.27.54.png?alt=media&amp;token=508015d4-51d2-494f-b288-2592c203cdda" alt=""><figcaption></figcaption></figure>

**6.** Test the flow Let's make sure it actually fires. Hit the "Run" button on the canvas to trigger a test execution. Check the logs at the bottom of the Dynatrace screen—you should see a green Success status.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FVM10PLCIEHtNsjzYBkPn%2FEkran%20Resmi%202026-03-01%2018.29.16.png?alt=media&amp;token=02dcde83-7064-46a9-9a02-eb8c486d8a99" alt=""><figcaption></figcaption></figure>

To support automatic resolution in ITOC360, create a second workflow or update the trigger configuration to also send resolved/closed problem events. ITOC360 maps resolved or closed states to RESOLVE events using the same ProblemID.

### Troubleshooting

If Dynatrace events do not appear in ITOC360:

* Make sure the ITOC360 webhook URL is copied correctly.
* Verify that the HTTP method is set to POST.
* Confirm that the payload is valid JSON.
* Make sure `api.itoc360.app` is added to the Dynatrace external request allowlist.
* Check the workflow execution logs in Dynatrace.
* Verify that the workflow trigger matches the selected event categories.
* Confirm that the ITOC360 source token is valid.

If incidents are not resolved automatically:

* Make sure resolved or closed Dynatrace problem events are sent to ITOC360.
* Confirm that the same `ProblemID` is included in both active and resolved events.
* ITOC360 uses `ProblemID` as the correlation key to match updates with the original incident.


# Elastic Integrations

[Elastic](https://www.elastic.co/) is a search and observability platform built around Elasticsearch and Kibana. Its built-in alerting engine lets you define rules that evaluate queries on your data at regular intervals. When a rule condition is met, Kibana can fire a webhook action to any HTTP endpoint — including itoc360. This page walks you through setting up that connection.

### How It Works

Kibana rules run on a schedule you define. When the rule condition is met (for example, a query returns more results than a threshold), Kibana calls the webhook connector you have attached to that rule. The connector sends a JSON payload to itoc360, which turns it into an alert in your on-call workflow.

### Prerequisites

* An Elastic Cloud account (any plan with Kibana access)
* An itoc360 account with at least one active on-call schedule

### Step 1 — Open Kibana

Log in to your Elastic Cloud account and open your Kibana deployment. You will land on the Observability overview page.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fer4XeS3P7PqbHqrTUBkE%2Fimage%20(3)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=3a9309b3-9f05-49cb-ad40-758effcc8cb8" alt=""><figcaption></figcaption></figure>

### Step 2 — Create a Webhook Connector

Navigate to **Settings (⚙️) → Connectors** in the left sidebar, then click **Create connector**.

Select **Webhook** from the connector type list. Fill in the connector form with the following values:

| Field             | Value                                         |
| ----------------- | --------------------------------------------- |
| Connector name    | `itoc360`                                     |
| Method            | POST                                          |
| URL               | <https://api.itoc360.app/functions/v1/events> |
| Authentication    | None                                          |
| HTTP Header Key   | `Content-Type`                                |
| HTTP Header Value | `application/json`                            |

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FF2qJKelSAMCER8w1o3lu%2FEkran%20Resmi%202026-03-23%2017.16.49.png?alt=media&amp;token=a9f51da2-2d1a-4ec7-b41c-7c7613f512d5" alt=""><figcaption></figcaption></figure>

Click **Save** to confirm.

### Step 3 — Create an Alerting Rule

Go to **Connectors → Rules** in the left menu and click **Create rule**. From the rule type list, select **Elasticsearch query**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FMhUTX9gRouoatesyqaev%2Fimage%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=619718bb-b8a3-40bb-bb60-f0df97b0de00" alt=""><figcaption></figcaption></figure>

Configure the rule definition:

* **Query type:** KQL or Lucene
* **Data view:** Select the data view that covers the indices you want to monitor
* **Condition:** Set your threshold (for example, `count() IS ABOVE 0`)
* **Rule schedule:** Every 1 minute (adjust to your needs)

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FcQZaTgYXCdVEM3KvvP7Y%2FEkran%20Resmi%202026-03-23%2017.18.10.png?alt=media&amp;token=40081841-7ad0-44bb-86ee-e7c3f312f34f" alt=""><figcaption></figcaption></figure>

Scroll down to the **Actions** section and click **Add action**. Select **Webhook**, then choose the `itoc360` connector you created in Step 2.

In the action body, paste the following template:

```json
{
  "alertId": "{{alertId}}",
  "alertName": "{{alertName}}",
  "alertActionGroup": "{{alertActionGroup}}",
  "alertActionGroupName": "{{alertActionGroupName}}",
  "spaceId": "{{spaceId}}",
  "date": "{{date}}",
  "kibanaBaseUrl": "{{kibanaBaseUrl}}",
  "context": {{{context}}}
}
```

Scroll further down, give the rule a name under **Details**, then click **Save rule**.

### Step 4 — Verify the Connection

To confirm that alerts are reaching ITOC360, open the connector and go to the **Test** tab. Replace the body with a plain JSON payload (no Mustache variables) and click **Run**.

A `200 OK` response in the Results section means the connection is working. Within the next rule evaluation cycle, a real alert will appear in your ITOC360 alert feed.

### Webhook Payload Structure

When a rule fires, Kibana sends a payload that looks like this:

```json
{
  "alertId": "abc123",
  "alertName": "High Error Rate",
  "alertActionGroup": "query matched",
  "alertActionGroupName": "Query matched",
  "spaceId": "default",
  "date": "2026-03-23T17:00:00.000Z",
  "kibanaBaseUrl": "https://my-project.kb.europe-west3.gcp.elastic.cloud",
  "context": {
    "title": "rule 'High Error Rate' matched query",
    "message": "rule is active",
    "conditions": "count > 0",
    "value": "42"
  }
}
```

### Troubleshooting

**The connector test returns an error** Double-check that the URL field contains your full itoc360 webhook endpoint and that the `Content-Type: application/json` header is present. Remove any trailing slashes from the URL.

**Rules are firing but no alerts appear in itoc360** Make sure the `itoc360` connector is selected in the **Actions** section of the rule, not just saved at the connector level. Each rule needs its connector explicitly attached.

**The action body looks wrong after saving** Kibana validates Mustache templates at save time. If you see an error, make sure `{{{context}}}` uses triple braces (not double) since it contains a JSON object, and all other variables use double braces.


# Grafana Integration

### Overview

[Grafana](https://grafana.com/) is an open-source analytics and observability platform widely used for monitoring metrics, logs, and traces. By configuring a Webhook contact point in Grafana Alerting, you can forward firing and resolved alerts directly to ITOC360 and trigger your on-call escalation policies in real time.

### Provider Configuration & Mapping

ITOC360 uses the `status` field from Grafana's webhook payload to determine the alert type.

| Grafana Status | ITOC360 Type |
| -------------- | ------------ |
| `firing`       | ALERT        |
| `resolved`     | RESOLVE      |

Priority is read from the `severity` label on your Grafana alert rule. The supported values and their mappings are:

| Grafana Severity Label | ITOC360 Priority |
| ---------------------- | ---------------- |
| `info`                 | LOW              |
| `warning`              | MEDIUM           |
| `critical`             | CRITICAL         |

To use priority mapping, add a `severity` label to your Grafana alert rule with one of the values above. If no severity label is present, the alert will default to MEDIUM priority.

***

### Setup Instructions

**Step 1: Get Your Webhook URL**

1. Log in to your ITOC360 platform.
2. Go to **Sources → Add Source**.
3. Select **Grafana** as your provider.
4. Save the configuration and copy the generated **Webhook URL** and **Token**.

**Step 2: Open Notification Configuration**

1. Log in to your Grafana instance.
2. From the left sidebar, go to **Alerts & IRM → Alerting → Notification configuration**.
3. Make sure you are on the **Contact points** tab.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FCWL8RNCeWu8r74AxLNwp%2Fimage%20(147).png?alt=media&amp;token=03c3548c-37fc-4e76-8579-4c15143df5f7" alt=""><figcaption></figcaption></figure>

**Step 3: Create a Contact Point**

1. Click **+ New contact point** in the top right corner.
2. Fill in the form:
   * **Name:** `itoc360`
   * **Integration:** Select `Webhook` from the dropdown.
   * **URL:** Paste your webhook URL in the following format:

     ```
     https://api.itoc360.app/functions/v1/events
     ```
   * **HTTP Method:** `POST`
   * **Extra Headers:**`x-itoc360-token`
3. Leave all other fields as default.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FDZefJpqLWxunQkyuSdpV%2Fimage%20(148).png?alt=media&amp;token=36df4672-6dfe-40d6-a5e0-34e1d9f6b2b6" alt=""><figcaption></figcaption></figure>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fy2UHSLiOeqylITw5jiCA%2Fimage%20(150).png?alt=media&amp;token=a7a7efc4-932a-48b4-8ede-7eafdad41762" alt=""><figcaption></figcaption></figure>

**Step 4: Test the Contact Point**

1. Click the **Test** button in the top right of the form.
2. A dialog will appear — click **Send test notification**.
3. A green **Test notification sent successfully** message confirms the payload reached ITOC360.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FoZobVwXwc3feW5WSGgq5%2Fimage%20(149).png?alt=media&amp;token=325e0fd1-4997-40fe-a2eb-f448568dea02" alt=""><figcaption></figcaption></figure>

4. Click **Save contact point**.

**Step 5: Set as Default Notification Policy**

1. Switch to the **Notification policies** tab.
2. On the **Default policy** row, click **More → Edit**.
3. In the **Edit route** dialog, click the **Default contact point** dropdown and select `itoc360`.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FNB3dV3Uak7tLKemyW4Hs%2Fimage%20(152).png?alt=media&amp;token=bda2f91a-334b-461e-8115-30542cc445c2" alt=""><figcaption></figcaption></figure>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F3fgpi6BvpAfPoqadbbue%2Fimage%20(153).png?alt=media&amp;token=118e14ac-82f8-4cf4-b996-cd9a65ae0916" alt=""><figcaption></figcaption></figure>

4. Click **Update policy**.

From this point on, all firing alerts in Grafana will be routed to ITOC360. Each alert rule you create will automatically notify your on-call team based on your escalation policies.


# New Relic Integration

[New Relic](https://newrelic.com/) is a full-stack observability platform that helps you monitor application performance, infrastructure health, browser experience, and more. It provides real-time insights with customizable alerting through its Alerts & AI system.

### Overview

This guide walks you through integrating New Relic with our alert management platform. New Relic delivers alert notifications through its **Workflow** system: when an alert condition is violated, New Relic creates an **Issue**, and the configured Workflow sends a webhook payload to our platform. When the issue is closed (manually or automatically), a separate **CLOSED** payload is sent for recovery.

### Integration Flow

1. New Relic monitors your infrastructure, applications, and services through installed agents and integrations.
2. When a metric violates a configured **Alert Condition** threshold, New Relic opens an **Incident** and groups it into an **Issue**.
3. The **Workflow** evaluates its filter criteria and sends an HTTP POST webhook payload to the configured **Destination** (our platform endpoint).
4. When the issue is resolved or manually closed, the Workflow sends a **CLOSED** payload to the same endpoint for recovery.

***

### Webhook Payload Schema

New Relic sends a customizable JSON payload via Workflows. The default payload template includes the following fields:

| Field               | Type    | Required | Description                                                       |
| ------------------- | ------- | -------- | ----------------------------------------------------------------- |
| id                  | string  | Yes      | Unique identifier for the issue                                   |
| issueUrl            | string  | Yes      | Direct link to the issue in New Relic                             |
| title               | string  | Yes      | Human-readable description of the alert condition violation       |
| priority            | string  | Yes      | Issue priority: `CRITICAL`, `HIGH`, `MEDIUM`, `LOW`, `WARNING`    |
| impactedEntities    | array   | Yes      | List of affected entity names (e.g., hostname)                    |
| totalIncidents      | number  | Yes      | Number of incidents grouped into this issue                       |
| state               | string  | Yes      | Issue state: `CREATED`, `ACTIVATED`, `ACKNOWLEDGED`, `CLOSED`     |
| trigger             | string  | Yes      | What triggered this notification: `INCIDENT_ADDED`, `USER_ACTION` |
| isCorrelated        | boolean | No       | Whether the issue was correlated with other issues                |
| createdAt           | number  | Yes      | Unix timestamp (ms) when the issue was created                    |
| updatedAt           | number  | Yes      | Unix timestamp (ms) when the issue was last updated               |
| sources             | array   | Yes      | Source of the alert (e.g., `["newrelic"]`)                        |
| alertPolicyNames    | array   | Yes      | List of alert policy names associated with this issue             |
| alertConditionNames | array   | Yes      | List of alert condition names that triggered this issue           |
| workflowName        | string  | Yes      | Name of the workflow that sent this notification                  |

***

### State / Status Mapping

| New Relic State | Platform Status | Description                                       |
| --------------- | --------------- | ------------------------------------------------- |
| CREATED         | PROBLEM         | Issue just created, first incident added          |
| ACTIVATED       | PROBLEM         | Issue is active with ongoing incidents            |
| ACKNOWLEDGED    | ACKNOWLEDGED    | Issue has been acknowledged by a team member      |
| CLOSED          | RECOVERY        | Issue resolved — either manually or automatically |

### Priority Mapping

| New Relic Priority | Platform Severity |
| ------------------ | ----------------- |
| CRITICAL           | Critical          |
| HIGH               | High              |
| MEDIUM             | Medium            |
| LOW                | Low               |
| WARNING            | Warning           |

***

### Alert Payload Examples

#### Raised (CREATED)

This payload is sent when a new issue is created from a threshold violation. The `state` field is `CREATED` and the `trigger` is `INCIDENT_ADDED`.

```json
{
  "id": "63d9ded1-4a02-46de-bcd5-e8305d743164",
  "issueUrl": "https://radar-api.service.newrelic.com/accounts/1/issues/0ea2df1c-adab-45d2-aae0-042b609d2322?notifier=WEBHOOK",
  "title": "prod-web-server-01 query result is > 1.0 for 1 minutes on 'High CPU Usage'",
  "priority": "CRITICAL",
  "impactedEntities": [
    "prod-web-server-01"
  ],
  "totalIncidents": 1,
  "state": "CREATED",
  "trigger": "INCIDENT_ADDED",
  "isCorrelated": false,
  "createdAt": 1770993830980,
  "updatedAt": 1770993830980,
  "sources": ["newrelic"],
  "alertPolicyNames": ["Test Infrastructure Policy"],
  "alertConditionNames": ["High CPU Usage"],
  "workflowName": "OnCall Webhook Workflow"
}
```

#### Cleared (CLOSED)

This payload is sent when the issue is closed. The `state` field is `CLOSED` and the `trigger` indicates what caused the closure (e.g., `USER_ACTION` for manual close).

```json
{
  "id": "63d9ded1-4a02-46de-bcd5-e8305d743164",
  "issueUrl": "https://radar-api.service.newrelic.com/accounts/1/issues/0ea2df1c-adab-45d2-aae0-042b609d2322?notifier=WEBHOOK",
  "title": "prod-web-server-01 query result is > 1.0 for 1 minutes on 'High CPU Usage'",
  "priority": "CRITICAL",
  "impactedEntities": [
    "prod-web-server-01"
  ],
  "totalIncidents": "1",
  "state": "CLOSED",
  "trigger": "USER_ACTION",
  "isCorrelated": "false",
  "createdAt": 1770993830980,
  "updatedAt": 1770996003468,
  "sources": ["newrelic"],
  "alertPolicyNames": ["Test Infrastructure Policy"],
  "alertConditionNames": ["High CPU Usage"],
  "workflowName": "OnCall Webhook Workflow"
}
```

***

### Installation & Configuration

#### Step 1: Create an Alert Source in the Platform

1. Log in to the alert management platform.
2. Navigate to **Integrations** → **Add Integration**.
3. Select **New Relic** as the provider.
4. Name the integration (e.g., `Production New Relic Alerts`).
5. Save and copy the generated **Webhook URL** and **Token**.

#### Step 2: Create a Webhook Destination in New Relic

1. Log in to your **New Relic** account.
2. Navigate to **Alerts** → **Destinations** (under ENRICH & NOTIFY in the left sidebar)

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FW8uuhN1aZYYmVD01Mdmb%2FEkran%20Resmi%202026-06-12%2014.56.30.png?alt=media&amp;token=4720aaba-086a-4d16-a5bb-96cefe9b492b" alt=""><figcaption></figcaption></figure>

&#x20;— Destinations page (empty, showing available destination types)

3. Click on **Webhook** from the "Add a destination" section.
4. Configure the webhook destination:
   * **Webhook name**: Enter a descriptive name (e.g., `OnCall Platform`)
   * **Endpoint URL**: [https://api.itoc360.app/functions/v1/events](https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>)
   * **Authorization**: Select 'custom header' and fill the key blank with "x-itoc360-token" then paste your source token through value blank.
5. Click **Save destination**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FdqCyrDbL7YOCw7pHzyMm%2FEkran%20Resmi%202026-03-24%2018.44.19.png?alt=media&amp;token=c020b9dc-953d-4793-a4fd-08bc02c9457d" alt=""><figcaption></figcaption></figure>

&#x20;— Add destination form with webhook name and endpoint URL

6. The destination will now appear in the Destinations list.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FZlkq870k98qeOxexOf2G%2FEkran%20Resmi%202026-02-25%2015.36.47.png?alt=media&amp;token=80ecc201-c47b-412d-8c8f-2b5758cdef96" alt=""><figcaption></figcaption></figure>

&#x20;— Destination created and visible in the list

#### Step 4: Create an Alert Condition

1. Navigate to **Alerts** → **Alert Conditions** or click **Create alert condition**.
2. Select **Write your own query** (NRQL mode).
3. Enter a NRQL query to monitor a metric. For example, to monitor CPU usage:

```sql
SELECT average(cpuPercent) FROM SystemSample WHERE hostname LIKE '%YourHostname%'
```

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FeAHfc2pTxdw4gG074d7W%2Fimage%20(10)%20(1)%20(1)%20(1).png?alt=media&amp;token=0cf328c3-e368-4197-bc00-040cb82203ab" alt=""><figcaption></figcaption></figure>

&#x20;— NRQL query entered in the condition builder

4. Click **Next** to set thresholds.
5. Configure the condition threshold:
   * **Threshold type**: Static
   * **Severity level**: Critical
   * **When a query returns a value**: above `1` for at least `1` minute

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F3hzOkJfAkqKJJd3GUtM6%2Fimage%20(11)%20(1)%20(1)%20(1).png?alt=media&amp;token=52e8ddf9-2798-468e-8526-d5e43f5e0e28" alt=""><figcaption></figcaption></figure>

&#x20;— Threshold configuration (Static, Critical, above 1 for 1 minute)

6. Click **Next** to add details.
7. Configure the condition details:
   * **Name your alert condition**: `High CPU Usage`
   * **Policy name**: `Test Infrastructure Policy` (or create a new policy)
   * **Group incidents into issues**: Select **One issue per condition**

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FEI7dfvnksUKhXM1lrbPu%2Fimage%20(12)%20(1)%20(1)%20(1).png?alt=media&amp;token=9f3538f2-ce8b-4dcd-8eba-ab6da22d8092" alt=""><figcaption></figcaption></figure>

— Add details page with condition name and policy

8. Click **Save & set up notifications**.

#### Step 5: Create a Workflow

1. Navigate to **Alerts** → **Workflows** (under ENRICH & NOTIFY).

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FFZJAYeOQj8ilSggOdMzg%2Fimage%20(13)%20(1).png?alt=media&amp;token=2140c112-06c8-4c1a-82a7-2a5c43440bde" alt=""><figcaption></figcaption></figure>

&#x20;— Workflows page

2. Click **Create your first workflow** (or **Add a workflow** if you already have one).
3. Configure the workflow filter:
   * **Policy**: Select `Test Infrastructure Policy`
   * Verify the filter shows "Filter is valid!"

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F2mzS0f3OgX697Y0G7bsh%2Fimage%20(14).png?alt=media&amp;token=a72f8948-19d3-4b3b-8316-f3c0f201d3ed" alt=""><figcaption></figcaption></figure>

&#x20;— Workflow filter configuration with policy selected

4. Under **Notify**, click **Webhook** to add a notification channel.
5. Select the destination you created in Step 2 (e.g., `OnCall Platform`).
6. Configure the payload template. The default template includes all necessary fields.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FZOm2HH4btLNDbUJc6zfL%2FEkran%20Resmi%202026-02-25%2015.45.01.png?alt=media&amp;token=9b152b5b-392f-409f-ae7a-fd9341cf4b0d" alt=""><figcaption></figcaption></figure>

&#x20;— Payload template editor with preview showing real data

7. Click **Update message** to save the payload template.
8. Back on the workflow page, verify the Webhook channel shows **All updates** (this ensures both CREATED and CLOSED notifications are sent).

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FZPkP72ROck3LfKhLMaAt%2Fimage%20(16).png?alt=media&amp;token=25573e0c-b7eb-4639-91b2-e486b7683fed" alt=""><figcaption></figcaption></figure>

&#x20;— Workflow with Webhook channel configured, showing "All updates"

> **Important:** The channel must be set to **All updates** to receive CLOSED (recovery) notifications. Without this, only trigger notifications will be sent.

9. Click **Activate workflow**.

***

### Testing

#### Verify Alert Trigger (CREATED)

Once the alert condition is active, it will automatically trigger when the threshold is breached. You can verify the notifications in two places:

1. **Issue Notifications Log**: Navigate to **Workflows** → **Issue Notifications Log** tab to see sent notifications.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Ffo5tr1l0XOllWW4IraOq%2Fimage%20(17).png?alt=media&amp;token=4830f7b5-a1e3-45e4-be91-43a801ba5faf" alt=""><figcaption></figcaption></figure>

&#x20;— Issue Notifications Log showing sent notifications

#### Verify Active Issue

Navigate to **Alerts** → **Issues & Activity** to see the active issue with its priority, duration, and entity name.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F8wBcZrWMtM2h86uEIF99%2FEkran%20Resmi%202026-02-25%2015.47.41.png?alt=media&amp;token=50fb843f-b7e4-4d8d-902c-eeb83e8e60db" alt=""><figcaption></figcaption></figure>

&#x20;— Issues & Activity showing Active issue (Critical priority)

#### Verify Recovery (CLOSED)

To test the recovery flow:

1. Go to **Issues & Activity**.
2. Select the active issue (checkbox).
3. Click **Close issues**.

#### Verification Checklist

Verify that:

1. A **CREATED** notification is received by the platform (status: PROBLEM).
2. The payload contains the correct `alertPolicyNames`, `alertConditionNames`, and `priority`.
3. A **CLOSED** notification is received after closing the issue (status: RECOVERY).
4. The `id` field matches between CREATED and CLOSED payloads for proper correlation.

***

### Troubleshooting

| Issue                          | Possible Cause                                  | Resolution                                                                                  |
| ------------------------------ | ----------------------------------------------- | ------------------------------------------------------------------------------------------- |
| No alerts received             | Workflow not activated                          | Ensure the workflow status is **Active** in the Workflows page                              |
| No alerts received             | Workflow filter doesn't match                   | Verify the Policy filter matches your alert policy name exactly                             |
| Recovery alerts missing        | Channel not set to "All updates"                | Edit the webhook channel in the workflow and ensure notification preference includes closed |
| Payload format unexpected      | Custom payload template modified                | Revert to the default payload template or verify all required fields are present            |
| Authentication error (401/403) | Incorrect webhook URL or token                  | Verify the endpoint URL and authentication token in the Destination settings                |
| Delayed notifications          | Evaluation delay or aggregation window too long | Reduce the Window duration and Delay values in the alert condition's signal settings        |
| "Failed" in Notifications Log  | Destination endpoint unreachable                | Check the endpoint URL is accessible and responding with 2xx status codes                   |
| Duplicate notifications        | Multiple workflows matching the same policy     | Review Workflows and remove duplicates                                                      |

***


# Prometheus Integration

### Overview

[Prometheus](https://prometheus.io/) is an open-source systems monitoring and alerting toolkit that collects metrics from configured targets, evaluates alert rules, and routes firing alerts to an external Alertmanager. When a rule condition is breached, Alertmanager groups and delivers a structured webhook payload to ITOC360.

This integration supports automatic alert creation on firing events and automatic resolution when Alertmanager sends a resolved notification.

### Integration Flow

1. Prometheus scrapes metrics from configured targets at a defined interval.
2. Prometheus evaluates alert rules continuously. When a condition is met, it sends the alert to Alertmanager.
3. Alertmanager groups the alerts and delivers a webhook POST request to ITOC360 endpoint.
4. When the alert condition clears, Alertmanager sends a `resolved` notification and the ITOC360 automatically closes the alert.

### Webhook Payload Schema

The payload delivered to ITOC360 follows the standard Prometheus Alertmanager webhook format (version 4).

```json
{
  "receiver": "string",
  "status": "firing | resolved",
  "alerts": [
    {
      "status": "firing | resolved",
      "labels": {
        "alertname": "string",
        "severity": "string",
        "env": "string"
      },
      "annotations": {
        "summary": "string",
        "description": "string"
      },
      "startsAt": "ISO8601 timestamp",
      "endsAt": "ISO8601 timestamp",
      "generatorURL": "string",
      "fingerprint": "string"
    }
  ],
  "groupLabels": {},
  "commonLabels": {
    "alertname": "string",
    "severity": "string"
  },
  "commonAnnotations": {
    "summary": "string",
    "description": "string"
  },
  "externalURL": "string",
  "version": "4",
  "groupKey": "string",
  "truncatedAlerts": 0
}
```

***

### Setup

#### Step 1 — Create an Alert Source on the ITOC360

1. Navigate to **Sources** → **Add Source**.
2. Search for **Prometheus** and select it.
3. Give the source a name and click **Save**.
4. Copy ITOC360 **URL** and **Token**.

#### Step 2 — Install and Configure Alertmanager

Prometheus does not deliver alerts directly to external systems. You must run a Prometheus Alertmanager instance and point Prometheus at it.

Install Alertmanager using your preferred method (binary, Docker, Helm). Then configure it to forward alerts to ITOC360:

**`alertmanager.yml`**

```yaml
global:
  resolve_timeout: 5m

route:
  receiver: itoc360-webhook
  group_wait: 10s
  group_interval: 1m
  repeat_interval: 4h

receivers:
  - name: itoc360-webhook
    webhook_configs:
      - url: "https://api.itoc360.app/functions/v1/events?token=<x-itoc360-token>"
        send_resolved: true
```

> `send_resolved: true` is required for automatic alert resolution on the ITOC360.

#### Step 3 — Configure Prometheus

Point Prometheus to your Alertmanager and define your rule files in `prometheus.yml`:

```yaml
global:
  scrape_interval: 15s
  evaluation_interval: 15s

alerting:
  alertmanagers:
    - static_configs:
        - targets:
            - <alertmanager-host>:9093

rule_files:
  - /etc/prometheus/rules/*.yaml
```

#### Step 4 — Create Alert Rules

Create rule files in the configured `rule_files` directory. Each file defines one or more alert groups.

**Example: `rules/production.yaml`**

```yaml
groups:
  - name: production-critical
    interval: 1m
    rules:
      - alert: HighCPUUsage
        expr: |
          100 - (avg by (instance) (rate(node_cpu_seconds_total{mode="idle"}[5m])) * 100) > 90
        for: 5m
        labels:
          severity: critical
        annotations:
          summary: "High CPU usage detected"
          description: "Instance {{ $labels.instance }} CPU usage is above 90% for more than 5 minutes."
```

> The `severity` label in `labels` is used by the ITOC360 for priority mapping (see table below).

#### Step 5 — Verify the Integration

After starting Prometheus and Alertmanager:

1. Open Prometheus UI at `http://<prometheus-host>:9090/alerts` — active alerts should appear there first.
2. Open Alertmanager UI at `http://<alertmanager-host>:9093` — confirm the alert is routed to the webhook receiver.
3. Confirm the alert appears on the ITOC360 under the source you created.

### Sample Payload

The following is a real payload captured during integration testing.

**ALERT (firing):**

```json
{
  "receiver": "itoc360-webhook",
  "status": "firing",
  "alerts": [
    {
      "status": "firing",
      "labels": {
        "alertname": "HighCPUUsage",
        "instance": "server-01:9100",
        "severity": "critical"
      },
      "annotations": {
        "summary": "High CPU usage detected",
        "description": "Instance server-01:9100 CPU usage is above 90% for more than 5 minutes."
      },
      "startsAt": "2026-03-10T09:46:06.815Z",
      "endsAt": "0001-01-01T00:00:00Z",
      "generatorURL": "http://prometheus:9090/graph?g0.expr=...",
      "fingerprint": "34e164e9af873ac1"
    }
  ],
  "groupLabels": {},
  "commonLabels": {
    "alertname": "HighCPUUsage",
    "severity": "critical"
  },
  "commonAnnotations": {
    "summary": "High CPU usage detected"
  },
  "externalURL": "http://alertmanager:9093",
  "version": "4",
  "groupKey": "{}:{}",
  "truncatedAlerts": 0
}
```

**RESOLVE (resolved):**

```json
{
  "receiver": "itoc360-webhook",
  "status": "resolved",
  "alerts": [
    {
      "status": "resolved",
      "labels": {
        "alertname": "HighCPUUsage",
        "severity": "critical"
      },
      "annotations": {
        "summary": "High CPU usage detected"
      },
      "startsAt": "2026-03-10T09:46:06.815Z",
      "endsAt": "2026-03-10T10:01:00.000Z",
      "fingerprint": "34e164e9af873ac1"
    }
  ],
  "version": "4"
}
```

### Field Mapping Reference

| Payload Field                       | Description                                                           |
| ----------------------------------- | --------------------------------------------------------------------- |
| `status`                            | Top-level event type: `firing` → ALERT, `resolved` → RESOLVE          |
| `alerts[0].fingerprint`             | Unique identifier per alert label set — used for fingerprint matching |
| `alerts[0].labels.alertname`        | Name of the alert rule that fired                                     |
| `alerts[0].labels.severity`         | Severity label from the rule definition — used for priority mapping   |
| `alerts[0].annotations.summary`     | Short human-readable alert title                                      |
| `alerts[0].annotations.description` | Detailed description of the alert condition                           |
| `alerts[0].startsAt`                | ISO 8601 timestamp when the alert started firing                      |
| `alerts[0].endsAt`                  | ISO 8601 timestamp when resolved (`0001-...` means still active)      |
| `commonLabels`                      | Labels shared across all alerts in this group                         |
| `commonAnnotations`                 | Annotations shared across all alerts in this group                    |
| `groupKey`                          | Alertmanager grouping key for the delivered alert batch               |

### Priority Mapping

ITOC360 maps the `severity` label from the alert rule to an internal priority level.

| Prometheus `severity` Label | ITOC360 Priority |
| --------------------------- | ---------------- |
| `critical`                  | CRITICAL         |
| `error`                     | HIGH             |
| `warning`                   | MEDIUM           |
| `info`                      | LOW              |
| *(not set)*                 | MEDIUM (default) |

> You control the `severity` label in your alert rule definitions. Use consistent values across your rule files for predictable priority routing.

### RESOLVE Detection

ITOC360 automatically resolves an alert when Alertmanager sends a payload with `"status": "resolved"`. This requires `send_resolved: true` in your Alertmanager webhook configuration (set in Step 2).

The resolved event is matched to the original alert using the `fingerprint` field, which Alertmanager generates deterministically from the alert's label set. As long as the labels do not change between firing and resolution, the fingerprint will match and the alert will be closed.

### Security

The webhook URL contains a source token generated by ITOC360. Keep this token secret and do not commit it to public repositories. If the token is exposed, rotate it from the ITOC360 source settings.

### Troubleshooting

* If alerts appear in Prometheus but not in ITOC360, open the Alertmanager UI and confirm that the alert is routed to the `itoc360-webhook` receiver.
* If alerts are created but not resolved automatically, verify that `send_resolved: true` is set in `alertmanager.yml`.
* If priority mapping does not work as expected, confirm that the alert rule includes a supported `severity` label.
* Check Alertmanager logs for webhook delivery errors such as invalid URL, timeout, or authentication failure.


# SignalFx Integration

Splunk Observability Cloud (formerly [SignalFx](https://www.splunk.com/en_us/about-splunk/acquisitions/signalfx.html)) is a real-time infrastructure monitoring and alerting platform designed for cloud-native environments. It uses detectors to evaluate metrics against defined conditions and can notify external systems via webhook whenever an alert fires or clears — making it straightforward to route those alerts into ITOC360.

### In ITOC360

Go to Sources, click **Create Source**, and select **SignalFx** from the list. Once the source is created, copy the webhook URL and token from the source detail page — you will need these when configuring your detector.

### In Splunk Observability Cloud

#### Step 1 — Create a Detector

In the left sidebar, click **Alerts**, then select **Detectors**. Click **Create detector** in the top right corner and select **Custom detector** from the dropdown.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FggWOF6hINjj4fRS1RKlp%2Fimage%20(123).png?alt=media&amp;token=fef21800-dfc5-4e62-82c3-c67a7a98b14f" alt=""><figcaption></figcaption></figure>

In the **Alert signal** step, enter the metric you want to monitor in the signal field. Use the **Add filter** button to narrow the signal down to a specific host, datacenter, or dimension — this keeps each alert tied to a single incident and makes resolution tracking reliable.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FYWw6NGYUm8fDCqGnBk6k%2Fimage%20(124).png?alt=media&amp;token=6d7f80aa-df11-42e4-8785-e87eec868586" alt=""><figcaption></figcaption></figure>

Work through the remaining steps — set your alert condition, configure alert settings, and customize the alert message as needed. When you reach the **Alert notifications** step, click **Add recipient**, select **Webhook** from the dropdown, and then click **Custom...**.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FfG8bYcDpfH9Q53cNJ83a%2Fimage%20(125).png?alt=media&amp;token=c4f5a88d-04d1-41e1-938b-38ebef47cc54" alt=""><figcaption></figcaption></figure>

#### Step 2 — Configure the Webhook

In the **Webhook Notification** modal that appears, paste your ITOC360 webhook URL into the **URL** field, appending your source token as a query parameter:

```
https://api.itoc360.app/functions/v1/events?token=<x-itoc360-token>
```

Leave the **Shared secret** field empty. Click **Update** to save the webhook.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FSXb09CbWdQZMjpGGcwRb%2Fimage%20(126).png?alt=media&amp;token=a42fe9c3-7958-437c-bc9b-7e63330f9d15" alt=""><figcaption></figcaption></figure>

Click **Proceed To Alert Activation**, give your detector a name, and click **Activate**. The detector will immediately begin monitoring the signal and send notifications to ITOC360 whenever the alert condition is met or cleared.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FzAlh5UP5ixRXlLuA0SPp%2Fimage%20(127).png?alt=media&amp;token=598a038a-c07d-47c3-ac8d-2b568e879b91" alt=""><figcaption></figcaption></figure>

***

### Notes

* Splunk Observability Cloud sends a separate notification for each unique dimension combination that matches your signal. If you want a single alert per detector, use the **Add filter** option to target a specific host or instance.
* Alerts are automatically resolved in ITOC360 when the detector sends a notification with `statusExtended` set to `ok`, `manually resolved`, or `stopped`.
* The **Shared secret** field in SignalFx is used for HMAC-SHA1 request signing and is separate from your itoc360 source token. You do not need to fill it in for ITOC360 to work.


# SigNoz Integration

### Overview

[SigNoz](https://signoz.io/) is an open-source observability platform built on OpenTelemetry. It provides unified APM, logs, traces, metrics, and alerting in a single tool — a self-hostable alternative to Datadog and New Relic. SigNoz includes a built-in Alertmanager, so no external Alertmanager deployment is required. When alert thresholds are breached, SigNoz delivers a structured webhook payload directly to the platform. Resolved events are sent automatically when the condition clears.

This integration supports automatic alert creation on firing events and automatic resolution when SigNoz sends a resolved notification.

### Integration Flow

1. You define alert rules in SigNoz based on metrics, logs, or traces.
2. SigNoz evaluates these rules continuously against incoming telemetry data.
3. When a rule condition is met, the built-in Alertmanager routes the alert to configured notification channels.
4. The platform receives a webhook POST request and creates an alert.
5. When the condition clears, SigNoz automatically sends a `resolved` notification and the platform closes the alert.

***

### Webhook Payload Schema

The payload follows the standard Prometheus Alertmanager webhook format (version 4). SigNoz adds a `message` field inside `annotations` alongside the standard `summary` and `description`.

```json
{
  "receiver": "string",
  "status": "firing | resolved",
  "alerts": [
    {
      "status": "firing | resolved",
      "labels": {
        "alertname": "string",
        "severity": "string"
      },
      "annotations": {
        "summary": "string",
        "description": "string",
        "message": "string"
      },
      "startsAt": "ISO8601 timestamp",
      "endsAt": "ISO8601 timestamp",
      "generatorURL": "string",
      "fingerprint": "string"
    }
  ],
  "groupLabels": {
    "alertname": "string",
    "severity": "string"
  },
  "commonLabels": {
    "alertname": "string",
    "severity": "string"
  },
  "commonAnnotations": {
    "summary": "string",
    "description": "string",
    "message": "string"
  },
  "externalURL": "string",
  "version": "4",
  "groupKey": "string",
  "truncatedAlerts": 0
}
```

### Setup

#### Step 1 — Create an Alert Source on the Platform

1. Navigate to **Sources** → **Add Source**.
2. Search for **SigNoz** and select it.
3. Give the source a name and click **Save**.
4. Copy the <https://api.itoc360.app/functions/v1/events> URL.

#### Step 2 — Navigate to Notification Channels in SigNoz

In your SigNoz instance, click **Settings** at the bottom of the left sidebar, then select **Notification Channels**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FK4vH6Z5hBrhdpBJyCnBP%2FEkran%20Resmi%202026-03-10%2016.59.50.png?alt=media&amp;token=664cd58e-e2de-4f13-8499-8f349f06e39f" alt=""><figcaption></figcaption></figure>

SigNoz sidebar with Settings menu highlighted at the bottom left

On the Notification Channels page, click **New Alert Channel**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FIDrJSZwrTqcxw1V5FlHF%2Fimage%20(88).png?alt=media&amp;token=120dd4d5-346e-4da3-aa57-ab7befa4c915" alt=""><figcaption></figcaption></figure>

&#x20;Notification Channels page (empty state) with the "New Alert Channel" button in the top right corner

#### Step 3 — Configure the Webhook Channel

Fill in the New Notification Channel form as follows:

* **Name**: Give the channel a descriptive name (e.g. `ITOC360`)
* **Send resolved alerts**: Toggle **ON** — this is required for automatic alert resolution on the platform
* **Type**: Select `Webhook`
* **Webhook URL**: Paste the <https://api.itoc360.app/functions/v1/events> URL
* **User Name**: Leave empty
* **Password**: Paste your **Token** from the platform (SigNoz uses this as a bearer token)

Click **Test** to verify connectivity, then click **Save**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FeKM5DzaVYmLwv47TZDCl%2FEkran%20Resmi%202026-03-10%2017.01.33.png?alt=media&amp;token=4f88c744-48a6-4a71-8a07-a6da650f7f8f" alt=""><figcaption></figcaption></figure>

New Notification Channel form filled with ITOC360 name, Webhook type, and the platform webhook URL

***

#### Step 4 — Verify the Channel Was Saved

After saving, the channel appears in the Notification Channels list with type `webhook`.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FU9NjeY0sj8lzpQODmj71%2Fimage%20(89).png?alt=media&amp;token=397776d8-a06c-4a53-8268-d2cc414a8898" alt=""><figcaption></figcaption></figure>

Notification Channels list showing the ITOC360 webhook channel with Edit and Delete actions

#### Step 5 — Assign the Channel to an Alert Rule

When creating or editing an alert rule in SigNoz (**Alerts** → **New Alert**), select the notification channel you created under **Notification Channels**. The alert will be routed to the platform when it fires.

#### Step 6 — Verify the Integration

Use the **Test** button on the notification channel to send a test payload. Confirm the alert appears on the platform under the source you created.

### Sample Payload

The following is a real payload captured during integration testing.

**ALERT (firing):**

```json
{
  "receiver": "ITOC360",
  "status": "firing",
  "alerts": [
    {
      "status": "firing",
      "labels": {
        "alertname": "Test Alert (ITOC360)",
        "severity": "critical"
      },
      "annotations": {
        "description": "Test alert fired from SigNoz",
        "message": "Test alert fired from SigNoz",
        "summary": "Test alert fired from SigNoz"
      },
      "startsAt": "2026-03-10T13:53:07.6738108Z",
      "endsAt": "0001-01-01T00:00:00Z",
      "generatorURL": "",
      "fingerprint": "e2947ae7eec5295f"
    }
  ],
  "groupLabels": {
    "alertname": "Test Alert (ITOC360)",
    "severity": "critical"
  },
  "commonLabels": {
    "alertname": "Test Alert (ITOC360)",
    "severity": "critical"
  },
  "commonAnnotations": {
    "description": "Test alert fired from SigNoz",
    "message": "Test alert fired from SigNoz",
    "summary": "Test alert fired from SigNoz"
  },
  "externalURL": "https://artistic-raccoon.eu2.signoz.cloud",
  "version": "4",
  "groupKey": "ITOC360-e2947ae7eec5295f-1773150787",
  "truncatedAlerts": 0
}
```

**RESOLVE (resolved):**

```json
{
  "receiver": "ITOC360",
  "status": "resolved",
  "alerts": [
    {
      "status": "resolved",
      "labels": {
        "alertname": "Test Alert (ITOC360)",
        "severity": "critical"
      },
      "annotations": {
        "description": "Test alert fired from SigNoz",
        "message": "Test alert fired from SigNoz",
        "summary": "Test alert fired from SigNoz"
      },
      "startsAt": "2026-03-10T13:53:07.6738108Z",
      "endsAt": "2026-03-10T14:10:00.000Z",
      "generatorURL": "",
      "fingerprint": "e2947ae7eec5295f"
    }
  ],
  "groupLabels": {
    "alertname": "Test Alert (ITOC360)",
    "severity": "critical"
  },
  "commonLabels": {
    "alertname": "Test Alert (ITOC360)",
    "severity": "critical"
  },
  "commonAnnotations": {
    "description": "Test alert fired from SigNoz",
    "message": "Test alert fired from SigNoz",
    "summary": "Test alert fired from SigNoz"
  },
  "externalURL": "https://artistic-raccoon.eu2.signoz.cloud",
  "version": "4",
  "groupKey": "ITOC360-e2947ae7eec5295f-1773150787",
  "truncatedAlerts": 0
}
```

***

### Field Mapping Reference

| Payload Field                       | Description                                                                        |
| ----------------------------------- | ---------------------------------------------------------------------------------- |
| `status`                            | Top-level event type: `firing` → ALERT, `resolved` → RESOLVE                       |
| `alerts[0].fingerprint`             | Unique identifier per alert label set — used for fingerprint matching              |
| `alerts[0].labels.alertname`        | Name of the alert rule that fired                                                  |
| `alerts[0].labels.severity`         | Severity label from the rule definition — used for priority mapping                |
| `alerts[0].annotations.summary`     | Short human-readable alert title                                                   |
| `alerts[0].annotations.description` | Detailed description of the alert condition                                        |
| `alerts[0].annotations.message`     | Additional message field specific to SigNoz (same value as summary in test alerts) |
| `alerts[0].startsAt`                | ISO 8601 timestamp when the alert started firing                                   |
| `alerts[0].endsAt`                  | ISO 8601 timestamp when resolved (`0001-...` means still active)                   |
| `commonLabels`                      | Labels shared across all alerts in this group                                      |
| `commonAnnotations`                 | Annotations shared across all alerts in this group                                 |
| `externalURL`                       | URL of the SigNoz instance that sent the alert                                     |
| `groupKey`                          | SigNoz-specific group key used for alert deduplication                             |

### Priority Mapping

The platform maps the `severity` label from the alert rule to an internal priority level.

| SigNoz `severity` Label | Platform Priority |
| ----------------------- | ----------------- |
| `critical`              | CRITICAL          |
| `error`                 | HIGH              |
| `warning`               | MEDIUM            |
| `info`                  | LOW               |
| *(not set)*             | MEDIUM (default)  |

> The `severity` label is set in your SigNoz alert rule definition. It is a required field when creating alerts in SigNoz.

### RESOLVE Detection

The platform automatically resolves an alert when SigNoz sends a payload with `"status": "resolved"`. This requires the **Send resolved alerts** toggle to be enabled on the notification channel (set in Step 3).

The resolved event is matched to the original alert using the `fingerprint` field, which SigNoz generates deterministically from the alert's label set. As long as the labels do not change between firing and resolution, the fingerprint will match and the alert will be closed automatically.


# Site24x7 Integration

### Overview

[Site24x7](https://www.site24x7.com/) provides cloud-based performance monitoring for servers, networks, and websites.

To connect Site24x7 with ITOC360, we use a Custom Webhook. Instead of using Site24x7's default payload, which contains unnecessary logs, we configure it to send a custom JSON template. This ensures the incoming data perfectly matches our Event ➔ Alert ➔ Incident architecture. When ITOC360 receives the payload, it uses the `Status` and `Severity` fields to map the priority and determine whether to trigger an alert or resolve an existing one.

### Provider Configuration & Mapping

When Site24x7 sends a webhook, we extract the exact status using JSONPath.

Priority Mapping Config:

JSON

```
{
  "priority": {
    "field": "$.Severity",
    "options": [
      { "value": "DOWN", "label": "Down" },
      { "value": "CRITICAL", "label": "Critical" },
      { "value": "TROUBLE", "label": "Trouble" }
    ],
    "mapping": {
      "DOWN": "CRITICAL",
      "CRITICAL": "HIGH",
      "TROUBLE": "MEDIUM"
    }
  }
}
```

Event Type Mapping:

* `$.Status == "DOWN"` | `"CRITICAL"` | `"TROUBLE"` ➔ `EventType: ALERT`
* `$.Status == "UP"` ➔ `EventType: RESOLVE`

Correlation (Fingerprint): We use `$.IncidentNumber` (which pulls from Site24x7's `$MONITOR_ID`). This is the unique key that links an active alert to its recovery event.

***

### Setup Instructions

#### Step 1: Get Your Webhook URL

1. Log in to your alert management platform.
2. Go to Sources → Add Source.
3. Select Site24x7 as your provider.
4. Save the configuration and copy the generated Webhook URL.

#### Step 2: Add the Webhook in Site24x7

1. Log in to your Site24x7 account.
2. On the left sidebar, scroll down and click Admin.
3. Click on Third-Party Integrations.
4. From the list of available integrations, select Webhooks.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F0TSdNhNgq3kQPtdD9a13%2Fimage%20(12)%20(1).png?alt=media&amp;token=6c0996fb-ac52-4bb9-993c-7974b0b67b3d" alt=""><figcaption></figcaption></figure>

#### Step 3: Configure the Payload

Fill out the integration form to match ITOC360's requirements.

1. Integration Name: Type a recognizable name (e.g., `ITOC360`).
2. Hook URL: <https://api.itoc360.app/functions/v1/events>
3. HTTP Method: Leave this as `POST`.
4. Post as JSON: Check this box.
5. Send Incident Parameters: Uncheck this box to disable the default payload.
6. Send Custom Parameters: Check this box. A text area will appear. Paste the following JSON structure exactly as shown:

JSON

```
{
  "IncidentName": "$MONITOR_NAME",
  "IncidentNumber": "$MONITOR_ID",
  "Status": "$STATUS",
  "Severity": "$STATUS",
  "Description": "$INCIDENT_REASON",
  "MonitorUrl": "$MONITORURL",
  "Time": "$TIME"
}
```

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FyxqFKAcRv3thNVie1sSN%2Fimage%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=5b78b537-0b36-4e59-8571-332e35d13a2d" alt=""><figcaption></figcaption></figure>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F7C8Vh2dvdbLVyuk1Yeps%2Fimage%20(2)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=aa81d9a9-042e-459d-9384-236b1b15a581" alt=""><figcaption></figcaption></figure>

#### Step 4: Select Triggers and Save

Scroll down to the bottom of the form to define when Site24x7 should send alerts.

1. Under Trigger Alerts for Monitor Status Change, make sure you check Down, Trouble, and Critical. *(Note: Site24x7 automatically sends recovery/UP signals, so you don't need to check a box for it here).*
2. Click Save and Test to finish the setup and send a sample payload to your platform.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FzOih8tWubKmJ6Mi5hgDj%2FEkran%20Resmi%202026-02-25%2021.51.02.png?alt=media&amp;token=b5bfa0f7-90ce-4ad7-a0c4-57a04819cd1d" alt=""><figcaption></figcaption></figure>

### Testing the Integration

When you click Save and Test, Site24x7 immediately fires a mock payload.

1. Check your platform's incoming logs or alerts dashboard.
2. You should see a new event with `Status: "DOWN"` and a description like "Service Unavailable".
3. Confirm that the platform successfully parsed this event and created an Incident with a `CRITICAL` priority.

### Troubleshooting

If the integration does not work as expected, use the following checks to identify the issue.

#### No event appears in ITOC360

* Make sure the Hook URL copied from ITOC360 is pasted correctly in Site24x7.
* Verify that the HTTP Method is set to `POST`.
* Make sure `Post as JSON` is enabled.
* Make sure `Send Custom Parameters` is enabled.
* Confirm that the custom JSON payload is pasted exactly as shown in the setup instructions.
* Click `Save and Test` in Site24x7 and check whether a test event reaches ITOC360.

#### Alerts are not created

* Confirm that the `Status` field is included in the custom JSON payload.
* Make sure the `Status` value is one of the supported alert statuses: `DOWN`, `CRITICAL`, or `TROUBLE`.
* Check that the event type mapping is configured correctly:
  * `DOWN`, `CRITICAL`, `TROUBLE` → `ALERT`
  * `UP` → `RESOLVE`
* Check the incoming event logs in ITOC360 to verify that the payload was received and parsed successfully.

#### Incidents are not resolved automatically

* Confirm that Site24x7 sends an `UP` status when the monitor recovers.
* Make sure the `IncidentNumber` field is included in both alert and recovery payloads.
* Verify that `IncidentNumber` is mapped from `$MONITOR_ID`.
* ITOC360 uses `IncidentNumber` as the correlation key, so the value must stay the same between the alert event and the recovery event.

#### Priority is not mapped correctly

* Confirm that the `Severity` field is included in the custom JSON payload.
* Make sure `Severity` is populated from `$STATUS`.
* Verify that the received value matches one of the configured priority mapping options: `DOWN`, `CRITICAL`, or `TROUBLE`.

#### Webhook test succeeds but real alerts do not appear

* Make sure the integration is assigned to the correct monitors, monitor groups, or all monitors.
* Under `Trigger Alerts for Monitor Status Change`, confirm that `Down`, `Trouble`, and `Critical` are selected.
* Check whether the monitor actually entered one of the selected statuses.
* Review the Site24x7 alert history to confirm that the webhook was triggered.


# VictoriaMetrics Integration

### Overview

[VictoriaMetrics](https://victoriametrics.com/) is a fast, cost-effective, and scalable time-series database. Alert rules are evaluated by **vmalert**, which fires notifications to a configured **Alertmanager** instance. Alertmanager then groups the alerts and delivers a webhook payload to the platform.

This integration supports automatic alert creation on firing events and automatic resolution when Alertmanager sends a `resolved` notification.

### Integration Flow

1. VictoriaMetrics ingests and stores metrics from your scrapers (vmagent, Prometheus, etc.).
2. **vmalert** continuously evaluates your alert rules against VictoriaMetrics. When a rule's condition is met, it pushes the alert to Alertmanager.
3. Alertmanager groups the alerts and delivers a webhook POST request to the platform endpoint.
4. When the alert condition clears, Alertmanager sends a `resolved` notification and the platform automatically closes the alert.

### Webhook Payload Schema

The payload delivered to the platform follows the standard Alertmanager webhook format (version 4), since vmalert uses the Alertmanager protocol natively.

```json
{
  "receiver": "string",
  "status": "firing | resolved",
  "alerts": [
    {
      "status": "firing | resolved",
      "labels": {
        "alertname": "string",
        "severity": "string",
        "cluster": "string"
      },
      "annotations": {
        "summary": "string",
        "description": "string"
      },
      "startsAt": "ISO8601 timestamp",
      "endsAt": "ISO8601 timestamp",
      "generatorURL": "string",
      "fingerprint": "string"
    }
  ],
  "groupLabels": {},
  "commonLabels": {
    "alertname": "string",
    "severity": "string"
  },
  "commonAnnotations": {
    "summary": "string",
    "description": "string"
  },
  "externalURL": "string",
  "version": "4",
  "groupKey": "string",
  "truncatedAlerts": 0
}
```

### Setup

#### Step 1 — Create an Alert Source on the Platform

1. Navigate to **Sources → Add Source**.
2. Search for **VictoriaMetrics** and select it.
3. Give the source a name and click **Save**.
4. Copy the <https://api.itoc360.app/functions/v1/events> **URL** and **Token** — you will need them in the next step.

#### Step 2 — Install and Configure Alertmanager

vmalert does not deliver alerts directly to external systems. You need an Alertmanager instance to receive alerts from vmalert and route them to the platform.

Install Alertmanager using your preferred method (binary, Docker, Helm). Then configure it to forward alerts to the platform:

**alertmanager.yml**

```yaml
global:
  resolve_timeout: 5m

route:
  receiver: itoc360-webhook
  group_wait: 10s
  group_interval: 1m
  repeat_interval: 4h

receivers:
  - name: itoc360-webhook
    webhook_configs:
      - url: "https://api.itoc360.app/functions/v1/events?token=<x-itoc360-token>"
        send_resolved: true
```

> `send_resolved: true` is required for automatic alert resolution on the platform.

#### Step 3 — Run vmalert

vmalert needs three things to operate: a datasource (VictoriaMetrics), a notifier (Alertmanager), and one or more rule files.

**Docker example:**

```bash
docker run -d --name vmalert \
  -p 8880:8880 \
  -v /path/to/rules:/etc/rules \
  victoriametrics/vmalert:latest \
  -rule=/etc/rules/*.yaml \
  -datasource.url=http://<victoriametrics-host>:8428 \
  -remoteWrite.url=http://<victoriametrics-host>:8428 \
  -notifier.url=http://<alertmanager-host>:9093 \
  -evaluationInterval=15s
```

Flag reference:

* `-datasource.url` — VictoriaMetrics endpoint used to evaluate rule expressions.
* `-remoteWrite.url` — where vmalert persists alert state and recording rule results.
* `-notifier.url` — Alertmanager address that will receive the alerts.
* `-rule` — path to your rule files (supports wildcards).

#### Step 4 — Create Alert Rules

vmalert uses the same rule format as Prometheus. Create rule files in the directory you mounted in Step 3.

**Example: rules/production.yaml**

```yaml
groups:
  - name: production-critical
    interval: 1m
    rules:
      - alert: HighCPUUsage
        expr: |
          100 - (avg by (instance) (rate(node_cpu_seconds_total{mode="idle"}[5m])) * 100) > 90
        for: 5m
        labels:
          severity: critical
        annotations:
          summary: "High CPU usage detected"
          description: "Instance {{ $labels.instance }} CPU usage is above 90% for more than 5 minutes."
```

The `severity` label is used by the platform for priority mapping (see table below).

#### Step 5 — Verify the Integration

After starting vmalert and Alertmanager:

1. Open the vmalert UI at `http://<vmalert-host>:8880/vmalert/groups` — your rule groups should be listed and active.
2. Open the Alertmanager UI at `http://<alertmanager-host>:9093` — confirm that firing alerts are routed to the `itoc360-webhook`receiver.
3. Confirm the alert appears on the platform under the source you created in Step 1.

### Sample Payload

The following is a real payload captured during integration testing.

**ALERT (firing):**

```json
{
  "receiver": "itoc360-webhook",
  "status": "firing",
  "alerts": [
    {
      "status": "firing",
      "labels": {
        "alertname": "HighCPUUsage",
        "instance": "vm-server-01:9100",
        "severity": "critical",
        "cluster": "east-1"
      },
      "annotations": {
        "summary": "VictoriaMetrics: High CPU usage detected",
        "description": "Instance vm-server-01:9100 CPU usage is above 90% for more than 5 minutes."
      },
      "startsAt": "2026-04-17T11:30:00.000Z",
      "endsAt": "0001-01-01T00:00:00Z",
      "generatorURL": "http://vmalert:8880/vmalert/alert?group_id=1234567890&alert_id=9876543210",
      "fingerprint": "vmtest34e164e9af873ac1"
    }
  ],
  "groupLabels": {},
  "commonLabels": {
    "alertname": "HighCPUUsage",
    "severity": "critical",
    "cluster": "east-1"
  },
  "commonAnnotations": {
    "summary": "VictoriaMetrics: High CPU usage detected"
  },
  "externalURL": "http://alertmanager:9093",
  "version": "4",
  "groupKey": "{}:{alertname=\"HighCPUUsage\"}",
  "truncatedAlerts": 0
}
```

**RESOLVE (resolved):**

```json
{
  "receiver": "itoc360-webhook",
  "status": "resolved",
  "alerts": [
    {
      "status": "resolved",
      "labels": {
        "alertname": "HighCPUUsage",
        "instance": "vm-server-01:9100",
        "severity": "critical",
        "cluster": "east-1"
      },
      "annotations": {
        "summary": "VictoriaMetrics: High CPU usage detected",
        "description": "Instance vm-server-01:9100 CPU usage is above 90% for more than 5 minutes."
      },
      "startsAt": "2026-04-17T11:30:00.000Z",
      "endsAt": "2026-04-17T11:45:00.000Z",
      "generatorURL": "http://vmalert:8880/vmalert/alert?group_id=1234567890&alert_id=9876543210",
      "fingerprint": "vmtest34e164e9af873ac1"
    }
  ],
  "version": "4"
}
```

### Field Mapping Reference

| Payload Field                       | Description                                                                          |
| ----------------------------------- | ------------------------------------------------------------------------------------ |
| `status`                            | Top-level event type: `firing` → ALERT, `resolved` → RESOLVE                         |
| `alerts[0].fingerprint`             | Unique identifier per alert label set — used for fingerprint matching                |
| `alerts[0].labels.alertname`        | Name of the alert rule that fired                                                    |
| `alerts[0].labels.severity`         | Severity label from the rule definition — used for priority mapping                  |
| `alerts[0].labels.cluster`          | Optional external label set via vmalert `-external.label` flag (useful in HA setups) |
| `alerts[0].annotations.summary`     | Short human-readable alert title                                                     |
| `alerts[0].annotations.description` | Detailed description of the alert condition                                          |
| `alerts[0].startsAt`                | ISO 8601 timestamp when the alert started firing                                     |
| `alerts[0].endsAt`                  | ISO 8601 timestamp when resolved (`0001-...` means still active)                     |
| `alerts[0].generatorURL`            | Link back to the originating rule in the vmalert UI                                  |
| `commonLabels`                      | Labels shared across all alerts in this group                                        |
| `commonAnnotations`                 | Annotations shared across all alerts in this group                                   |
| `groupKey`                          | Alertmanager group key used for deduplication                                        |

### Priority Mapping

The platform maps the `severity` label from your alert rule to an internal priority level.

| VictoriaMetrics `severity` Label | Platform Priority |
| -------------------------------- | ----------------- |
| `critical`                       | CRITICAL          |
| `error`                          | HIGH              |
| `warning`                        | MEDIUM            |
| `info`                           | LOW               |
| (not set)                        | MEDIUM (default)  |

You control the `severity` label in your alert rule definitions. Use consistent values across your rule files for predictable priority routing.

### RESOLVE Detection

The platform automatically resolves an alert when Alertmanager sends a payload with `"status": "resolved"`. This requires `send_resolved: true` in your Alertmanager webhook configuration (set in Step 2).

The resolved event is matched to the original alert using the `fingerprint` field, which Alertmanager generates deterministically from the alert's label set. As long as the labels do not change between firing and resolution, the fingerprint will match and the alert will be closed.


# Cloud Monitoring

This category covers native monitoring services from major cloud providers. These tools track resource consumption, service health, budget thresholds, and platform-level events across AWS, Google Cloud, Azure, and Alibaba Cloud — and forward alerts to ITOC360 when action is required.

***

### Integrations in this category

| Integration              | What it monitors                                | Alert delivery        |
| ------------------------ | ----------------------------------------------- | --------------------- |
| **Amazon CloudWatch**    | AWS resource metrics, logs, alarms              | Webhook (SNS)         |
| **AWS Budget**           | AWS cost and usage thresholds                   | Webhook (SNS)         |
| **AWS GuardDuty**        | Threat detection across AWS accounts            | Webhook (EventBridge) |
| **Google Cloud Monitor** | GCP resource metrics and uptime checks          | Webhook               |
| **Azure Log Alerts**     | Log Analytics query-based alert rules           | Webhook               |
| **Azure Metric Alerts**  | Azure Monitor metric threshold alerts           | Webhook               |
| **Azure Activity Logs**  | Azure subscription-level activity events        | Webhook               |
| **Azure Cost Budget**    | Azure spending threshold alerts                 | Webhook               |
| **Azure Service Health** | Azure platform incidents and maintenance events | Webhook               |
| **Alibaba CloudMonitor** | Alibaba Cloud resource metrics and events       | Webhook               |

***

### How it works

Cloud monitoring services generate alerts when resource metrics, cost thresholds, or platform health events meet defined conditions. These alerts are forwarded to ITOC360 via webhooks — typically through notification channels like AWS SNS, Azure Action Groups, or Google Cloud notification channels. ITOC360 receives the payload, parses the alert details, and routes the incident to the responsible on-call team based on your escalation policies.

{% hint style="info" %}
ITOC360 generates a unique webhook URL per Source. Go to **Management > Sources**, create a Source, and paste the webhook URL into your cloud provider's notification or action group settings.
{% endhint %}

***

### Get started


# Alibaba CloudMonitor Integration

Route threshold-triggered alerts from Alibaba CloudMonitor into itoc360 to automatically open and resolve incidents across your on-call workflow.

### Overview

Alibaba CloudMonitor is the native monitoring and alerting service for Alibaba Cloud resources. It tracks metrics like CPU utilization, memory usage, disk I/O, and network throughput across services such as ECS, RDS, SLB, and more. When a metric crosses a defined threshold, CloudMonitor fires a webhook callback to notify external systems.

The CloudMonitor console gives a centralized view of all active alerts, system events, and resource quota usage across your Alibaba Cloud account.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F4ZYHVZ8H7ra2jzyYjJHe%2Fimage%20(90).png?alt=media&amp;token=73323473-a4cd-4677-911b-bb446074d205" alt=""><figcaption></figcaption></figure>

### Step 1 — Create an Alert Contact

An alert contact holds the destination URL that CloudMonitor will call when an alert fires. In this step, you create a contact that points to your itoc360 source webhook URL.

1. In the CloudMonitor console, expand the **Alerts** section in the left sidebar and click **Alert Contacts**.
2. Switch to the **Alert Contacts** tab and click **+ Create Alert Contact**.
3. Fill in the form:
   * **Name** — enter a recognizable label such as `ITOC360`
   * **Region for Alert Notification Service** — select the region closest to your infrastructure
   * **Slack Webhook (http|https)** — paste the itoc360 source webhook URL, including the token query parameter
   * **Language of Alert Notifications** — set to **English**
4. Click **OK** to save. The approval indicator at the bottom of the form will turn green once the webhook URL passes validation.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FTVgYZzdMwSQyg6FanBXX%2FEkran%20Resmi%202026-03-16%2001.44.04.png?alt=media&amp;token=7a312a63-6a52-4d7c-a287-a363334bbea7" alt=""><figcaption></figcaption></figure>

> **Note:** The webhook URL must be publicly reachable over HTTPS. If you are testing locally, use a tunnel tool such as ngrok first, then swap in your production ITOC360 endpoint when going live.

### Step 2 — Create an Alert Contact Group

Alert rules in CloudMonitor do not reference contacts directly — they reference groups. You need to wrap the contact you just created inside a group before it can receive notifications.

1. Still on the Alert Contacts page, click the **Alert Contact Group** tab.
2. Click **+ Create Alert Contact Group**.
3. Set the **Group Name** to something clear, for example `itoc360-group`.
4. In the contact selector on the left, find the contact you created in Step 1 and move it to the **Selected Contacts** column on the right.
5. Click **Confirm** to save the group.<br>

   <figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FXghAd4rJFUSQKK7l9OHD%2Fimage%20(91).png?alt=media&amp;token=75bfa327-a8ba-4ced-b100-ad4e84770c4f" alt=""><figcaption></figcaption></figure>

### Step 3 — Create an Alert Rule

An alert rule defines which metric to watch, the threshold that triggers a notification, and which contact group receives it. It also carries the callback URL that CloudMonitor POSTs the payload to.

1. In the left sidebar, click **Alert Rules**, then click **+ Create Alert Rule**.
2. Set the following fields in the panel:
   * **Product** — choose the Alibaba Cloud service you want to monitor, for example `Elastic Compute Service (ECS)`
   * **Resource Range** — select **All Resources** to cover every instance, or restrict to specific instances if preferred
   * **Rule Description** — click **+ Add Rule** to define the threshold: pick the metric, comparison operator, threshold value, and alert level (Critical, Warn, or Info)
   * **Alert Contact Group** — select the group created in Step 2
3. Scroll down to **Advanced Settings** and locate the **Alert Callback** field. Paste the same ITOC360 webhook URL here:\
   \*[https://api.itoc360.app/functions/v1/events?token=<](https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>)x-itoc360-token[>](https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>)\
   \*CloudMonitor will POST the alert payload directly to this URL each time the rule fires.
4. Click **Confirm** to activate the rule.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FENu8DE8LTH6b4QgOcwZp%2FEkran%20Resmi%202026-03-16%2001.45.57.png?alt=media&amp;token=69ab021a-c8bc-4a3b-831d-4a9d9e0fb7c2" alt=""><figcaption></figcaption></figure>

> **Note:** Set the **Mute Period** to a value that fits your alert volume. The default 24-hour window means CloudMonitor will not re-notify for the same condition within that period, which helps keep incident noise low.

### Step 4 — Verify the Rule is Active

After saving, the rule appears in the Alert Rules list. The status column should show **Normal** in green, confirming the rule is enabled and CloudMonitor is actively evaluating the metric.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FSsiHcUL6D36kXi72ZV1W%2FEkran%20Resmi%202026-03-16%2001.46.47.png?alt=media&amp;token=6baefdc7-5fd9-4fa7-a0c5-37356251a1e3" alt=""><figcaption></figcaption></figure>

You can trigger a test notification at any time by clicking the **More** menu on the rule row, or by using the **Test** button inside the Alert Callback field when editing the rule. When the test fires, a POST request is sent to the callback URL and the alert should appear in your itoc360 source.

### How Alerts Map to Incidents

itoc360 reads the `alertState` field from the CloudMonitor payload to decide whether to open or resolve an incident:

| CloudMonitor `alertState` | itoc360 Action    |
| ------------------------- | ----------------- |
| `ALERT`                   | Opens incident    |
| `OK`                      | Resolves incident |
| `INSUFFICIENT_DATA`       | Opens incident    |

When the same rule fires again after recovering, a new incident is opened since the previous one is already closed.

### Priority Mapping

itoc360 uses the `triggerLevel` field to determine incident priority:

| CloudMonitor `triggerLevel` | itoc360 Priority |
| --------------------------- | ---------------- |
| `CRITICAL`                  | Critical         |
| `WARN`                      | Medium           |
| `INFO`                      | Low              |

To customize these mappings per source, go to **Sources → Edit → Priority Mapping**.

### Troubleshooting

**Webhook fires but no incident appears in ITOC360**

Check the Supabase Edge Function logs for validation errors. The most common cause is a missing or misnamed field in the callback payload. Confirm that the Alert Callback URL in the rule matches the URL shown on the ITOC360 source page exactly, including the token query parameter.

**Test button returns a non-200 status**

CloudMonitor sends a GET request to verify the host before the first POST. Make sure your endpoint responds to GET requests with a 200. The itoc360 webhook handles this automatically; if you have a proxy or firewall in front of it, ensure GET traffic is also allowed through.

**Alert fires but the incident never resolves**

Automatic resolution requires CloudMonitor to send a follow-up notification with `alertState` set to `OK` when the metric drops back below threshold. Verify that the alert rule does not have an unusually long Mute Period that would delay the recovery notification.


# Azure Activity Logs Integration

Azure Activity Logs track operations performed across your subscription — things like resource creation, deletion, configuration changes, and access events. This integration forwards those events to ITOC360 as alerts so your on-call team gets notified when something significant happens in your Azure environment.

### How it works

Azure Monitor watches for activity log events that match your alert rule. When a match is found, it fires a webhook to ITOC360 via an Action Group. The platform parses the incoming payload and creates an alert automatically.

Since Activity Log alerts don't have a "resolved" state — each event is a one-time occurrence rather than an ongoing condition — every incoming webhook creates a new alert.

### Prerequisites

* An active Azure subscription
* Access to Azure Monitor with sufficient permissions to create alert rules and action groups
* [https://api.itoc360.app/functions/v1/events?token=<](https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>)x-itoc360-token[>](https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>) \
  (available from the Sources page in ITOC360)

### Setup

#### Step 1 — Create an alert rule

Go to **Azure Portal → Monitor → Alerts** and click **+ Create → Alert rule**.

On the **Scope** tab, set the scope level to **Subscription** and select your subscription from the resource browser. Click **Apply**.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FXcGevvrtUZItVVna0oJW%2Fimage%20(98).png?alt=media&amp;token=6082ec54-1494-4210-a895-4dfa941b4386" alt=""><figcaption></figcaption></figure>

#### Step 2 — Configure the condition

On the **Condition** tab, choose **All Administrative operations** as the signal. This covers the broadest range of activity log events. You can narrow it down later if needed — for example, filtering by a specific operation or resource type.

Leave Event Level, Status, and Event initiated by at their defaults unless you want to filter further.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FkjttJneMNTgDfLcWkCOb%2Fimage%20(99).png?alt=media&amp;token=5a8550d0-783f-43d6-a14d-8c7e04d63338" alt=""><figcaption></figcaption></figure>

#### Step 3 — Create an Action Group

On the **Actions** tab, select **Use action groups** and then click **+ Create action group**.

Fill in the basics:

* **Action group name** — something descriptive like `oncall-webhook`
* **Display name** — max 12 characters, e.g. `oncall`
* **Region** — Global works fine here

Move to the **Actions** tab within the action group wizard. Set the action type to **Webhook**, give it a name, and paste your ITOC360 webhook URL:

```
https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>
```

**Important:** Make sure **Enable the common alert schema** is set to **Yes**. If this is left off, the payload structure will differ and the integration won't parse correctly.

Click **OK**, then complete the action group creation.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FdP8TFZeKjEryNSH6YRpw%2Fimage%20(101).png?alt=media&amp;token=dc914d04-0bc8-435a-8170-1dd7c3e16e50" alt=""><figcaption></figcaption></figure>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FdFTBwdt9zLDSMpbWbSWw%2FEkran%20Resmi%202026-03-26%2014.29.36.png?alt=media&amp;token=1cad32f5-deba-48cd-9ce6-6802aa357146" alt=""><figcaption></figcaption></figure>

#### Step 4 — Finish the alert rule

Back on the alert rule wizard, give your rule a name under the **Details** tab — something like `activity-log-oncall`. Set the severity level if relevant (it doesn't affect routing in ITOC360 but helps with Azure's own alerting view).

Click **Review + create**, then **Create**.

Once created, you should see the rule listed as **Enabled** in the alert rules list.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FLnQVIvYNLvG8gcwA8Qo2%2Fimage%20(103).png?alt=media&amp;token=91fc1048-f622-4c97-a4dc-39320a03116f" alt=""><figcaption></figcaption></figure>

### Verifying the integration

The easiest way to test without waiting for a real event is to perform any operation in Azure — editing a resource tag, changing a setting, or similar. This triggers an Administrative activity log event and should fire the webhook within a minute or two.

You can also test directly with a curl request:

```bash
curl -X POST "https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>" \
  -H "Content-Type: application/json" \
  -d '{
    "schemaId": "Microsoft.Insights/activityLogs",
    "data": {
      "status": "Activated",
      "context": {
        "activityLog": {
          "eventSource": "Administrative",
          "eventDataId": "8195a56a-85de-4663-943e-1a2bf401ad94",
          "level": "Warning",
          "operationName": "Microsoft.Insights/actionGroups/write",
          "status": "Started",
          "subscriptionId": "your-subscription-id"
        }
      }
    }
  }'
```

A successful response returns the created event object with a 200 status.

***

### Field mappings

Azure Activity Log alerts use the Common Alert Schema. The platform reads the following fields:

| Azure Field                              | Platform Field                             |
| ---------------------------------------- | ------------------------------------------ |
| `data.context.activityLog.eventDataId`   | Fingerprint — ties together related events |
| `data.context.activityLog.level`         | Priority                                   |
| `data.context.activityLog.operationName` | Alert title                                |
| `data.context.activityLog.eventSource`   | Alert context                              |

#### Level to priority mapping

| Azure Level   | Platform Priority |
| ------------- | ----------------- |
| Critical      | CRITICAL          |
| Error         | HIGH              |
| Warning       | MEDIUM            |
| Informational | LOW               |

***

### Notes

Activity Log alerts don't resolve automatically. Each event is a discrete occurrence, so alerts created from this integration will need to be acknowledged or closed manually in itoc360.

If you want to limit alerts to a specific operation type — for example, only fire when a virtual machine is deleted — you can do so by selecting a more specific signal in the Condition step instead of "All Administrative operations".


# Azure Cost Budget Integration

Azure Cost Management budgets let you define spending thresholds for your subscription or billing account and get notified automatically when those thresholds are crossed. This integration routes those budget alerts to ITOC360 so your team is aware of unexpected cost spikes before they become a problem at the end of the month.

### How it works

You create a budget in Azure Cost Management and configure alert conditions — for example, notify when actual spending reaches 80% or 100% of the budget. When the threshold is breached, Azure fires a webhook to ITOC360 via an Action Group. The platform parses the payload and creates an alert with the budget name, spent amount, and threshold clearly visible in the alert title.

Budget alerts are one-directional — Azure fires a notification when a threshold is crossed, but there is no automatic resolution. Each alert in ITOC360 will need to be acknowledged or closed manually once the situation is addressed.

### Prerequisites

* An active Azure subscription or billing account
* ITOC360 webhook URL and integration token&#x20;
* An Action Group configured with ITOC360 webhook URL (see the Action Group setup section below)

### Part 1 — Set up an Action Group

Before creating the budget, make sure you have an Action Group that points to your ITOC360 endpoint. If you already created one for another Azure integration, you can reuse it — skip to Part 2.

Go to **Azure Portal → Monitor → Action Groups** and click **+ Create**.

On the **Basics** tab:

* **Action group name** — e.g. `itoc360`
* **Display name** — e.g. `itoc360`
* **Region** — choose the region closest to you

On the **Actions** tab, set the action type to **Webhook**, give it a name, and paste your itoc360 webhook URL in the URI field:

```
https://api.itoc360.app/functions/v1/events?token=<x-itoc360-token>
```

Set **Enable the common alert schema** to **Yes** — this is required. Click **OK**, then **Review + create** → **Create**.

### Part 2 — Create a budget

Go to **Azure Portal → Cost Management + Billing → Cost Management → Budgets** and click **+ Add**.

#### Step 1 — Create a budget

On the **Create a budget** tab, fill in the budget details:

* **Name** — give your budget a descriptive name, e.g. `itoc360-monthly-budget`
* **Reset period** — `Monthly` is the most common choice
* **Creation date** — when the budget starts tracking
* **Expiration date** — set this at least a year out
* **Amount** — your monthly spending limit in your billing currency

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FKBrLELjuFSvcFt4OxNkC%2FEkran%20Resmi%202026-03-27%2011.57.38.png?alt=media&amp;token=ee3dc63f-5e03-49a7-9678-8e2c0676e60e" alt=""><figcaption></figcaption></figure>

Click **Next >** to move to the alerts configuration.

#### Step 2 — Set alert conditions

On the **Set alerts** tab, configure when you want to be notified:

Under **Alert conditions**, click the row to add a threshold:

* **Type** — choose `Actual` to alert when real spending crosses the threshold, or `Forecasted` to alert based on projected spend
* **% of budget** — enter the threshold percentage, e.g. `80` for an early warning or `100` for when the budget is fully consumed

You can add multiple rows to get notified at different thresholds — for example, one at 80% forecasted and another at 100% actual.

Under **Alert recipients (email)**, enter at least one email address. This is required by Azure even if you're using an Action Group for the webhook notification.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FFi7PxT0ehSmLnscLXAxQ%2FEkran%20Resmi%202026-03-27%2011.58.36.png?alt=media&amp;token=4b1216f0-05c6-4b0b-964e-40740373f005" alt=""><figcaption></figcaption></figure>

Click **Create** to save the budget.

#### Step 3 — Connect the Action Group to a budget alert rule

Azure's budget creation wizard doesn't expose Action Group selection for billing-account-scoped budgets. To connect your ITOC360 webhook, you need to create an alert rule through Azure Monitor that targets your budget.

Go to **Azure Portal → Monitor → Alerts → + Create → Alert rule**:

1. **Scope** → select your subscription
2. **Condition** → select **Cost Management** signals, choose your budget
3. **Actions** → select your `itoc360` Action Group
4. **Details** → name the rule `budget-alert-oncall`
5. **Review + create** → **Create**

From this point on, whenever your budget threshold is crossed, Azure will fire a webhook to ITOC360 automatically.

### Field mappings

Azure Cost Budget alerts are delivered using the Common Alert Schema with a `monitoringService` of `CostAlerts`. The platform reads the following fields:

| Azure Field                                                          | Platform Field                                         |
| -------------------------------------------------------------------- | ------------------------------------------------------ |
| `data.alertContext.AlertData.BudgetName` + `data.essentials.alertId` | Fingerprint — ties together events for the same budget |
| `data.alertContext.AlertData.ThresholdType`                          | Priority                                               |
| `data.alertContext.AlertData.BudgetName`                             | Alert title (budget name)                              |
| `data.alertContext.AlertData.SpentAmount`                            | Alert title (current spend)                            |
| `data.alertContext.AlertData.BudgetThreshold`                        | Alert title (threshold)                                |

#### Threshold type to priority mapping

| Azure Threshold Type | Platform Priority |
| -------------------- | ----------------- |
| Actual               | HIGH              |
| Forecasted           | MEDIUM            |

Actual spend alerts are treated as HIGH because the threshold has already been crossed. Forecasted alerts are MEDIUM since they represent a projected overage that can still be addressed before it happens.

### Notes

Budget alerts do not resolve automatically. Once a budget alert fires, the corresponding alert in ITOC360 will remain open until it is manually acknowledged or closed.

For better coverage, consider setting up multiple alert conditions on the same budget — for example, a Forecasted alert at 80% as an early warning and an Actual alert at 100% as a final notification. Each threshold triggers a separate webhook and creates a separate alert in ITOC360.

Budgets reset according to the reset period you configured. After a monthly reset, the spending counter starts fresh and previous alerts are no longer relevant — make sure to close any open budget alerts in ITOC360 at the start of a new period.


# Azure Log Alerts Integration

Azure Monitor's log-based alerts fire when a query result crosses a threshold you define. Getting those alerts into your on-call flow means pointing an Action Group at your platform's webhook — the setup takes maybe ten minutes once you know where everything lives.

You'll need Monitor contributor rights on the subscription and the webhook URL from your platform's Integrations page before touching anything in Azure.

### Setting Up the Alert Source

On your platform, go to **Integrations → Inbound Integrations** and add a new Azure Alerts source. The webhook URL gets generated at the end of the wizard — copy it and keep it somewhere handy, you'll paste it into Azure shortly.

### Building the Alert Rule in Azure

In the [Azure Portal](https://portal.azure.com/), open **Monitor → Alerts** and hit **Create → Alert rule**.

**Scope tab** — the first thing Azure asks is what you're watching. Set the scope level to Subscription, then click Select scope. The panel that opens on the right shows your subscriptions and resource groups — pick whichever one makes sense for your use case and confirm.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FY7UdFazgQQaznJ63SyCP%2FEkran%20Resmi%202026-03-03%2012.35.22.png?alt=media&amp;token=d986a954-833b-4472-9205-19d7191a0738" alt=""><figcaption></figcaption></figure>

**Condition tab** — this is where you define what triggers the alert. Signal name controls which activity stream gets monitored; "All Administrative operations" is a reasonable catch-all for tracking write/delete events across your subscription. The chart in the middle will start reflecting historical event data once you pick a signal.

Down below, Alert logic has three dropdowns: Event Level, Status, and Event initiated by. For a first-pass setup, leaving these at "All selected" is totally fine — you can tighten the filters later once you have a feel for what's actually firing.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FnMkyQhvpLfTxtHrJoVav%2Fimage%20(8)%20(1)%20(1).png?alt=media&amp;token=fb598704-afa6-4b01-8e5d-2dc636f944f7" alt=""><figcaption></figcaption></figure>

Click **Next: Actions** when the condition looks right.

### Creating the Action Group

Action groups are Azure's way of bundling together "what happens when this fires." On the Actions tab, create a new one.

**Basics tab** — name it something like `oncall-webhook` (the action group name can be longer, but the display name is capped at 12 characters, so plan accordingly — `webhook` works fine there). Subscription and resource group just need to match wherever you're deploying this, and Region can stay Global.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F4pfoPedpwg5YeqoKESOH%2Fimage%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=131f5e61-b3ed-4ea1-891d-aa8c32e07d25" alt=""><figcaption></figcaption></figure>

**Actions tab** — skip Notifications and jump straight here. Set Action type to **Webhook**, give the action a name like `oncall`, then click the edit icon. A panel slides in from the right with a URI field — paste your platform's webhook URL there. One thing worth double-checking: **Enable the common alert schema** should be flipped to **Yes**. Without it, the payload shape can vary between alert types, which tends to cause parsing issues on the receiving end. Hit OK to close the panel.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FLmhoyupoClG2UpbCdeaf%2FEkran%20Resmi%202026-03-03%2012.43.19.png?alt=media&amp;token=5dff4f42-8ca1-4f47-871d-7af209c6e8ef" alt=""><figcaption></figcaption></figure>

Click **Review + create**, then **Create**.

### Finishing the Alert Rule

Back in the main alert rule wizard, scroll to **Alert rule details** and give the rule a name — something like `activity-log-oncall` is descriptive enough. Set the severity to match the criticality of what you're monitoring, then click **Create alert rule**.

Once it saves, the rule shows up in your alert rules list with status Enabled. That's the signal that everything is wired up correctly.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FtlzjlGYM33brBGuMsGlZ%2Fimage%20(2)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=5dc5e91f-f99d-412c-bc58-97af41855fa1" alt=""><figcaption></figcaption></figure>

### A Few Things Worth Knowing

Azure log alerts don't send a resolve notification when the condition clears — incidents created through this integration will need to be closed manually from your platform. This is an Azure limitation, not a platform one.

If the webhook stops receiving events, the most common culprit is the common alert schema being disabled on the action. Also worth checking: the action group is still attached to the alert rule (Azure sometimes detaches it if the group gets edited after the rule is saved).

The same action group can be reused across multiple alert rules — no need to recreate it each time you add a new rule.


# Azure Metric Alerts Integration

## Azure Metric Alerts — Webhook Integration

Azure Monitor lets you fire alerts when any resource metric crosses a threshold — CPU usage, storage capacity, request latency, whatever you're tracking. Those alerts can hit a webhook endpoint directly via Action Groups, which is how we get them into the on-call platform.

This guide walks through setting up a Storage Account metric alert as an example. The same steps apply to any other Azure resource type.

### 1. Create a Storage Account (if you don't have one)

You need at least one Azure resource to attach a metric alert to. A Storage Account works well for testing — it's free to create and always has measurable metrics.

Go to **Azure Portal** → search **Storage accounts** → **+ Create**. Fill in the basics (subscription, resource group, name, region) and click through to **Review + create**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FmobNnpWX4USI2skEyDLp%2FEkran%20Resmi%202026-03-03%2017.39.03.png?alt=media&amp;token=e4e6440b-91f7-4b29-9c19-d2e07ebf4365" alt=""><figcaption></figcaption></figure>

Hit **Create**. Once the deployment finishes you'll see this:

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FQCJ23FIDtQoMVFexg8LH%2FEkran%20Resmi%202026-03-03%2017.40.42.png?alt=media&amp;token=f0f268d6-52ae-437f-b839-9f94b0dd34ef" alt=""><figcaption></figcaption></figure>

Click **Go to resource** to open the storage account.

### 2. Create the alert rule

From the storage account overview, go to **Monitor → Alerts** in the left panel, then **+ Create → Alert rule**. On the **Scope** tab, click **Select scope** — a panel slides in on the right. Find your storage account in the list, check it, and hit **Apply**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F4GCbUzi8LJAunAOUKjXg%2FEkran%20Resmi%202026-03-03%2017.42.43.png?alt=media&amp;token=347d236c-9982-4b0f-a77f-b433d338c619" alt=""><figcaption></figcaption></figure>

### 3. Set the condition

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FR6MrokTsgA7Bb9EIFbE5%2Fimage%20(80).png?alt=media&amp;token=54d094fb-c3ad-4ed9-866c-2003abdef233" alt=""><figcaption></figcaption></figure>

Switch to the **Condition** tab. Click **Select a signal** — a search panel opens. Type `used` and select **Used capacity** from the results.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fdn6WP979JURKa6QPHpaK%2Fimage%20(80).png?alt=media&amp;token=3cfa9059-acdf-4258-892d-b5a936d95acb" alt=""><figcaption></figcaption></figure>

On the condition configuration screen, set the threshold to whatever makes sense for your alert. For a quick test, **Greater than 0 bytes** works fine since any data in the account will trigger it.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FaXEh3pbwLR6OxOlPRJr4%2Fimage%20(81).png?alt=media&amp;token=39d91698-d323-40fb-b5fc-5d0bf07196b1" alt=""><figcaption></figcaption></figure>

Click **Next: Actions**.

### 4. Create the action group

On the **Actions** tab, select **Use action groups**, then **+ Create action group**. Give it a name — something like `OnCall-Webhook-Group` — and set a short display name.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FdtdvkCKF1JcGWIhlM5fH%2FEkran%20Resmi%202026-03-03%2017.50.00.png?alt=media&amp;token=c47cebdd-555f-4678-af3b-c1a11f59d4ed" alt=""><figcaption></figcaption></figure>

Click through to the **Actions** tab within the action group form. Set **Action type** to **Webhook**, give it a name like `TriggerWebhook`, and paste your on-call platform webhook URL into the **URI** field. Make sure **Enable the common alert schema** is set to **Yes** — this standardizes the payload format across all Azure alert types.

Hit **OK**, then **Review + create** → **Create**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FiAMR3BgCBc5yumzMj90H%2FEkran%20Resmi%202026-03-03%2017.50.58.png?alt=media&amp;token=ebd323d0-6a33-4888-ae3f-f6b04234225b" alt=""><figcaption></figcaption></figure>

Back in the alert rule form, you'll see a panel to select from existing action groups. Pick **OnCall-Webhook-Group** and click **Select**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FzuA9mle4Eo83YgVnLr4i%2FEkran%20Resmi%202026-03-03%2017.52.16.png?alt=media&amp;token=c282db4e-57cd-4354-8c11-f0ecf56c215e" alt=""><figcaption></figcaption></figure>

### 5. Name the alert rule

On the **Details** tab, give the alert rule a descriptive name. Set the severity level to match what this alert means for your environment.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FsXp24y5W2nWDHnnYyUjk%2FEkran%20Resmi%202026-03-03%2017.53.13.png?alt=media&amp;token=4ddf874f-9664-41c1-934a-b294f90098df" alt=""><figcaption></figcaption></figure>

Click **Review + create** → **Create**.

### 6. Verify the action group

To confirm the webhook URL is correctly set, go to **Monitor → Alerts → Action groups** and open **OnCall-Webhook-Group**. The Actions section should show the webhook entry with your [https://api.itoc360.app/functions/v1/events?token=\<x-itoc360-token>](https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>) URL.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FdaEr2abDUXFaFJsNGJ94%2FEkran%20Resmi%202026-03-03%2017.54.55.png?alt=media&amp;token=b8edc6fa-932a-4047-b456-358d8945ed71" alt=""><figcaption></figcaption></figure>

That's it. When the metric condition is met, Azure will POST the alert payload to your webhook URL and the on-call platform will create an alert automatically.

### Field mappings

Azure Metric alerts use the Common Alert Schema. The platform reads the following fields:

| Azure Field                        | Platform Field                                                           |
| ---------------------------------- | ------------------------------------------------------------------------ |
| `data.essentials.alertId`          | Fingerprint — ties together fired and resolved events for the same alert |
| `data.essentials.monitorCondition` | `Fired` → ALERT, `Resolved` → RESOLVE                                    |
| `data.essentials.severity`         | Priority                                                                 |
| `data.essentials.alertRule`        | Alert title                                                              |

Severity to priority mapping:

| Azure Severity | Platform Priority |
| -------------- | ----------------- |
| Sev0           | CRITICAL          |
| Sev1           | HIGH              |
| Sev2           | MEDIUM            |
| Sev3           | LOW               |
| Sev4           | LOW               |

**Will alerts resolve automatically?** Yes — when the metric condition clears, Azure fires another webhook with `monitorCondition: Resolved` and the platform closes the alert.


# Azure Service Health Integration

Azure Service Health keeps you informed about incidents, planned maintenance windows, and health advisories that affect the Azure services your workloads depend on. This integration routes those notifications to ITOC360 so your on-call team is looped in automatically when something impacts your Azure environment.

### How it works

When a Service Health event occurs — such as a service outage or upcoming maintenance — Azure fires a webhook to ITOC360 via an Action Group. The platform parses the payload and creates an alert. When the issue is resolved on Azure's end, a follow-up webhook with `stage: Resolved` closes the alert automatically.

### Prerequisites

* An active Azure subscription
* Your ITOC360 webhook URL and integration token (available from the Sources page in ITOC360)

### Setup

#### Step 1 — Navigate to Service Health

In the Azure Portal, search for **Service Health** in the top search bar and open it. You'll land on the Service issues view. From here, click **+ Create service health alert** in the toolbar.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FCkDbxctRiCnrybnJOi1C%2Fimage%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=f07e0b12-2a45-4bce-b4ca-4134406b0a2b" alt=""><figcaption></figcaption></figure>

#### Step 2 — Configure the scope

On the **Scope** tab, set the scope level to **Subscription** and select your subscription from the resource browser. Click **Apply**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FAnbyh5GUfZnjMADPvuGb%2FEkran%20Resmi%202026-03-26%2016.45.13.png?alt=media&amp;token=1ba1c8cc-5a70-40ea-8ed8-7bc88d0302bc" alt=""><figcaption></figcaption></figure>

#### Step 3 — Configure the condition

On the **Condition** tab, the signal is automatically set to **Service health** — you don't need to change this. Configure the following:

* **Services** — leave as all services so you catch events across your entire subscription
* **Regions** — leave as all regions, or narrow down to the regions your workloads run in
* **Event types** — select the event types you want to be alerted on: Service issue, Planned maintenance, Health advisories, Security advisories<br>

  <figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FuUDwFWmueyJOcK42r2xw%2Fimage%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=9c256544-249d-411c-8626-dcc48f7b52af" alt=""><figcaption></figcaption></figure>

#### Step 4 — Set up an Action Group

On the **Actions** tab, select **Use action groups** and click **+ Create action group**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fdpm6xRdKbFLlsknG4jIE%2FEkran%20Resmi%202026-03-26%2016.37.59.png?alt=media&amp;token=24276d36-d831-41cf-b963-53c2fc5d3cd5" alt=""><figcaption></figcaption></figure>

\
On the **Basics** tab of the action group wizard, fill in the details:

* **Action group name** — e.g. `itoc360`
* **Display name** — e.g. `itoc360` (max 12 characters)
* **Region** — choose the region closest to you

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fg9guDYh1Si94wfVRHKnR%2FEkran%20Resmi%202026-03-26%2016.39.51.png?alt=media&amp;token=262129c7-f8ec-4b5e-ba29-d77a0c98f154" alt=""><figcaption></figcaption></figure>

Move to the **Actions** tab. Click the **Action type** dropdown and select **Webhook**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fsg02tkgJybZh3t8h3Qg6%2Fimage%20(2)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=ffe7bcfa-66bb-4658-b8a6-335d1c8216ea" alt=""><figcaption></figcaption></figure>

A side panel will open. Paste your ITOC360 webhook URL in the **URI** field:

```
https://api.itoc360.app/functions/v1/events?token=<x-itoc360-token>
```

Make sure **Enable the common alert schema** is set to **Yes** — this is required for the integration to parse the payload correctly. Click **OK**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FR2t5y4JarzMdMmXb0zCO%2FEkran%20Resmi%202026-03-26%2016.40.59.png?alt=media&amp;token=2396dd12-0b70-4315-a4d9-5ddf1d1d287c" alt=""><figcaption></figcaption></figure>

Review the action group summary and click **Create**.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FXenP1IR0jlE09HHKWeds%2FEkran%20Resmi%202026-03-26%2016.41.41.png?alt=media&amp;token=0a963478-71fc-41f7-97bb-5270aeb865d2" alt=""><figcaption></figcaption></figure>

#### Step 5 — Finish the alert rule

Back on the alert rule wizard, move to the **Details** tab. Give your rule a name like `service-health-oncall`. Click **Review + create**, then **Create**.

### Verifying the integration

You can test the integration with a curl request without waiting for a real Azure service event:

```bash
curl -X POST "https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>" \
  -H "Content-Type: application/json" \
  -d '{
    "schemaId": "Microsoft.Insights/activityLogs",
    "data": {
      "status": "Activated",
      "context": {
        "activityLog": {
          "eventSource": "ServiceHealth",
          "eventDataId": "6fa98c0f-334a-b066-1934-1a4b3d929856",
          "level": "Informational",
          "operationName": "Microsoft.ServiceHealth/incident/action",
          "properties": {
            "title": "Virtual Machines - West Europe",
            "service": "Virtual Machines",
            "region": "West Europe",
            "incidentType": "Incident",
            "stage": "Active"
          }
        }
      }
    }
  }'
```

A successful response returns the created event object with a 200 status. To test automatic resolution, send the same payload with `"stage": "Resolved"`.

### Field mappings

Azure Service Health alerts are delivered using the Common Alert Schema with an `eventSource` of `ServiceHealth`. The platform reads the following fields:

| Azure Field                                        | Platform Field                                                    |
| -------------------------------------------------- | ----------------------------------------------------------------- |
| `data.context.activityLog.eventDataId`             | Fingerprint — ties together alert and resolve events              |
| `data.context.activityLog.properties.stage`        | Alert type — `Active` triggers ALERT, `Resolved` triggers RESOLVE |
| `data.context.activityLog.properties.incidentType` | Priority                                                          |
| `data.context.activityLog.properties.title`        | Alert title                                                       |

#### Incident type to priority mapping

| Azure Incident Type | Platform Priority |
| ------------------- | ----------------- |
| Incident            | HIGH              |
| ActionRequired      | HIGH              |
| Security            | CRITICAL          |
| Maintenance         | LOW               |
| Informational       | LOW               |

### Notes

Service Health alerts resolve automatically. When Azure marks an incident as resolved, the platform receives a follow-up webhook and closes the corresponding alert in ITOC360 without any manual action.

If you want to be notified only about specific event types — for example, only active incidents and not maintenance windows — adjust the **Event types** selection in the Condition step accordingly.


# AWS Budget Integration

### Overview

AWS Budgets lets you set spending thresholds on your AWS account and get notified when your actual or forecasted costs cross those limits. The alerts don't come directly as webhooks — they travel through Amazon SNS first, which wraps everything in an envelope and delivers it to your endpoint as an HTTP POST.

The `Message` field inside that envelope is a JSON-encoded string containing the real alert details: budget name, spend amounts, notification type, and the billing period. The platform parses this automatically, so you don't have to do anything special on your end.

One thing worth knowing upfront: AWS Budgets only fires when a threshold is crossed. There's no recovery notification when spending drops back down — so alerts created by this integration will need to be closed manually in the platform after you've reviewed them.

***

### Integration Flow

```
AWS Budgets
│
│ Threshold exceeded
▼
Amazon SNS Topic
│
│ HTTPS subscription delivers payload
▼
Platform Webhook Endpoint
│
│ SNS envelope parsed → Message field decoded
│ Fingerprint: md5(BudgetName::AccountId)
▼
Alert Created → Priority mapped → On-Call Team Notified
```

***

### Provider Configuration & Mapping

AWS Budgets uses the same SNS envelope pattern as Amazon CloudWatch — the priority information lives inside a JSON string in the `Message` field, not at the top level. The platform extracts `NotificationType` from the parsed message to determine priority.

**Priority Mapping Config:**

```json
{
  "priority": {
    "field": "_priority",
    "options": [
      { "value": "HIGH", "label": "Actual Spend Exceeded" },
      { "value": "MEDIUM", "label": "Forecasted Spend Exceeded" }
    ],
    "mapping": {
      "HIGH": "HIGH",
      "MEDIUM": "MEDIUM"
    }
  }
}
```

**Priority Mapping Table:**

| NotificationType (inside Message) | Platform Priority | Description                                         |
| --------------------------------- | ----------------- | --------------------------------------------------- |
| `ACTUAL`                          | HIGH              | Real spend has crossed the threshold                |
| `FORECASTED`                      | MEDIUM            | Projected spend is on track to exceed the threshold |

**Fingerprint (Correlation) Field:**\
`md5(BudgetName::AccountId)` — ties all alerts from the same budget in the same account together.

### Alert Payload Example

#### Raised (Actual Spend — OVER\_BUDGET)

This is what arrives at your webhook when actual spending crosses the threshold. The `NotificationType` inside `Message` is `ACTUAL`, which maps to **HIGH** priority.

— *ALARM payload received at webhook.site (Type: Notification, Subject: AWS Budgets Notification)*

```json
{
  "Type": "Notification",
  "MessageId": "4fcbd345-c623-5a4b-baa0-b1643acab804",
  "TopicArn": "arn:aws:sns:us-east-1:288761728549:oncall-budget-alerts",
  "Subject": "AWS Budgets Notification",
  "Message": "{\"AlarmName\":\"test-oncall-budget\",\"AccountId\":\"288761728549\",\"BudgetName\":\"test-oncall-budget\",\"BudgetType\":\"COST\",\"BudgetLimit\":{\"Amount\":\"1.0\",\"Unit\":\"USD\"},\"ActualSpend\":{\"Amount\":\"0.85\",\"Unit\":\"USD\"},\"ForecastedSpend\":{\"Amount\":\"1.20\",\"Unit\":\"USD\"},\"NotificationThreshold\":\"80.0\",\"NotificationType\":\"ACTUAL\",\"AlertType\":\"OVER_BUDGET\",\"TimePeriod\":{\"Start\":\"2026-03-01\",\"End\":\"2026-03-31\"},\"Timestamp\":\"2026-03-04T10:00:00Z\"}",
  "Timestamp": "2026-03-04T09:26:01.834Z",
  "SignatureVersion": "1",
  "Signature": "REDACTED",
  "SigningCertURL": "https://sns.us-east-1.amazonaws.com/SimpleNotificationService-7506a1e35b36ef5a444dd1a8e7cc3ed8.pem",
  "UnsubscribeURL": "https://sns.us-east-1.amazonaws.com/?Action=Unsubscribe&SubscriptionArn=arn:aws:sns:us-east-1:288761728549:oncall-budget-alerts:a2a819e7-cf5d-4981-9a96-b56238145e7c"
}
```

Resulting alert: **Priority → HIGH**, **Type → ALERT**

> AWS Budgets does not send a recovery payload when spending drops below the threshold. Alerts created by this integration must be closed manually in the platform.

***

### Installation & Configuration

#### Step 1: Paste the ITOC360 URL

Head to **Sources → Add Source**, pick **AWS Budgets** as the provider, give it a name like `AWS Budget Alerts – Production`, and hit Save. Copy the <https://api.itoc360.app/functions/v1/events> URL.

#### Step 2: Create an SNS Topic

1. Log in to the **AWS Management Console** and navigate to **Simple Notification Service (SNS) → Topics**.
2. Click **Create topic**, select type **Standard** (not FIFO), and give it a name like `oncall-budget-alerts`.
3. Leave everything else as default and click **Create topic**.
4. Note the **Topic ARN** on the detail page — you'll need this when setting up the budget alert.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FJ2PEPuB0wx2JCetJ3csS%2Fimage%20(8)%20(1).png?alt=media&amp;token=ed167d57-9586-4f86-8eb9-fdad364b4ff8" alt=""><figcaption></figcaption></figure>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FOuAbCpSqdm3iaSHlCd8g%2Fimage%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=4dbd7858-0064-4c84-ab71-09b9b5524bc5" alt=""><figcaption></figcaption></figure>

#### Step 3: Subscribe the Webhook to the SNS Topic

1. On the topic detail page, go to the **Subscriptions** tab and click **Create subscription**.
2. Protocol: **HTTPS**
3. Endpoint: Paste the <https://api.itoc360.app/functions/v1/events> URL.
4. **Enable raw message delivery:** Leave this **unchecked**. The full SNS envelope needs to reach the platform intact.
5. Click **Create subscription**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Ffk1qPqOOItRcethH3xNM%2FEkran%20Resmi%202026-03-04%2014.44.27.png?alt=media&amp;token=2c25ccd9-dcc5-4546-a3be-9465b980b27f" alt=""><figcaption></figcaption></figure>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FxMCKlgCSLsbpKmdA7MAt%2FEkran%20Resmi%202026-03-04%2014.44.27.png?alt=media&amp;token=f3bad50b-b405-4c88-8425-73aa132ee879" alt=""><figcaption></figcaption></figure>

The subscription will show `PendingConfirmation` right away. AWS fires a `SubscriptionConfirmation` payload to your endpoint — open the `SubscribeURL` value from that payload in your browser to confirm it.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FPTgnwDPmMGGuPmjDjXD3%2FEkran%20Resmi%202026-03-04%2014.45.51.png?alt=media&amp;token=fe391e00-e3f0-4956-81d0-162f81169047" alt=""><figcaption></figcaption></figure>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FVh03NAJsYFRV3y4leCyH%2FEkran%20Resmi%202026-03-04%2014.48.50.png?alt=media&amp;token=f67342f4-cd17-4901-aaff-842e94016d1f" alt=""><figcaption></figcaption></figure>

> **Heads up:** The confirmation URL expires in about 3 minutes. If you see `Invalid token`, go to the Subscriptions tab, delete the pending one, and create a fresh subscription.

***

#### Step 4: Create a Budget and Link It to the SNS Topic

1. Navigate to **AWS Billing → Budgets → Create budget**.<br>

   <figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FK4gpTDZsanghLFu29GPT%2Fimage%20(3)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=b1bedb63-50dd-429e-b880-64724efc5a6f" alt=""><figcaption></figcaption></figure>
2. Select **Customize (advanced)** — the simplified template doesn't expose SNS alert options.<br>

   <figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F4XNdi6pgKrG32e1crmPA%2Fimage%20(4)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=950343d8-063f-4942-81f0-b0f7e62f3f67" alt=""><figcaption></figcaption></figure>
3. Set your **Budget name**, **Period** (Monthly), and **Budget amount**.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FDYKtyElGC8y18eynAQqP%2Fimage%20(5)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=6bed57ab-1b81-4ead-8cda-8766261f04de" alt=""><figcaption></figcaption></figure>

1. In the **Alerts** section:
   * Threshold: your desired percentage (e.g., `80%`)
   * Trigger: `Actual` or `Forecasted`
   * SNS alert: paste the **Topic ARN** from Step 2

     <figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FJxe8zWh5qZo3ubgafY6k%2Fimage%20(6)%20(1)%20(1)%20(1).png?alt=media&amp;token=890975ac-5512-4372-b37c-903f15a18135" alt=""><figcaption></figcaption></figure>

     <figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FnL5cGyFnm3y4HWrKuFQn%2FEkran%20Resmi%202026-03-04%2014.53.43.png?alt=media&amp;token=62dd6dbb-4b23-4df6-bdb4-e2e848dc2edf" alt=""><figcaption></figcaption></figure>
2. Click **Next → Next → Create budget**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FmjVcqcx50hv0cKIno9ez%2Fimage%20(7)%20(1)%20(1).png?alt=media&amp;token=ee54d523-2cd0-46ce-8fd0-db5f43da315e" alt=""><figcaption></figcaption></figure>

***

#### Step 5: Test the Integration

Real budget alerts only fire when a threshold is actually crossed, which can take days. Instead, use SNS Publish to send a test payload right now.

1. Go to **SNS → Topics → `oncall-budget-alerts`** and click **Publish message**.
2. **Subject:** `AWS Budgets Notification`
3. **Message body:**

```json
{
  "AlarmName": "test-oncall-budget",
  "AccountId": "123456789012",
  "BudgetName": "test-oncall-budget",
  "BudgetType": "COST",
  "BudgetLimit": {"Amount": "1.0", "Unit": "USD"},
  "ActualSpend": {"Amount": "0.85", "Unit": "USD"},
  "ForecastedSpend": {"Amount": "1.20", "Unit": "USD"},
  "NotificationThreshold": "80.0",
  "NotificationType": "ACTUAL",
  "AlertType": "OVER_BUDGET",
  "TimePeriod": {"Start": "2026-03-01", "End": "2026-03-31"},
  "Timestamp": "2026-03-04T10:00:00Z"
}
```

4. Click **Publish message** and check your webhook endpoint.

— *SNS Publish message form with Subject and Message body filled in*

— *Test payload received (Type: Notification, Message field visible)*

***

### Verification Checklist

* A budget notification payload was received by the platform (status: PROBLEM).
* The `Subject` field reads `AWS Budgets Notification`.
* The `Message` field contains a valid JSON string with `BudgetName`, `AccountId`, `NotificationType`, and `AlertType`.
* Priority mapped correctly: `ACTUAL` → HIGH, `FORECASTED` → MEDIUM.
* The platform created an alert with the budget name visible in the alert title.

***

### Troubleshooting

| Issue                                                                    | Possible Cause                                   | Resolution                                                                                                   |
| ------------------------------------------------------------------------ | ------------------------------------------------ | ------------------------------------------------------------------------------------------------------------ |
| Subscription stuck on `PendingConfirmation`                              | Confirmation URL expired or endpoint unreachable | Delete the subscription and create a new one. Open the `SubscribeURL` immediately after it arrives.          |
| No alerts received after budget creation                                 | Threshold not yet crossed                        | Use SNS Publish with a test message body to validate without waiting for a real breach.                      |
| `Invalid payload` error                                                  | Raw message delivery is enabled                  | Disable **Enable raw message delivery** on the SNS subscription. The full SNS envelope is required.          |
| Priority always maps to MEDIUM                                           | `NotificationType` not parsed correctly          | Verify the `Message` field is a valid JSON string and `NotificationType` is either `ACTUAL` or `FORECASTED`. |
| Alerts not closing automatically                                         | AWS Budgets does not send recovery events        | This is an AWS limitation. Close budget alerts manually in the platform after investigation.                 |
| Duplicate alerts for the same budget                                     | Multiple SNS subscriptions for the same endpoint | Remove duplicate subscriptions from the SNS topic.                                                           |
| `SubscriptionConfirmation` payload received but status stays unconfirmed | `SubscribeURL` not opened in time                | Copy the `SubscribeURL` from the confirmation payload and open it in a new browser tab.                      |


# AWS Cloudwatch Integration

## Amazon CloudWatch Integration

Amazon CloudWatch is a monitoring and observability service built for AWS cloud resources, providing real-time metrics, alarms, and automated actions across your entire AWS infrastructure.

### Overview

This guide walks you through integrating Amazon CloudWatch with our alert management platform. CloudWatch alarm notifications are delivered through Amazon Simple Notification Service (SNS) as HTTP POST webhooks. The `Message` field inside the SNS envelope contains a JSON-encoded string with the full alarm details including alarm name, state change, trigger condition, and affected resource.

### Integration Flow

1. CloudWatch continuously monitors AWS resource metrics (CPU, memory, disk, network, custom metrics, etc.).
2. When a metric violates a configured alarm threshold, CloudWatch changes the alarm state to **ALARM** and publishes a notification to the linked SNS topic.
3. The SNS topic delivers the notification payload to the subscribed HTTPS endpoint (our platform webhook).
4. When the metric returns to normal, CloudWatch changes the alarm state to **OK** and publishes a recovery notification through the same SNS topic.

***

### Webhook Payload Schema

CloudWatch alarm notifications are wrapped in an **SNS notification envelope**. The payload structure is standardized by AWS and cannot be customized.

#### SNS Envelope Fields

| Field            | Type   | Required | Description                                                                 |
| ---------------- | ------ | -------- | --------------------------------------------------------------------------- |
| Type             | string | Yes      | SNS message type (`Notification`, `SubscriptionConfirmation`)               |
| MessageId        | string | Yes      | Unique identifier for the SNS message                                       |
| TopicArn         | string | Yes      | ARN of the SNS topic that published the message                             |
| Subject          | string | No       | Alert summary, e.g. `ALARM: "high-cpu-test-alarm" in US East (N. Virginia)` |
| Message          | string | Yes      | JSON-encoded string containing the full CloudWatch alarm details            |
| Timestamp        | string | Yes      | ISO 8601 timestamp of the notification                                      |
| SignatureVersion | string | No       | Version of the SNS message signature                                        |
| Signature        | string | No       | Base64-encoded signature for message verification                           |
| SigningCertURL   | string | No       | URL of the certificate used to sign the message                             |
| UnsubscribeURL   | string | No       | URL to unsubscribe from the SNS topic                                       |

#### Inner Message Fields (JSON-encoded inside `Message`)

| Field            | Type   | Description                                                        |
| ---------------- | ------ | ------------------------------------------------------------------ |
| AlarmName        | string | Name of the CloudWatch alarm                                       |
| AlarmDescription | string | Description of the alarm                                           |
| AWSAccountId     | string | AWS account ID                                                     |
| NewStateValue    | string | Current alarm state: `ALARM`, `OK`, or `INSUFFICIENT_DATA`         |
| NewStateReason   | string | Human-readable explanation of the state change                     |
| StateChangeTime  | string | Timestamp of the state change                                      |
| Region           | string | AWS region where the alarm is configured                           |
| AlarmArn         | string | Full ARN of the CloudWatch alarm                                   |
| OldStateValue    | string | Previous alarm state                                               |
| Trigger          | object | Object containing MetricName, Namespace, Threshold, Dimensions etc |

***

### Severity / Status Mapping

CloudWatch does not have a native severity field. The alarm state is used to determine the alert status:

| CloudWatch State   | Platform Status | Description                                    |
| ------------------ | --------------- | ---------------------------------------------- |
| ALARM              | PROBLEM         | Threshold breached, resource is in alarm state |
| OK                 | RECOVERY        | Metric returned to normal, alarm cleared       |
| INSUFFICIENT\_DATA | PROBLEM         | Not enough data to evaluate the alarm          |

**Priority Mapping** Priority is inferred from the alarm name. To enable automatic priority mapping, include one of the following keywords in your alarm name:

* `CRITICAL` → Critical
* `HIGH` → High
* `WARN` or `WARNING` → Medium
* `LOW` or `INFO` → Low

Alarms without these keywords default to **Medium** priority. Example: `prod-database-CRITICAL-cpu-alarm`

***

### Alert Payload Examples

#### Raised (ALARM)

This payload is sent when a CloudWatch alarm is triggered. The `Subject` field begins with `ALARM:` and the inner `NewStateValue` is `ALARM`.

ALARM payload :

```json
{
  "Type": "Notification",
  "MessageId": "xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx",
  "TopicArn": "arn:aws:sns:region:ACCOUNT_ID:TOPIC_NAME",
  "Subject": "ALARM: \"example-alarm-name\" in REGION",
  "Message": "{\"AlarmName\":\"example-alarm-name\",\"AlarmDescription\":\"Test alarm description\",\"AWSAccountId\":\"ACCOUNT_ID\",\"NewStateValue\":\"ALARM\",\"NewStateReason\":\"Threshold Crossed: example reason\",\"StateChangeTime\":\"2026-02-10T17:18:34.056+0000\",\"Region\":\"REGION\",\"AlarmArn\":\"arn:aws:cloudwatch:region:ACCOUNT_ID:alarm:example-alarm-name\",\"OldStateValue\":\"INSUFFICIENT_DATA\",\"Trigger\":{\"MetricName\":\"ExampleMetric\",\"Namespace\":\"AWS/Service\",\"StatisticType\":\"Statistic\",\"Statistic\":\"AVERAGE\",\"Unit\":null,\"Dimensions\":[{\"value\":\"example-resource\",\"name\":\"ResourceName\"}],\"Period\":86400,\"EvaluationPeriods\":1,\"DatapointsToAlarm\":1,\"ComparisonOperator\":\"GreaterThanThreshold\",\"Threshold\":0.0}}",
  "Timestamp": "2026-02-10T17:18:34.096Z",
  "SignatureVersion": "1",
  "Signature": "REDACTED",
  "SigningCertURL": "https://sns.region.amazonaws.com/SimpleNotificationService.pem",
  "UnsubscribeURL": "https://sns.region.amazonaws.com/?Action=Unsubscribe"
}
```

#### Cleared (OK)

This payload is sent when the alarm returns to normal. The `Subject` field begins with `OK:` and the inner `NewStateValue` is `OK`.

```json
{
  "Type": "Notification",
  "MessageId": "xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx",
  "TopicArn": "arn:aws:sns:region:ACCOUNT_ID:TOPIC_NAME",
  "Subject": "OK: \"example-alarm-name\" in REGION",
  "Message": "{\"AlarmName\":\"example-alarm-name\",\"AlarmDescription\":\"Test alarm description\",\"AWSAccountId\":\"ACCOUNT_ID\",\"NewStateValue\":\"OK\",\"NewStateReason\":\"Recovery reason\",\"StateChangeTime\":\"2026-02-10T17:28:07.334+0000\",\"Region\":\"REGION\",\"AlarmArn\":\"arn:aws:cloudwatch:region:ACCOUNT_ID:alarm:example-alarm-name\",\"OldStateValue\":\"ALARM\",\"Trigger\":{\"MetricName\":\"ExampleMetric\",\"Namespace\":\"AWS/Service\",\"StatisticType\":\"Statistic\",\"Statistic\":\"AVERAGE\",\"Unit\":null,\"Dimensions\":[{\"value\":\"example-resource\",\"name\":\"ResourceName\"},{\"value\":\"example-dimension\",\"name\":\"DimensionType\"}],\"Period\":86400,\"EvaluationPeriods\":1,\"DatapointsToAlarm\":1,\"ComparisonOperator\":\"GreaterThanThreshold\",\"Threshold\":0.0}}",
  "Timestamp": "2026-02-10T17:28:07.380Z",
  "SignatureVersion": "1",
  "Signature": "REDACTED",
  "SigningCertURL": "https://sns.region.amazonaws.com/SimpleNotificationService.pem",
  "UnsubscribeURL": "https://sns.region.amazonaws.com/?Action=Unsubscribe"
}
```

***

### Installation & Configuration

#### Step 1: Create an Alert Source in the Platform

1. Log in to the alert management platform.
2. Navigate to **Integrations** → **Add Integration**.
3. Select **Amazon CloudWatch** as the provider.
4. Name the integration (e.g., `Production AWS Alerts`).
5. Paste [https://api.itoc360.app/functions/v1/events?token=\<x-itoc360-token>](https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>)

#### Step 2: Create an SNS Topic in AWS

1. Log in to the **AWS Management Console**.
2. Navigate to **Simple Notification Service (SNS)** → **Topics**.
3. Click **Create topic**.
4. Select type: **Standard** (not FIFO).
5. Enter a topic name (e.g., `oncall-cloudwatch-alerts`).
6. Leave all other settings as default.
7. Click **Create topic**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FqrhHGjtLbZxXOOsSEMl0%2FEkran%20Resmi%202026-02-25%2015.14.48.png?alt=media&amp;token=6da046a5-5e34-42ba-808b-905a62962f35" alt=""><figcaption></figcaption></figure>

* SNS Create Topic page (Standard type selected, topic name entered)

8. Note the **Topic ARN** displayed on the topic detail page.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FL5JQRDSp8JoVP9P1a8i7%2FEkran%20Resmi%202026-02-25%2015.15.59.png?alt=media&amp;token=fc98f275-b59a-4092-9276-e7a790d89903" alt=""><figcaption></figcaption></figure>

* SNS Topic created with ARN visible

#### Step 3: Create an SNS Subscription (Webhook Endpoint)

1. On the topic detail page, go to the **Subscriptions** tab.
2. Click **Create subscription**.
3. **Topic ARN**: Pre-filled with the topic ARN (do not change).
4. **Protocol**: Select **HTTPS**.
5. **Endpoint**: Paste your platform webhook URL (e.g., `https://<your-platform>/functions/v1/webhook`).
6. **Enable raw message delivery**: Leave **unchecked** (disabled). This ensures the full SNS envelope is delivered.
7.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F87zMruSaqWKl4ZNRvsLx%2FEkran%20Resmi%202026-02-25%2015.17.48.png?alt=media&amp;token=c44d1ad7-d943-42b7-b709-15fd06c3992c" alt=""><figcaption></figcaption></figure>

* Click **Create subscription**.

1. The subscription status will initially show **PendingConfirmation**.
2. The platform will automatically confirm the subscription. If using a third-party test endpoint (e.g., webhook.site), manually open the `SubscribeURL` from the received payload in your browser.
3. After refreshing, the subscription status should change to **Confirmed**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FBjb3OjPuFZhp7zgdry7B%2Fimage%20(5)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=f3ce20a3-4462-446f-ac43-74d3fe69ae1b" alt=""><figcaption></figcaption></figure>

* SNS Subscription status: Confirmed

#### Step 4: Create a CloudWatch Alarm and Link to the SNS Topic

1. Navigate to **CloudWatch** → **Alarms** → **All alarms**.
2. Click **Create alarm**.
3. Click **Select metric** and choose the metric you want to monitor (e.g., EC2 CPUUtilization, RDS connections, S3 object count, or a custom metric).

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FfZ6igc5ovFfrm9Jg94wT%2FEkran%20Resmi%202026-02-12%2018.30.15.png?alt=media&amp;token=14ab1945-239e-4b2c-96e5-d0cae15eb53d" alt=""><figcaption></figcaption></figure>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FcNuCFjl0EjA6KN8Ue9Gf%2FEkran%20Resmi%202026-02-12%2018.30.57.png?alt=media&amp;token=35edc4cd-5900-4be2-8322-81764084a511" alt=""><figcaption></figcaption></figure>

1. Configure the alarm condition:
   * **Period**: Select an appropriate evaluation period (e.g., 1 minute, 5 minutes).
   * **Threshold type**: Static.
   * **Condition**: Greater than (or your preferred operator).
   * **Threshold value**: Set the desired threshold.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F6aPTJWLzcwiHot2eEXxD%2FEkran%20Resmi%202026-02-25%2015.21.20.png?alt=media&amp;token=fb92315c-41ed-4431-8c8e-0df02b7f0dd6" alt=""><figcaption></figcaption></figure>

5. Click **Next** to configure actions.
6. Under **Notification**, configure **two** notification actions:

   **Action 1 — In alarm (Trigger):**

   * Alarm state trigger: **In alarm**
   * Select an existing SNS topic: Choose the topic created in Step 2 (e.g., `oncall-cloudwatch-alerts`)

   **Action 2 — OK (Recovery):**

   * Click **Add notification**
   * Alarm state trigger: **OK**
   * Select an existing SNS topic: Choose the same topic

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FfKf7XhKW8ifSEwHMxyHX%2Fimage%20(6)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=cb7d473f-7f02-446d-b14a-924722121934" alt=""><figcaption></figcaption></figure>

* Configure actions page showing both In Alarm and OK notification actions

7. Click **Next**, name your alarm, add a description, and click **Create alarm**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fvtgdul46g9Ibhzs55QAK%2FEkran%20Resmi%202026-02-25%2015.23.25.png?alt=media&amp;token=cae619de-874e-470e-8cb2-43c9bbdc472d" alt=""><figcaption></figcaption></figure>

&#x20;

* Alarm successfully created (state: Insufficient data, Actions enabled)

> **Important:** Both **In alarm** and **OK** notification actions must be configured to ensure proper alert lifecycle handling and automatic recovery.

***

### Testing

Once the alarm is triggered, you can verify the integration by checking the received payloads.

#### Verify ALARM Notification

When the alarm condition is met, CloudWatch will automatically send an ALARM notification through SNS to your webhook endpoint.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FAgFOyq67Gfc6mccxK97m%2Fimage%20(9)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=d7e8715d-09bf-4e34-91bb-078244976897" alt=""><figcaption></figcaption></figure>

* CloudWatch dashboard showing alarm in "In alarm" state

#### Trigger a Manual OK (Recovery) via CloudShell

To test the recovery flow, use **AWS CloudShell** (available in the AWS Console top toolbar) to manually set the alarm state to OK:

```bash
aws cloudwatch set-alarm-state \
  --alarm-name "high-cpu-test-alarm" \
  --state-value OK \
  --state-reason "Recovery test - CPU back to normal" \
  --region us-east-1
```

&#x20;

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F2zAGY2Cs6Av1CurEeicA%2FEkran%20Resmi%202026-02-25%2015.26.23.png?alt=media&amp;token=dce37686-3397-4b7f-ad64-ab7f38268830" alt=""><figcaption></figcaption></figure>

* CloudShell with set-alarm-state OK command executed, alarm state changed to OK

#### Verification Checklist

Verify that:

1. An **ALARM** notification is received by the platform (status: PROBLEM).
2. An **OK** notification is received after recovery (status: RECOVERY).
3. Both payloads contain the correct `Type: "Notification"`, `TopicArn`, `Subject`, and `Message` fields.

***

### Troubleshooting

| Issue                         | Possible Cause                                        | Resolution                                                                                       |
| ----------------------------- | ----------------------------------------------------- | ------------------------------------------------------------------------------------------------ |
| No alerts received            | SNS subscription not confirmed                        | Check subscription status in SNS Console. Re-create subscription if stuck on PendingConfirmation |
| No alerts received            | Alarm notification action not configured              | Ensure the SNS topic is attached to the alarm's In Alarm action                                  |
| Recovery alerts missing       | OK notification action not configured                 | Add the SNS topic to the alarm's OK action via **Add notification**                              |
| SubscriptionConfirmation only | Endpoint did not confirm the subscription             | Open the `SubscribeURL` in a browser or ensure your platform auto-confirms                       |
| Payload format unexpected     | Raw message delivery is enabled                       | Disable "Enable raw message delivery" in the SNS subscription settings                           |
| Delayed notifications         | Alarm evaluation period too long                      | Reduce the alarm's Period setting for faster evaluation                                          |
| Invalid payload error         | Payload does not match the expected CloudWatch schema | Verify the subscription is HTTPS and raw delivery is disabled                                    |
| Duplicate notifications       | Multiple SNS subscriptions for the same endpoint      | Remove duplicate subscriptions from the SNS topic                                                |


# Google Cloud Monitor Integration

Google Cloud Monitoring (formerly Stackdriver) lets you set up alerting policies on metrics and logs across your GCP infrastructure. When a condition is met, it fires a webhook notification to any endpoint you configure — including ITOC360.

This integration receives those webhook notifications and turns them into incidents in your on-call workflow. When the alert resolves in Google Cloud, the incident is automatically resolved in itoc360 as well.

### How It Works

Google Cloud Monitoring sends a webhook payload to ITOC360 every time an alerting policy condition is triggered or resolved. The payload always contains an `incident_id` that stays the same for both the open and close events — ITOC360 uses this to match them together automatically.

* When `state` is `OPEN` → a new alert is created in ITOC360
* When `state` is `CLOSED` → the existing alert is resolved

### Prerequisites

* A Google Cloud project with Cloud Monitoring enabled
* An alerting policy (or you will create one during setup)
* An ITOC360 source configured for Google Cloud Monitoring

***

### Step 1 — Copy Your Webhook URL

In ITOC360, navigate to your source settings and copy the webhook URL generated for your Google Cloud Monitoring source. You will paste this into Google Cloud in the next step.

***

### Step 2 — Add a Webhook Notification Channel

Open the [Google Cloud Console](https://console.cloud.google.com/) and navigate to **Monitoring** from the left sidebar.On the Monitoring page, go to **Alerting**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FpBJGmokmM3FATzq3Ix7A%2Fimage%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=eea349ae-9f37-40e6-b837-e115063be52d" alt=""><figcaption></figcaption></figure>

Click the **"Edit Notification Channels"** button in the top right corner of the Alerting page.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fr0J1gUzsZAH4DSw7nSZG%2Fimage%20(2)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=a462e51c-ed74-4bbe-8653-6d176eae4a78" alt=""><figcaption></figcaption></figure>

On the Notification Channels page, scroll down to the **Webhooks** section and click **"Add New"**.

Fill in the form:

* **Display Name** — enter a recognizable name, for example `itoc360`
* **Endpoint URL** — paste the webhook URL you copied from ITOC360, then append your source token as a query parameter at the end

Google Cloud Monitoring does not support custom request headers, so the source token must be passed in the URL itself. The final URL should look like this:

```
https://api.itoc360.app/functions/v1/events?token=<x-itoc360-token>
```

You can find your source token on the source settings page in ITOC360.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FNDJqfgvSYDYigMRNWwgS%2Fimage%20(4)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=4ef1bc66-7fd0-4fcd-b7a8-944ca50a0d91" alt=""><figcaption></figcaption></figure>

Click **"Test Connection"** to verify that ITOC360 can receive the payload. You should see a success toast at the bottom of the page.

Click **Save**. The new webhook channel will now appear in the Webhooks list.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FV5xMVbogWwVNcBU6Zj7g%2FEkran%20Resmi%202026-03-07%2017.22.22.png?alt=media&amp;token=ee80bd61-4d71-4200-8a85-3de174240ac7" alt=""><figcaption></figcaption></figure>

***

### Step 3 — Attach the Webhook to an Alerting Policy

Go back to **Monitoring > Alerting** and open an existing alerting policy, or create a new one by clicking **"Create Policy"**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FmImML1TI7NpSwzDgDXb0%2Fimage%20(5)%20(1)%20(1)%20(1).png?alt=media&amp;token=84b84d25-fc07-4209-83d3-1a10b39e4e58" alt=""><figcaption></figcaption></figure>

In the left sidebar, click **"Notifications and name"** to jump to the notifications step.

Click **"Add Notification Channels"**.

A panel will open listing all available notification channels. Find the webhook you created under the **Webhooks** section and select it.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F1VBFzP3zoxJoqC1GxnBR%2Fimage%20(7)%20(1).png?alt=media&amp;token=7ed1ee1f-4016-4936-9e54-9748d0afd2a6" alt=""><figcaption></figcaption></figure>

After selecting it, the channel will appear under the Notifications section of the policy.

Give the policy a name in the **"Alert policy name"** field at the bottom, then click **"Create Policy"** or **"Save"** if you are editing an existing one.

The policy will now appear in the Alerting list.

***

### Payload Reference

Below is the payload structure that Google Cloud Monitoring sends to webhook. This is provided for reference — no manual configuration is needed.

```json
{
  "version": "1.2",
  "incident": {
    "incident_id": "0.opqiw61fsv7p",
    "scoping_project_id": "your-project",
    "scoping_project_number": 12345,
    "url": "https://console.cloud.google.com/monitoring/alerting/incidents/...",
    "state": "OPEN",
    "severity": "ERROR",
    "started_at": 1577840461,
    "ended_at": null,
    "policy_name": "projects/your-project/alertPolicies/12345",
    "condition_name": "CPU utilization > 90%",
    "resource_name": "your-project gke-cluster-1-default-pool",
    "resource_display_name": "gke-cluster-1-default-pool",
    "resource_type_display_name": "VM Instance",
    "resource": {
      "type": "gce_instance",
      "labels": {
        "instance_id": "11223344",
        "project_id": "your-project",
        "zone": "us-central1-c"
      }
    },
    "metric": {
      "type": "compute.googleapis.com/instance/cpu/utilization",
      "displayName": "CPU utilization",
      "labels": {
        "instance_name": "my-vm-instance"
      }
    },
    "documentation": {
      "content": "CPU is above the threshold. Check the runbook.",
      "mime_type": "text/markdown"
    },
    "summary": "CPU for gke-cluster-1 is above the threshold of 90%"
  }
}
```

When the alert resolves, the same payload is sent with `state` set to `"CLOSED"` and `ended_at` filled in. itoc360 matches it to the original alert using `incident_id` and closes the incident automatically.

***

### Priority Mapping

itoc360 maps the `severity` field from the incoming payload to its own priority levels. The default mapping is shown below. You can override it per source from the source settings page.

| Google Cloud Severity | itoc360 Priority |
| --------------------- | ---------------- |
| CRITICAL              | Critical         |
| ERROR                 | High             |
| WARNING               | Medium           |
| INFO                  | Low              |
| no severity           | Medium           |

> **Note:** When an alerting policy does not have a severity level configured, Google Cloud sends `"no severity"` as the value. ITOC360 treats this as Medium priority by default.

### Troubleshooting

**Test notification was sent but no event appeared in itoc360** Check that the endpoint URL is correct and that the `token` query parameter is present and matches your itoc360 source token. Google Cloud Monitoring does not support custom headers, so authentication must be done via the query parameter. Also make sure your itoc360 source is active.

**Incidents are not resolving automatically** This usually means the alerting policy is not configured to send a notification on resolution. In Google Cloud, make sure the **"Notify on incident closure"** option is enabled for the notification channel, or that your alerting policy has a closing condition defined.

**`severity` field is missing from the payload** Some alerting policies do not set a severity level. In that case, ITOC360 falls back to Medium priority. You can set a default priority override from the source settings if needed.


# Log Management

This category covers log aggregation and time-series data platforms. These tools store and analyze large volumes of log and metric data, and send alerts to ITOC360 when log-based conditions or metric thresholds are met.

***

### Integrations in this category

| Integration       | What it monitors                               | Alert delivery        |
| ----------------- | ---------------------------------------------- | --------------------- |
| **Grafana Loki**  | Log aggregation and query-based alerts         | Webhook (via Grafana) |
| **Grafana Mimir** | Long-term Prometheus metrics storage           | Webhook (via Grafana) |
| **Graylog**       | Centralized log management, event streams      | Webhook               |
| **InfluxDB**      | Time-series metrics and threshold-based alerts | Webhook               |

***

### How it works

Log management platforms collect and index log streams from your infrastructure and applications. When a log-based alert rule is triggered — an error pattern appears, a metric threshold is breached, or an anomaly is detected — the platform sends an alert payload to your ITOC360 Source webhook URL. ITOC360 parses the incoming alert, applies escalation logic, and notifies the on-call engineer.

{% hint style="info" %}
Grafana Loki and Grafana Mimir route alerts through Grafana's alerting engine. Configure the ITOC360 webhook as a Grafana contact point to forward alerts from both sources.
{% endhint %}

***

### Get started


# Graylog Integration

Connect Graylog to ITOC360 so that every alert your event definitions produce lands directly in your on-call workflow — no manual forwarding, no missed pages.

### Overview

[Graylog](https://graylog.org/) is an open-source log management and SIEM platform that lets you define conditions on your log data and fire notifications when those conditions are met. The HTTP Notification type sends a structured JSON payload to any endpoint you point it at, which is exactly how ITOC360 receives it.

When a Graylog event definition matches, ITOC360 opens an alert. Repeated firings of the same definition group into that existing alert rather than creating duplicates, so a flapping condition produces one alert to act on instead of a stream of pages. Graylog does not send a follow-up notification when a condition stops matching, so alerts raised from Graylog are closed in ITOC360 by the responder once the issue is handled.

The screenshot below shows the Alerts & Events dashboard where your event history and alert metrics are visible at a glance.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FMCI3T6yLEGpZk9RnMMpD%2Fimage%20(92).png?alt=media&amp;token=59f36d5d-98a9-40a2-b240-c9bbb20f5040" alt=""><figcaption></figcaption></figure>

***

### Step 1 — Open the Notifications Page

In the top navigation bar, click **Alerts**, then select the **Notifications** tab. This is where you manage every outbound integration Graylog can call.

Click **Create Notification** in the top-right corner to start.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FmDw07crN4mDKVJYXEeTL%2Fimage%20(93).png?alt=media&amp;token=897f0abb-cacb-4f18-b474-c9cf70c8f5fe" alt=""><figcaption></figcaption></figure>

### **Step 2 — Whitelist the ITOC360 URL**

Graylog validates every outbound notification URL against an allowlist and silently refuses to POST to addresses that are not on it. Configure this before creating the notification, otherwise the notification will appear to save correctly but never deliver.

Go to **System → Configurations**, find **URL Whitelist**, and click **Edit configuration**. Add an entry:

* **Title** — `itoc360`
* **Type** — Regex
* **Value** — `^https://api\.itoc360\.app/.*`

### Step 3— Configure the HTTP Notification

Fill in the form that appears:

* **Title** — give it a name you'll recognise later, for example `ITOC360`
* **Notification Type** — select **HTTP Notification** from the dropdown
* **URL** — paste [https://api.itoc360.app/functions/v1/events?token=\<x-itoc360-token>](https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>) URL here, including the token query parameter

The form also has optional fields for Basic Authentication, API Key, and API Secret. You do not need any of these — ITOC360 authenticates through the token in the URL.

Once the URL is in place, click **Execute Test Notification** to fire a test payload immediately. If everything is wired up correctly, a new alert will appear in your ITOC360 source within a few seconds.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FgolBDA2szr2rHFIF7Ngl%2FEkran%20Resmi%202026-03-16%2016.36.41.png?alt=media&amp;token=10a71e0f-3742-4ffb-bd64-b140c389eadb" alt=""><figcaption></figcaption></figure>

\
Scroll down and click **Save** to store the notification.

### Step 4 — Attach the Notification to an Event Definition

A notification on its own does nothing until it is linked to an event definition. Open **Event Definitions**, find the definition you want to forward to ITOC360, and click **Edit**. Navigate to the **Notifications** step, click **Add Notification**, and select the `ITOC360` notification you just created. Save the definition.

On the same Notifications step, set **Message Backlog** to a non-zero value such as `5`. With a backlog of `0` the alert still arrives, but it carries only the event definition title and no log content — rarely enough for a responder to act on.

From this point on, every time that event definition triggers, Graylog will POST the payload to ITOC360.

### How Alerts Map to Incidents

**How Alerts Are Grouped**

ITOC360 identifies a Graylog alert by its event definition, so every firing of the same definition lands on the same alert instead of opening a new one. If the definition uses an aggregation with a group-by field, each group is tracked as a separate alert.

The log lines that triggered the condition are read from the `backlog` array and attached to the alert. Two fields in the payload are easy to misread: `event.message` repeats the event definition title rather than carrying the log line, and `event.source` identifies the Graylog node rather than the monitored host. Both the log line and its originating host come from `backlog`.

### Priority Mapping

ITOC360 uses the `event.priority` integer that Graylog includes in every payload:

| Graylog `event.priority` | ITOC360 Priority |
| ------------------------ | ---------------- |
| `1`                      | Low              |
| `2`                      | Medium           |
| `3`                      | High             |

You can override these defaults per source under **Sources → Edit → Priority Mapping**.

### Troubleshooting

**Execute Test Notification returns an error or no alert appears**

Check that the URL in the notification form is exactly the one shown on your ITOC360 source page, token included. A single mistyped character will cause a 401 or 404. If the test reports success but no alert appears, check the URL whitelist in **System → Configurations** — an address that is not whitelisted is rejected without an error in the notification form.

**Alerts do not close by themselves**

This is expected. Graylog sends a notification when a condition is met and does not send one when it clears, so there is no resolution signal for ITOC360 to act on. Close the alert in ITOC360 once the underlying issue is handled. If you need automatic closure, route Graylog through n8n and send an explicit resolve event from a second event definition that matches the healthy state.

**Unknown or placeholder values in the payload**

Fields like `job_definition_id: "<unknown>"` and `event.id: "TEST_NOTIFICATION_ID"` appear only when you use the Execute Test Notification button. In production, when a real event triggers the definition, all fields will contain the actual Graylog-generated values.


# InfluxDB Integration

[InfluxDB](https://www.influxdata.com/) is a high-performance time series database purpose-built for storing metrics, events, and real-time analytics. Its built-in Checks & Notifications system lets you define threshold conditions on your time series data and push alert notifications directly to external HTTP endpoints — making it straightforward to route those alerts into ITOC360.

### In ITOC360

Go to Sources, click **Create Source**, and select **InfluxDB** from the list. Once the source is created, copy the webhook URL and token from the source detail page — you will need these when configuring InfluxDB.

### In InfluxDB

In the left sidebar, hover over the bell icon to expand the navigation and click **Alerts**.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fb2hWR39c6vdHz4CDRuWr%2Fimage%20(115).png?alt=media&amp;token=701db040-6c9a-4483-8ba4-accfbb36840c" alt=""><figcaption></figcaption></figure>

#### Step 1 — Create a Notification Endpoint

On the Alerts page, click **Notification Endpoints**, then click **+ Create** in the top right corner.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F6cQTdWOSxMnDvuF8MUFC%2Fimage%20(116).png?alt=media&amp;token=6c152022-f019-4141-b1d4-d1e1b6fb2e87" alt=""><figcaption></figcaption></figure>

From the **Destination** dropdown, select **HTTP** and give the endpoint a name. Under **HTTP Options**, make sure the method is set to **POST** and the auth method is **none**. Paste your ITOC360 webhook URL into the URL field, appending your source token as a query parameter:

```
https://api.itoc360.app/functions/v1/events?token=<x-itoc360-token>
```

Click **Create Notification Endpoint** to save.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fg1s9OZ5AlWxdh2yzcy5q%2FEkran%20Resmi%202026-03-31%2014.23.52.png?alt=media&amp;token=a9baf71d-1345-4599-a87a-78cbf8ba4655" alt=""><figcaption></figcaption></figure>

#### Step 2 — Create a Check

Click the **Checks** tab on the Alerts page, then click **+ Create** and select **Threshold Check**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F6SgrNcZtvAgYh3u2hLmo%2Fimage%20(117).png?alt=media&amp;token=39488172-a7d4-4b57-8f00-20f7e3c9eac1" alt=""><figcaption></figcaption></figure>

In the query builder, select your bucket from the **FROM** column, choose a measurement, and select the field you want to monitor. Click **Submit** to preview the data on the chart.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FYFvuiMIkuImvlYynP0tm%2Fimage%20(118).png?alt=media&amp;token=47684841-aa8a-4400-82b7-5a88a20e959f" alt=""><figcaption></figcaption></figure>

Switch to the **2. Configure Check** tab. In the **Thresholds** section on the right, click **+ CRIT** and enter the value above which the check should fire as critical. You can optionally add a **WARN** threshold for a lower severity level. Give the check a descriptive name at the top, then click the checkmark button in the top right corner to save.\ <br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FNykvm1qxgUFjHZp9qR5r%2Fimage%20(119).png?alt=media&amp;token=963bc533-74fb-41bc-9952-74929764c827" alt=""><figcaption></figcaption></figure>

#### Step 3 — Create Notification Rules

Click the **Notification Rules** tab. InfluxDB requires a separate rule for each status level, so you will need to create two rules — one for when the check fires and one for when it recovers.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fdccewmj3IF1svdoW7gUE%2Fimage%20(120).png?alt=media&amp;token=e9999515-83e2-4496-9abc-9f5e6784acf4" alt=""><figcaption></figcaption></figure>

Click **+ Create**. Give the rule a name and set the condition to `When status is equal to CRIT`. Under **Notification Endpoint**, select the endpoint you created in Step 1. Click **Create Notification Rule** to save.\ <br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F4lqC605tcMrsn84KqpvH%2Fimage%20(121).png?alt=media&amp;token=fd183ee3-2458-4eb9-8ba8-fc93c3cb825b" alt=""><figcaption></figcaption></figure>

Then create a second rule in the same way, this time setting the condition to `When status is equal to OK` and selecting the same endpoint. This second rule is what allows ITOC360 to automatically resolve alerts when your metric returns to normal.

### Notes

* InfluxDB runs notification rules on a schedule (default: every 1 minute). There may be a short delay between a threshold breach and the alert appearing in ITOC360.
* The CRIT rule and the OK rule must point to the same notification endpoint so that ITOC360 can correctly match each alert to its resolution.
* If you have multiple checks, each one should have its own pair of notification rules.


# Mimir Integration

### Overview

[Grafana Mimir ](https://grafana.com/oss/mimir/)is an open-source, horizontally scalable, highly available, multi-tenant time series database (TSDB) for long-term Prometheus metrics storage. When alert rules defined in the Mimir Ruler are evaluated and a threshold is breached, Mimir routes those alerts through an external Alertmanager, which then delivers a structured webhook payload to the platform.

This integration supports automatic alert creation on firing events and automatic resolution when Alertmanager sends a resolved notification.

### Integration Flow

1. Mimir Ruler evaluates alert rules against stored metrics at a configured interval.
2. When a rule condition is met, the Ruler sends the alert to an external Alertmanager.
3. Alertmanager groups the alerts and delivers a webhook POST request to the platform endpoint.
4. When the alert condition clears, Alertmanager sends a `resolved` notification and the platform automatically closes the alert.

### Webhook Payload Schema

The payload delivered to the platform follows the standard Prometheus Alertmanager webhook format (version 4).

```json
{
  "receiver": "string",
  "status": "firing | resolved",
  "alerts": [
    {
      "status": "firing | resolved",
      "labels": {
        "alertname": "string",
        "severity": "string",
        "env": "string"
      },
      "annotations": {
        "summary": "string",
        "description": "string"
      },
      "startsAt": "ISO8601 timestamp",
      "endsAt": "ISO8601 timestamp",
      "generatorURL": "string",
      "fingerprint": "string"
    }
  ],
  "groupLabels": {},
  "commonLabels": {
    "alertname": "string",
    "severity": "string"
  },
  "commonAnnotations": {
    "summary": "string",
    "description": "string"
  },
  "externalURL": "string",
  "version": "4",
  "groupKey": "string",
  "truncatedAlerts": 0
}
```

***

### Setup

#### Step 1 — Create an Alert Source on the Platform

1. Navigate to **Sources** → **Add Source**.
2. Search for **Mimir** and select it.
3. Give the source a name and click **Save**.
4. Copy the generated **ITOC360 URL** and **Token**.

#### Step 2 — Install and Configure Alertmanager

Mimir does not include a built-in Alertmanager. You must run an external Prometheus Alertmanager and point Mimir's Ruler at it.

Install Alertmanager using your preferred method (binary, Docker, Helm). Then configure it to forward alerts to the platform:

**`alertmanager.yml`**

```yaml
global:
  resolve_timeout: 5m

route:
  receiver: itoc360-webhook
  group_wait: 10s
  group_interval: 1m
  repeat_interval: 4h

receivers:
  - name: itoc360-webhook
    webhook_configs:
      - url: "https://api.itoc360.app/functions/v1/events?token=<x-itoc360-token>"
        send_resolved: true
        http_config:
          headers:
            x-itoc360-token: "<your-source-token>"
```

> `send_resolved: true` is required for automatic alert resolution on the platform.

#### Step 3 — Configure the Mimir Ruler

Point the Mimir Ruler to your external Alertmanager in `mimir.yaml`:

```yaml
ruler:
  alertmanager_url: http://<alertmanager-host>:9093
  rule_path: /etc/mimir/rules
```

#### Step 4 — Create Alert Rules

Create rule files in the configured `rule_path` directory. Each file defines one or more alert groups.

**Example: `rules/production.yaml`**

```yaml
groups:
  - name: mimir-critical
    interval: 1m
    rules:
      - alert: MimirIngesterUnhealthy
        expr: |
          min by (cluster, namespace) (
            cortex_ring_members{state="Unhealthy", name="ingester"}
          ) > 0
        for: 15m
        labels:
          severity: critical
        annotations:
          summary: "Mimir cluster has unhealthy ingesters"
          description: >
            Mimir cluster {{ $labels.cluster }} in namespace
            {{ $labels.namespace }} has unhealthy ingesters.
```

> The `severity` label in `labels` is used by the platform for priority mapping (see table below).

#### Step 5 — Verify the Integration

After starting Mimir and Alertmanager:

1. Check Alertmanager UI at `http://<alertmanager-host>:9093` — active alerts should appear there first.
2. Trigger a test rule (e.g., `expr: vector(1) > 0`) and wait for the `group_wait` period.
3. Confirm the alert appears on the platform under the source you created.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fi9kvJufWDahyfWwprxjU%2FEkran%20Resmi%202026-03-10%2001.56.42.png?alt=media&amp;token=b6e0bb09-3ed7-47e2-ba8d-104e561e334d" alt=""><figcaption></figcaption></figure>

### Sample Payload

The following is a real payload captured during integration testing.

**ALERT (firing):**

```json
{
  "receiver": "itoc360-webhook",
  "status": "firing",
  "alerts": [
    {
      "status": "firing",
      "labels": {
        "alertname": "MimirIngesterUnhealthy",
        "cluster": "prod-eu",
        "namespace": "monitoring",
        "severity": "critical"
      },
      "annotations": {
        "summary": "Mimir cluster has unhealthy ingesters",
        "description": "Mimir cluster prod-eu in namespace monitoring has unhealthy ingesters."
      },
      "startsAt": "2026-03-09T22:28:43.863Z",
      "endsAt": "0001-01-01T00:00:00Z",
      "generatorURL": "http://mimir:9009/graph?...",
      "fingerprint": "34e164e9af873ac1"
    }
  ],
  "groupLabels": {},
  "commonLabels": {
    "alertname": "MimirIngesterUnhealthy",
    "severity": "critical"
  },
  "commonAnnotations": {
    "summary": "Mimir cluster has unhealthy ingesters"
  },
  "externalURL": "http://alertmanager:9093",
  "version": "4",
  "groupKey": "{}:{}",
  "truncatedAlerts": 0
}
```

**RESOLVE (resolved):**

```json
{
  "receiver": "itoc360-webhook",
  "status": "resolved",
  "alerts": [
    {
      "status": "resolved",
      "labels": {
        "alertname": "MimirIngesterUnhealthy",
        "severity": "critical"
      },
      "annotations": {
        "summary": "Mimir cluster has unhealthy ingesters"
      },
      "startsAt": "2026-03-09T22:28:43.863Z",
      "endsAt": "2026-03-09T23:01:00.000Z",
      "fingerprint": "34e164e9af873ac1"
    }
  ],
  "status": "resolved",
  "version": "4"
}
```

***

### Field Mapping Reference

| Payload Field                       | Description                                                           |
| ----------------------------------- | --------------------------------------------------------------------- |
| `status`                            | Top-level event type: `firing` → ALERT, `resolved` → RESOLVE          |
| `alerts[0].fingerprint`             | Unique identifier per alert label set — used for fingerprint matching |
| `alerts[0].labels.alertname`        | Name of the alert rule that fired                                     |
| `alerts[0].labels.severity`         | Severity label from the rule definition — used for priority mapping   |
| `alerts[0].annotations.summary`     | Short human-readable alert title                                      |
| `alerts[0].annotations.description` | Detailed description of the alert condition                           |
| `alerts[0].startsAt`                | ISO 8601 timestamp when the alert started firing                      |
| `alerts[0].endsAt`                  | ISO 8601 timestamp when resolved (`0001-...` means still active)      |
| `commonLabels`                      | Labels shared across all alerts in this group                         |
| `commonAnnotations`                 | Annotations shared across all alerts in this group                    |
| `groupKey`                          | Alertmanager group key used for deduplication                         |

### Priority Mapping

The platform maps the `severity` label from the alert rule to an internal priority level.

| Mimir `severity` Label | Platform Priority |
| ---------------------- | ----------------- |
| `critical`             | CRITICAL          |
| `error`                | HIGH              |
| `warning`              | MEDIUM            |
| `info`                 | LOW               |
| *(not set)*            | MEDIUM (default)  |

> You control the `severity` label in your alert rule definitions. Use consistent values across your rule files for predictable priority routing.

### RESOLVE Detection

The platform automatically resolves an alert when Alertmanager sends a payload with `"status": "resolved"`. This requires `send_resolved: true` in your Alertmanager webhook configuration (set in Step 2).

The resolved event is matched to the original alert using the `fingerprint` field, which Alertmanager generates deterministically from the alert's label set. As long as the labels do not change between firing and resolution, the fingerprint will match and the alert will be closed.


# Loki Integration

### Overview

[Grafana Loki](https://grafana.com/oss/loki/) is a horizontally scalable, highly available, multi-tenant log aggregation system inspired by Prometheus. Unlike traditional log systems, Loki indexes only metadata (labels) rather than full log content, making it cost-efficient at scale. When alert rules defined in the Loki Ruler detect error conditions or anomalies in log streams, Loki routes those alerts through an external Alertmanager, which delivers a structured webhook payload to the platform.

This integration supports automatic alert creation on firing events and automatic resolution when Alertmanager sends a resolved notification.

### Integration Flow

1. Loki continuously ingests log streams from applications and infrastructure.
2. The Loki Ruler evaluates LogQL alert rules against incoming log data at a configured interval.
3. When a rule condition is met, the Ruler sends the alert to an external Alertmanager.
4. Alertmanager groups the alerts and delivers a webhook POST request to the platform endpoint.
5. When the log condition clears, Alertmanager sends a `resolved` notification and the platform automatically closes the alert.

### Webhook Payload Schema

The payload delivered to the platform follows the standard Prometheus Alertmanager webhook format (version 4).

```json
{
  "receiver": "string",
  "status": "firing | resolved",
  "alerts": [
    {
      "status": "firing | resolved",
      "labels": {
        "alertname": "string",
        "severity": "string",
        "env": "string"
      },
      "annotations": {
        "summary": "string",
        "description": "string"
      },
      "startsAt": "ISO8601 timestamp",
      "endsAt": "ISO8601 timestamp",
      "generatorURL": "string",
      "fingerprint": "string"
    }
  ],
  "groupLabels": {},
  "commonLabels": {
    "alertname": "string",
    "severity": "string"
  },
  "commonAnnotations": {
    "summary": "string",
    "description": "string"
  },
  "externalURL": "string",
  "version": "4",
  "groupKey": "string",
  "truncatedAlerts": 0
}
```

***

### Setup

#### Step 1 — Create an Alert Source on the Platform

1. Navigate to **Sources** → **Add Source**.
2. Search for **Loki** and select it.
3. Give the source a name and click **Save**.
4. Copy the generated ITOC360 **URL** and **Token**.

#### Step 2 — Install and Configure Alertmanager

Loki does not include a built-in Alertmanager. You must run an external Prometheus Alertmanager and point Loki's Ruler at it.

Install Alertmanager using your preferred method (binary, Docker, Helm). Then configure it to forward alerts to the platform:

**`alertmanager.yml`**

```yaml
global:
  resolve_timeout: 5m

route:
  receiver: itoc360-webhook
  group_wait: 10s
  group_interval: 1m
  repeat_interval: 4h

receivers:
  - name: itoc360-webhook
    webhook_configs:
      - url: "https://api.itoc360.app/functions/v1/events?token=<x-itoc360-token>"
        send_resolved: true
```

> `send_resolved: true` is required for automatic alert resolution on the platform.

#### Step 3 — Configure the Loki Ruler

Point the Loki Ruler to your external Alertmanager in `loki-config.yaml`:

```yaml
ruler:
  alertmanager_url: http://<alertmanager-host>:9093
  storage:
    type: local
    local:
      directory: /etc/loki/rules
  enable_api: true
```

#### Step 4 — Create Alert Rules

Create rule files in the configured rules directory. Loki uses **LogQL** for alert expressions, allowing you to alert on log content, patterns, and rates.

**Example: `rules/production.yaml`**

```yaml
groups:
  - name: loki-critical
    interval: 1m
    rules:
      - alert: HighErrorRate
        expr: |
          sum(rate({app="api"} |= "ERROR" [5m])) > 10
        for: 2m
        labels:
          severity: critical
        annotations:
          summary: "High error rate detected in API logs"
          description: "Application {{ $labels.app }} is producing more than 10 errors per second over the last 5 minutes."

      - alert: StackOverflowException
        expr: |
          count_over_time({app=~".+"} |= "StackOverflow" [5m]) > 0
        for: 0m
        labels:
          severity: critical
        annotations:
          summary: "StackOverflow exception detected in logs"
          description: "StackOverflow exception found in log stream {{ $labels.app }}."
```

> The `severity` label in `labels` is used by the platform for priority mapping (see table below).

> Loki alert rules use **LogQL** syntax — log stream selectors (`{app="api"}`) combined with filter expressions (`|= "ERROR"`) and metric queries (`rate`, `count_over_time`).

#### Step 5 — Verify the Integration

After starting Loki and Alertmanager:

1. Check Alertmanager UI at `http://<alertmanager-host>:9093` — active alerts should appear there first.
2. Trigger a test rule and wait for the `group_wait` period.
3. Confirm the alert appears on the platform under the source you created.

### Sample Payload

The following is a real payload captured during integration testing.

**ALERT (firing):**

```json
{
  "receiver": "itoc360-webhook",
  "status": "firing",
  "alerts": [
    {
      "status": "firing",
      "labels": {
        "alertname": "HighErrorRate",
        "env": "api",
        "severity": "critical"
      },
      "annotations": {
        "summary": "High error rate detected in API logs",
        "description": "Application api is producing more than 10 errors per second over the last 5 minutes."
      },
      "startsAt": "2026-03-10T10:44:47.805Z",
      "endsAt": "0001-01-01T00:00:00Z",
      "generatorURL": "/graph?g0.expr=...",
      "fingerprint": "34e164e9af873ac1"
    }
  ],
  "groupLabels": {},
  "commonLabels": {
    "alertname": "HighErrorRate",
    "env" : "test",
    "severity": "critical"
  },
  "commonAnnotations": {
    "summary": "High error rate detected in API logs"
  },
  "externalURL": "http://alertmanager:9093",
  "version": "4",
  "groupKey": "{}:{}",
  "truncatedAlerts": 0
}
```

**RESOLVE (resolved):**

```json
{
  "receiver": "itoc360-webhook",
  "status": "resolved",
  "alerts": [
    {
      "status": "resolved",
      "labels": {
        "alertname": "HighErrorRate",
        "severity": "critical"
      },
      "annotations": {
        "summary": "High error rate detected in API logs"
      },
      "startsAt": "2026-03-10T10:44:47.805Z",
      "endsAt": "2026-03-10T11:01:00.000Z",
      "fingerprint": "34e164e9af873ac1"
    }
  ],
  "status": "resolved",
  "version": "4"
}
```

### Field Mapping Reference

| Payload Field                       | Description                                                           |
| ----------------------------------- | --------------------------------------------------------------------- |
| `status`                            | Top-level event type: `firing` → ALERT, `resolved` → RESOLVE          |
| `alerts[0].fingerprint`             | Unique identifier per alert label set — used for fingerprint matching |
| `alerts[0].labels.alertname`        | Name of the alert rule that fired                                     |
| `alerts[0].labels.severity`         | Severity label from the rule definition — used for priority mapping   |
| `alerts[0].annotations.summary`     | Short human-readable alert title                                      |
| `alerts[0].annotations.description` | Detailed description of the alert condition                           |
| `alerts[0].startsAt`                | ISO 8601 timestamp when the alert started firing                      |
| `alerts[0].endsAt`                  | ISO 8601 timestamp when resolved (`0001-...` means still active)      |
| `commonLabels`                      | Labels shared across all alerts in this group                         |
| `commonAnnotations`                 | Annotations shared across all alerts in this group                    |
| `groupKey`                          | Alertmanager group key used for deduplication                         |

### Priority Mapping

The platform maps the `severity` label from the alert rule to an internal priority level.

| Loki `severity` Label | Platform Priority |
| --------------------- | ----------------- |
| `critical`            | CRITICAL          |
| `error`               | HIGH              |
| `warning`             | MEDIUM            |
| `info`                | LOW               |
| *(not set)*           | MEDIUM (default)  |

> You control the `severity` label in your alert rule definitions. Use consistent values across your rule files for predictable priority routing.

### RESOLVE Detection

The platform automatically resolves an alert when Alertmanager sends a payload with `"status": "resolved"`. This requires `send_resolved: true` in your Alertmanager webhook configuration (set in Step 2).

The resolved event is matched to the original alert using the `fingerprint` field, which Alertmanager generates deterministically from the alert's label set. As long as the labels do not change between firing and resolution, the fingerprint will match and the alert will be closed.


# OpenSearch Integration

OpenSearch's Alerting plugin can send every triggered monitor straight into ITOC360, where it becomes an alert and follows your on-call routing rules.

Unlike most tools, OpenSearch doesn't have a fixed alert payload — you decide what the webhook sends by writing a short message template. This page gives you that template, so you only need to copy it once.

### Before you start

You'll need:

* OpenSearch 2.0 or later, with the Alerting and Notifications plugins enabled
* A monitor that's already running (this page doesn't cover creating monitors)
* Your ITOC360 OpenSearch webhook URL, which includes your source token

> In OpenSearch 2.0 the old Alerting **Destinations** were replaced by **Notifications → Channels**. If your cluster still shows a Destinations tab, it will simply point you to Notifications.

### Get your webhook URL from ITOC360

1. In ITOC360, open **Integrations** and add a new **OpenSearch** integration.
2. Give it a name that matches the cluster or team it belongs to.
3. Copy the generated webhook URL. It already contains your source token, so treat it like a password.

### Create a notification channel in OpenSearch

Open the main menu and go to **Notifications → Channels**, then click **Create channel**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FIjRYLKc3GPEnDs2k0MjL%2F30_01-channels-list.png?alt=media&amp;token=3905506c-b890-463d-97fd-527c53dac259" alt="" width="563"><figcaption></figcaption></figure>

Fill in the form as follows:

| Field               | Value                                                                                                                             |
| ------------------- | --------------------------------------------------------------------------------------------------------------------------------- |
| Name                | `itoc360`                                                                                                                         |
| Channel type        | Custom webhook                                                                                                                    |
| Method              | POST                                                                                                                              |
| Define endpoints by | Webhook URL                                                                                                                       |
| Webhook URL         | [https://api.itoc360.app/functions/v1/events?token=\<x-itoc-360>](https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>) |
| Webhook header      | `Content-Type` → `application/json`                                                                                               |

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F1zOkJMpnCux3AOEojb4W%2F31_02-create-channel.png?alt=media&amp;token=12d7e862-55c7-4575-afa0-e388e949c67e" alt="" width="563"><figcaption></figcaption></figure>

Click **Create**. The channel is now available to every monitor in the cluster.

You can use **Send test message** to confirm the endpoint is reachable. Keep in mind that the test message is plain text rather than your template, so ITOC360 won't create an alert from it — it only proves the connection works.

### Add an action to your trigger

Open the monitor you want to forward, click **Edit**, and scroll down to **Triggers**. Expand the trigger you want to use and take note of its **Severity level** — ITOC360 uses that value to set the alert's priority.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FXbLr6ADVP5Y9qJi7LHqO%2F32_03-trigger-condition.png?alt=media&amp;token=2d121359-2de4-42a1-b38d-1d080d4012b2" alt="" width="563"><figcaption></figcaption></figure>

Under **Actions**, add an action:

1. Give the action a name.
2. Select the ITOC360 channel you just created.
3. Replace the contents of the **Message** box with the template below.

```
{
  "title": "{{ctx.monitor.name}} - {{ctx.trigger.name}}",
  "description": "{{ctx.monitor.name}} just entered Triggered status.",
  "monitor_name": "{{ctx.monitor.name}}",
  "alert_id": "{{ctx.trigger.id}}",
  "alert_time": "{{ctx.periodStart}}",
  "alert_severity": "{{ctx.trigger.severity}}",
  "status": "ALERT"
}
```

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FjOh3iwvJ33Do3orSPPQf%2F33_04-action-message-template.png?alt=media&amp;token=18ceac5b-d9a0-420a-ab36-0165cc56acc9" alt="" width="563"><figcaption></figcaption></figure>

Save the monitor. From now on, every time this trigger fires, itoc360 receives an alert.

### Close alerts automatically

OpenSearch doesn't send a notification when a condition stops matching, so recovery needs its own trigger. Add a second trigger to the same monitor:

1. Name it something like `<your-trigger>-resolve`.
2. Invert the trigger condition. If your alert trigger uses `ctx.results[0].hits.total.value > 0`, the recovery trigger uses:

```
ctx.results[0].hits.total.value == 0
```

3. Add an action pointing at the same ITOC360 channel, with this message template:

```
{
  "title": "{{ctx.monitor.name}} - {{ctx.trigger.name}}",
  "description": "{{ctx.monitor.name}} just returned to normal status.",
  "monitor_name": "{{ctx.monitor.name}}",
  "alert_id": "{{ctx.trigger.id}}",
  "alert_time": "{{ctx.periodStart}}",
  "alert_severity": "{{ctx.trigger.severity}}",
  "status": "RESOLVED"
}
```

The only difference from the first template is the `status` field. When ITOC360 receives `RESOLVED`, it closes the open alert for that monitor.

### Priority mapping

OpenSearch severity levels run from 1 to 5, where 1 is the most urgent. itoc360 maps them like this:

| OpenSearch severity | itoc360 priority |
| ------------------- | ---------------- |
| 1 (Highest)         | Critical         |
| 2                   | High             |
| 3                   | Medium           |
| 4                   | Low              |
| 5 (Lowest)          | Low              |

If a payload arrives without a severity, the alert is created with Medium priority.

### Verify the integration

The quickest way to confirm everything works end to end is to let the monitor run once while its condition is met. Within a few seconds you should see a new alert on the ITOC360 **Alerts** page, titled after your monitor and trigger.

If nothing arrives, check the following:

* **The trigger didn't actually fire.** Open the monitor's history — a green bar means the condition was never met, so no action ran.
* **Throttling is enabled on the action.** OpenSearch suppresses repeat notifications while throttling is active.
* **The webhook URL is incomplete.** The token is part of the URL; if it was truncated when pasting, requests are rejected.
* **The message body isn't valid JSON.** OpenSearch sends the message exactly as written, so a missing comma or quote will break the payload.


# Splunk Integration

Splunk is a platform for searching, monitoring, and analyzing machine data. This integration delivers triggered Splunk alerts to ITOC360 through the ITOC360 alert action app, so alerts fired by your saved searches open incidents on your dashboard and reach the right on-call engineer.

### How it works

The ITOC360 app adds a custom alert action to Splunk. When a saved search or alert triggers, the action sends the alert to ITOC360 with the search name as its title, the host from the triggering result, and the severity you selected. ITOC360 maps the severity to a priority and routes the alert through your escalation policies.

### Create a source in ITOC360

1. In ITOC360, go to **Sources** and click **Add Source**.
2. Select **Splunk** as the source type.
3. Give the source a name and save it.
4. Copy the generated source token — you will paste it into the alert action settings in Splunk.

### Install the ITOC360 app in Splunk

Install from Splunkbase:

1. In Splunk Web, go to **Apps → Find More Apps**.
2. Search for **ITOC360** and click **Install**.

Or install from file:

1. Download the app package from Splunkbase.
2. In Splunk Web, go to **Apps → Manage Apps → Install app from file**.
3. Upload the package and restart Splunk if prompted.

### Add the alert action to an alert

1. Run the search you want to alert on, then click **Save As → Alert**. Give it a title, set the schedule (for example a cron schedule), and define the trigger condition.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FJrKnM9QRkfUm54VVxaKb%2F19_splunk-save-as-alert.png?alt=media&amp;token=fa76b52d-3baa-4b20-bcc7-c61f85b7f609" alt="" width="563"><figcaption></figcaption></figure>

1. Under **Trigger Actions**, click **Add Actions** and select **ITOC360**.
2. Configure the action:

| Parameter    | Description                                                                            | Default      |
| ------------ | -------------------------------------------------------------------------------------- | ------------ |
| Source token | Token of your ITOC360 Splunk source                                                    | — (required) |
| Severity     | Severity assigned to alerts from this action: critical, high, medium, or low           | medium       |
| Host field   | Result field used as the alert host; falls back to the Splunk server name when missing | host         |

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fb9K58ou6w0Na62Vz3uFl%2F20_splunk-itoc360-action.png?alt=media&amp;token=861a01d8-995b-45b6-8c6e-1769742eac91" alt="" width="563"><figcaption></figcaption></figure>

4. Click **Save**. The alert summary page shows ITOC360 listed under Actions.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FVMheyQBffXT806E6aw5j%2F21_splunk-alert-saved.png?alt=media&amp;token=5e89b741-4308-4bdd-8d79-3051b51e5f70" alt="" width="563"><figcaption></figcaption></figure>

### Priority mapping

ITOC360 maps the severity you select to an alert priority:

| Severity | ITOC360 priority |
| -------- | ---------------- |
| critical | CRITICAL         |
| high     | HIGH             |
| medium   | MEDIUM           |
| low      | LOW              |

### Verify the integration

1. Create a test alert with a search that always returns results, for example `index=_internal | head 5`, scheduled to run every few minutes with a trigger condition of **Number of Results > 0**.
2. Attach the ITOC360 action with your source token.
3. When the alert triggers, it appears on your ITOC360 dashboard with the search name as its title.
4. If nothing arrives, search `index=_internal itoc360` in Splunk — the action logs each delivery attempt and any errors there.


# Sumo Logic Integration

Sumo Logic is a cloud-based log management and analytics platform that provides real-time insights into applications and infrastructure. This integration delivers alerts from Sumo Logic monitors to ITOC360 through a webhook connection, so triggered monitors open alerts on your dashboard and recovered monitors resolve them automatically.

### How it works

Sumo Logic sends a webhook request to ITOC360 whenever a monitor triggers or recovers. ITOC360 creates an alert when the monitor fires, maps its severity to a priority, and resolves the alert when the recovery notification arrives.

### Create a source in ITOC360

1. In ITOC360, go to **Sources** and click **Add Source**.
2. Select **Sumo Logic** as the source type.
3. Give the source a name and save it.
4. Copy the generated webhook URL with your token. It looks like this:

```
https://api.itoc360.app/functions/v1/events?token=YOUR_TOKEN
```

### Create a webhook connection in Sumo Logic

1. In Sumo Logic, go to **Administration → Connections** and click **Add**.
2. Select **Webhook** as the connection type.
3. Name the connection (for example, `ITOC360`).
4. Paste your ITOC360 webhook URL into the **URL** field.
5. Leave **Authorization Header** and **Custom Headers** empty — the token in the URL handles authentication.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FSgwQ3KDbJmY99mmsm4Zd%2F18_WhatsApp%20Image%202026-07-08%20at%2021.53.34.png?alt=media&amp;token=3885d63c-c985-4879-81c7-a23fd3dffb94" alt="" width="563"><figcaption></figcaption></figure>

### Configure the payloads

Replace the default **Alert Payload** with the following:

```json
{
  "title": "{{Name}}",
  "description": "{{Description}}",
  "host": "sumo-logic",
  "severity": "{{TriggerType}}",
  "status": "Active",
  "alert_id": "{{Id}}",
  "trigger_time": "{{TriggerTime}}"
}
```

Replace the **Recovery Payload** with the following:

```json
{
  "title": "{{Name}}",
  "description": "{{Description}}",
  "status": "Resolved",
  "alert_id": "{{Id}}",
  "trigger_time": "{{TriggerTime}}"
}
```

The recovery payload intentionally omits the severity and host fields — Sumo Logic does not provide these variables in the recovery context. ITOC360 matches the recovery to the original alert using the alert ID, so the alert resolves correctly without them.&#x20;

Click **Save** to store the connection.

### Attach the connection to a monitor

1. Go to **Monitoring → Monitors** and create or edit a monitor.
2. In the **Notifications** section, choose **Webhook** as the connection type and select your ITOC360 connection.
3. Enable the notification for both **Alert** and **Recovery** so ITOC360 receives the full lifecycle.
4. Save the monitor.

### Priority mapping

ITOC360 maps the Sumo Logic trigger type to an alert priority:

| Sumo Logic trigger | ITOC360 priority |
| ------------------ | ---------------- |
| Critical           | CRITICAL         |
| Warning            | MEDIUM           |
| MissingData        | LOW              |

### Verify the integration

1. Open the connection in Sumo Logic and click **Test Alert**. A test alert appears on your ITOC360 dashboard.
2. Click **Test Recovery**. The test alert resolves.
3. When a real monitor triggers, the alert arrives with the monitor name as its title and the trigger type mapped to its priority. It resolves automatically when the monitor's recovery condition is met.

{% hint style="warning" %} Resolving an alert manually inside Sumo Logic does not send a recovery notification to webhooks. Alerts resolve in ITOC360 when the monitor's recovery condition is met or when the monitor is disabled. {% endhint %}


# Security

This category covers cloud-native security and threat detection platforms. These tools monitor your environments for suspicious activity, misconfigurations, and active threats — and send high-priority alerts to ITOC360 to ensure the right security engineer is reached immediately.

***

### Integrations in this category

| Integration                        | What it monitors                                                            | Alert delivery        |
| ---------------------------------- | --------------------------------------------------------------------------- | --------------------- |
| **AWS GuardDuty**                  | Threat detection across AWS accounts, IAM, S3, and network activity         | Webhook (EventBridge) |
| **Azure Sentinel**                 | Cloud-native SIEM: log analytics, threat intelligence, incident correlation | Webhook               |
| **Google Security Command Center** | GCP asset vulnerabilities, misconfigurations, and active threats            | Webhook               |
| **CrowdStrike**                    | Endpoint detection and response, threat intelligence                        | Webhook               |

***

### How it works

Security platforms continuously analyze activity logs, network traffic, and endpoint behavior for indicators of compromise. When a threat is detected or a security rule is triggered, the platform sends an alert to your ITOC360 Source webhook URL. ITOC360 applies your escalation policy for that source and immediately notifies the designated security on-call engineer through their configured channel.

{% hint style="warning" %}
Security alerts are typically high severity. Make sure your escalation policy for security sources has short timeouts and at least two escalation levels to ensure critical threats are never missed.
{% endhint %}

***

### Get started


# CrowdStrike Integration

### Overview

This document describes the integration between [CrowdStrike Falcon](https://www.crowdstrike.com/en-us/) and our alert management platform. CrowdStrike Falcon is an endpoint detection and response (EDR) platform that monitors devices for threats, malware, and suspicious behavior in real time. When a detection or incident is triggered, Falcon can deliver a structured webhook payload to external systems for centralized alerting and on-call management.

This integration uses CrowdStrike's **Falcon Fusion SOAR** workflow engine to send detection events via webhook to the platform endpoint.

### Integration Flow

1. CrowdStrike Falcon detects a threat or suspicious activity on a monitored endpoint.
2. A Falcon Fusion SOAR workflow is triggered, evaluating the detection against configured conditions.
3. The workflow executes a **Call Webhook** action using the configured webhook from the CrowdStrike Store, sending the detection payload to the platform.
4. When a detection is closed or resolved in CrowdStrike, the workflow sends an updated payload with `status: closed` to clear the alert on the platform.

### Webhook Payload Schema

The payload sent to the platform is constructed using CrowdStrike Fusion template variables. The following schema is the recommended structure for this integration.

| Field        | Type   | Required | Description                                                               |
| ------------ | ------ | -------- | ------------------------------------------------------------------------- |
| incident\_id | string | Yes      | Unique detection ID used to correlate trigger and resolution events       |
| title        | string | Yes      | Human-readable detection title, typically includes detection name         |
| status       | string | Yes      | Current detection status: `new`, `in_progress`, `true_positive`, `closed` |
| severity     | string | Yes      | Severity label: `Critical`, `High`, `Medium`, `Low`, `Informational`      |
| description  | string | No       | Detailed description of the detected behavior or threat                   |
| host         | string | No       | Hostname of the affected endpoint                                         |
| link         | string | No       | Direct URL to the detection in the Falcon console                         |
| timestamp    | string | No       | ISO 8601 timestamp of when the detection was created                      |

### Severity / Status Mapping

#### Status → Alert Type

| CrowdStrike Status | Platform Status | Description                               |
| ------------------ | --------------- | ----------------------------------------- |
| new                | ALERT           | Detection is newly created and unreviewed |
| in\_progress       | ALERT           | Detection is being actively investigated  |
| true\_positive     | ALERT           | Detection confirmed as a real threat      |
| closed             | RESOLVE         | Detection has been closed or resolved     |

#### Severity → Priority

| CrowdStrike Severity | Platform Priority |
| -------------------- | ----------------- |
| Critical             | CRITICAL          |
| High                 | HIGH              |
| Medium               | MEDIUM            |
| Low                  | LOW               |
| Informational        | LOW               |

### Alert Payload Examples

#### Raised (New Detection)

This payload is sent when CrowdStrike Falcon detects a new threat on an endpoint.

```json
{
  "description": "A suspicious PowerShell command was executed with encoded parameters, commonly used to evade detection.",
  "detection_id": "ldt:abc123def456:789012345",
  "event_id": "evt-abc123def456789012345",
  "link": "https://falcon.crowdstrike.com/activity/detections/detail/ldt:abc123def456:789012345",
  "severity": "High",
  "severity_score": "70",
  "source": "WORKSTATION-042",
  "status": "new",
  "summary": "Suspicious PowerShell Execution",
  "timestamp": "2026-02-26T10:15:30.000Z"
}
```

#### Cleared (Detection Closed)

This payload is sent when the detection is reviewed and closed in the Falcon console.

```json
{
  "description": "Detection reviewed and closed by analyst. Confirmed false positive.",
  "detection_id": "ldt:abc123def456:789012345",
  "event_id": "evt-abc123def456789012345",
  "link": "https://falcon.crowdstrike.com/activity/detections/detail/ldt:abc123def456:789012345",
  "severity": "High",
  "severity_score": "70",
  "source": "WORKSTATION-042",
  "status": "closed",
  "summary": "Suspicious PowerShell Execution",
  "timestamp": "2026-02-26T10:45:00.000Z"
}
```

### Installation & Configuration

#### Step 1: Create an Alert Source in the Platform

1. Log in to the alert management platform.
2. Navigate to **Integrations** → **Add Integration**.
3. Select **CrowdStrike Falcon** as the provider.
4. Name the integration (e.g., `CrowdStrike Production`).
5. Paste [https://api.itoc360.app/functions/v1/events?token=\<x-itoc360-token>](https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>) URL.

#### Step 2: Open Falcon Fusion SOAR

1. Log in to the **CrowdStrike Falcon Console**.<br>

   <figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FfV10su9YEn1kYomrErJg%2FEkran%20Resmi%202026-02-27%2000.56.44.png?alt=media&amp;token=14e69eb5-b153-4206-b2fa-2bd42200735f" alt=""><figcaption></figcaption></figure>
2. Click the **CrowdStrike** logo on the top left and choose **Workflows**.<br>

   <figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FlZQuwbCie3LdYEaZjv2G%2Fimage%20(66).png?alt=media&amp;token=b9384324-f53e-4e4d-8b7d-b47e442345de" alt=""><figcaption></figcaption></figure>
3. Click **Create a Workflow** on the top right.<br>

   <figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F7wkfr7DhBDKNyJth1KyW%2Fimage%20(59).png?alt=media&amp;token=d9b85b45-bbcc-4bca-83c1-e6f25af10b7c" alt=""><figcaption></figcaption></figure>

#### Step 3: Configure the Trigger

1. On the workflow canvas, add a trigger and choose **New Detection**.<br>

   <figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FIeTLr8NyNcUIkKwa1NCn%2Fimage%20(60).png?alt=media&amp;token=bea62ec2-0f77-45cf-9f54-542935a038e4" alt=""><figcaption></figcaption></figure>
2. Optionally add a **Condition** to filter by severity (e.g., severity greater than Medium).<br>

   <figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FlQY4p00NyY3VzbhXQZj4%2Fimage%20(52).png?alt=media&amp;token=a9467142-cdcb-480c-84f0-052e0cf00ef7" alt=""><figcaption></figcaption></figure>

#### Step 4: Configure the Webhook from Store

1. Click **Add Action** → choose Action type **Notification** → select **Call Webhook**.<br>

   <figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FGXT6k7js8cQu8TfT1TIe%2Fimage%20(61).png?alt=media&amp;token=031b4d7c-9dfd-4b83-a4e5-cbd51327058b" alt=""><figcaption></figcaption></figure>
2. If the webhook is not yet configured, click the **Store** link and click **Configure** on the Webhook item.<br>

   <figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FfXWXfMvorFWxHwPmZgr6%2Fimage%20(62).png?alt=media&amp;token=58116e6f-f339-4db7-afff-b076f5309856" alt=""><figcaption></figcaption></figure>

   <figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FTRZCxVkP9qvFk25laaa9%2Fimage%20(63).png?alt=media&amp;token=795a4e4c-d838-440e-b596-134530254118" alt=""><figcaption></figcaption></figure>
3. The **Configure CrowdStrike Webhook** modal will open.<br>

Fill in the fields as follows:

* **Name**: A descriptive name for this connection (e.g., `platform-oncall`)
* **Webhook URL**: [https://api.itoc360.app/functions/v1/events?token=\<x-itoc-360>](https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>) URL.
* **HMAC Secret Key**: Leave empty
* **Signature Header Name**: Leave as default (x-itoc-360)
* **Custom headers**: Add your platform token on line 1:<br>

  <figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FDGXvJ3cQQ9IQiUG3qMey%2Fimage%20(64).png?alt=media&amp;token=f1167ce5-1244-478c-8992-84c486a118ee" alt=""><figcaption></figcaption></figure>

4. Click **Save configuration**.

#### Step 5: Set the JSON Body

1. Back in the workflow canvas, select the webhook you just configured.
2. In the data field, paste the following JSON body:

```json
{
  "description": "{{Detection.Description}}",
  "detection_id": "{{Detection.ID}}",
  "event_id": "{{ID}}",
  "link": "{{SourceEventURL}}",
  "severity": "{{Detection.SeverityDisplayName}}",
  "severity_score": "{{Detection.Severity}}",
  "source": "{{Source}}",
  "status": "{{Detection.Status}}",
  "summary": "{{Detection.Name}}",
  "timestamp": "{{ObservedTime}}"
}
```

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FiWnXDQWIW6NjL38FbiDK%2Fimage%20(2)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=33bc5bc0-cc87-4401-b408-b9596b89ff58" alt=""><figcaption></figcaption></figure>

#### Step 6: Save and Activate the Workflow

1. Click **Save** to save the workflow.
2. Toggle the workflow to **Active**.
3. For recovery notifications, create a second workflow triggered on detection  status change to `closed`, using the same webhook and JSON body.<br>

   <figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F3lCjBhGwQ4uiwNG8PNiV%2FEkran%20Resmi%202026-02-27%2000.45.04.png?alt=media&amp;token=41fc4f66-b591-4248-ad6f-ab3f19ff1ce3" alt=""><figcaption></figcaption></figure>

   <figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FHMoQ9xNjdl9b7ZKsuqRU%2FEkran%20Resmi%202026-02-27%2001.24.44.png?alt=media&amp;token=569c0703-59c8-4388-b4cc-6411c37ce571" alt=""><figcaption></figcaption></figure>

## Testing

#### Method 1: Trigger a Test Detection

1. In the Falcon console, navigate to **Activity** → **Detections**.
2. Use a test or simulated detection event if available in your environment.
3. Verify the payload is received in the platform's event log.

#### Method 2: Replay a Workflow

1. Navigate to **Fusion SOAR** → **Workflows**.
2. Open the configured workflow.
3. Click **Run** or **Test** to manually execute the workflow with a sample event.
4. Check the platform's `events` and `alerts` tables for the incoming record.

#### Method 3: Validate with Webhook.site

Before connecting to the platform, set the Webhook URL to `https://webhook.site` temporarily to inspect the raw payload and confirm all template variables are resolving correctly.

### Troubleshooting

| Issue                      | Possible Cause                                   | Resolution                                                                                         |
| -------------------------- | ------------------------------------------------ | -------------------------------------------------------------------------------------------------- |
| No alerts received         | Workflow not active                              | Ensure the workflow is toggled to Active in Falcon Fusion                                          |
| No alerts received         | Incorrect webhook URL or token                   | Verify the Webhook URL and `x-itoc360-token` in Custom headers of the webhook configuration        |
| Template variables empty   | Wrong variable path in JSON body                 | Test the workflow and inspect the raw payload in webhook.site to verify variable resolution        |
| Recovery alerts missing    | No separate workflow for closed detections       | Create a second workflow triggered on detection status change to `closed`                          |
| Invalid payload error      | Missing required fields in the JSON body         | Ensure `incident_id`, `title`, `status`, and `severity` are all present and non-empty              |
| Duplicate alerts           | Workflow triggering on every detection update    | Add a condition to trigger only on `status = new` for the alert workflow                           |
| Severity not mapping       | `severity_display_name` returns unexpected value | Check the Falcon console for the exact severity string and update the platform mapping accordingly |
| Webhook config not visible | Webhook not yet added from Store                 | Navigate to Store → Configure the Webhook item before selecting it in the workflow action          |


# Azure Sentinel Integration

### Overview

Microsoft Sentinel is a cloud-native SIEM and SOAR solution built on Azure. It provides intelligent security analytics and threat intelligence across the enterprise, with a single solution for alert detection, threat visibility, proactive hunting, and threat response.

This guide walks you through integrating Microsoft Sentinel with the alert management platform. Since Sentinel does not natively support outbound HTTP webhooks, the integration is implemented using Azure Logic Apps (Playbooks) as middleware. When a Sentinel incident is created, an Automation Rule triggers a Logic App playbook that formats and forwards the incident payload via HTTP POST to the platform webhook.

***

### Integration Flow

1. A security event or custom Analytics rule triggers a new Incident in Microsoft Sentinel.
2. The Sentinel Automation Rule detects the incident creation and runs the configured Logic App playbook.
3. The Logic App sends an HTTP POST request to the platform webhook with the structured incident payload.
4. The platform receives the payload, validates the schema, and creates an alert with the appropriate severity.

***

### Webhook Payload Schema

The payload is sent by the Logic App as a custom-structured JSON object built from the Sentinel incident trigger output.

| **Field**        | **Type** | **Required** | **Description**                                        |
| ---------------- | -------- | ------------ | ------------------------------------------------------ |
| IncidentName     | string   | Yes          | Display name of the Sentinel incident                  |
| IncidentNumber   | integer  | Yes          | Auto-incremented incident identifier in the workspace  |
| Severity         | string   | Yes          | Incident severity: High, Medium, Low, or Informational |
| Status           | string   | Yes          | Current lifecycle status: New, Active, or Closed       |
| Description      | string   | No           | Optional description of the incident (may be null)     |
| WorkspaceId      | string   | Yes          | Unique identifier of the Log Analytics workspace       |
| CreatedTime      | string   | Yes          | ISO 8601 timestamp of when the incident was created    |
| LastModifiedTime | string   | Yes          | ISO 8601 timestamp of the last modification            |

***

### Severity / Status Mapping

Sentinel's `Severity` field maps directly to platform priority:

| **Sentinel Severity** | **Platform Priority** | **Description**                                       |
| --------------------- | --------------------- | ----------------------------------------------------- |
| High                  | CRITICAL              | High severity incident, immediate response required   |
| Medium                | HIGH                  | Medium severity incident, prompt investigation needed |
| Low                   | MEDIUM                | Low severity incident, investigate when possible      |
| Informational         | LOW                   | Informational event, no immediate action required     |

Sentinel `Status` maps to platform alert lifecycle:

| **Sentinel Status** | **Platform Status** | **Description**                            |
| ------------------- | ------------------- | ------------------------------------------ |
| New                 | PROBLEM             | New incident created, not yet investigated |
| Active              | PROBLEM             | Incident is currently being investigated   |
| Closed              | RECOVERY            | Incident has been resolved and closed      |

***

### Alert Payload Examples

#### Raised (New Incident)

This payload is sent when a new Sentinel incident is created and the automation rule triggers the Logic App. The `Status` field is `"New"` and `Severity` reflects the analytics rule configuration.

```
{
  "IncidentName": "OnCall Webhook Test Alarm",
  "IncidentNumber": 108,
  "Severity": "Medium",
  "Status": "New",
  "Description": null,
  "WorkspaceId": "32382f81-6cf6-416f-9bfb-5c6a224c5843",
  "CreatedTime": "2026-02-24T01:11:49.84Z",
  "LastModifiedTime": "2026-02-24T01:11:50.03Z"
}
```

### Installation & Configuration

#### Step 1: Create an Alert Source in the Platform

1. Log in to the alert management platform.
2. Navigate to Integrations → Add Integration.
3. Select Microsoft Sentinel (or Custom Webhook) as the provider.
4. Name the integration (e.g., `Production Sentinel Alerts`).
5. Paste [https://api.itoc360.app/functions/v1/events?token=\<x-itoc360-token>](https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>) URL.

***

#### Step 2: Create a Log Analytics Workspace & Add Sentinel

Microsoft Sentinel requires a Log Analytics workspace. If you already have one, skip to Step 3.

1. In the Azure Portal, search for Log Analytics workspaces and click + Create.
2. Create a new Resource Group (e.g., `sentinel-rg`) and name your workspace (e.g., `sentinel-workspace`). Complete the deployment.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FB0wk8gCYCMc1Jai40j0K%2Fimage%20(32).png?alt=media&amp;token=e124bf0d-de2d-459c-9145-c1854efb78a1" alt=""><figcaption></figcaption></figure>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FVzC60revvEJLl50nISaQ%2Fimage%20(31).png?alt=media&amp;token=885132dd-92e7-4605-b18d-dba1db2cd07b" alt=""><figcaption></figcaption></figure>

3. Search for Microsoft Sentinel in the Azure Portal, click + Create, select your newly created workspace, and click Add.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FoQGE8YgYPWDSGLA8rVZq%2Fimage%20(33).png?alt=media&amp;token=37f25bc6-753a-4722-81cf-37c2555d509b" alt=""><figcaption></figcaption></figure>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FymZ1aJ1jyNKqyXdCj6p7%2Fimage%20(34).png?alt=media&amp;token=d58c73da-1b32-4332-944c-a9ffdaa63684" alt=""><figcaption></figcaption></figure>

***

#### Step 3: Create a Logic App (Playbook)

*CRITICAL: To avoid trigger recognition bugs, always create the Playbook directly from within Sentinel, NOT from the general Azure Logic Apps menu.*

1. In the Azure Portal, go to Microsoft Sentinel and select your workspace.
2. In the left sidebar, under Configuration, click Automation.
3. Click + Create at the top and select Playbook with incident trigger.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FXZ237KKwqeLdwFzXcIm8%2Fimage%20(35).png?alt=media&amp;token=4e46535c-0fc7-4c85-a202-c4dfa727072f" alt=""><figcaption></figcaption></figure>

4. Select your Resource Group (`sentinel-rg`) and name your playbook (e.g., `SentinelWebhookPlaybook`). Click Review + create and complete the deployment.

***

#### Step 4: Configure the Logic App Workflow

1. Open your newly created Logic App (`SentinelWebhookPlaybook`) and go to Logic app designer.
2. The trigger Microsoft Sentinel incident will already be there. Click the + button below it and select Add an action.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FTwi8eNAO8PPUcfEOQsOk%2FEkran%20Resmi%202026-02-24%2015.53.06.png?alt=media&amp;token=059b87ee-638a-4acc-87fa-3ccd9c4c104f" alt=""><figcaption></figcaption></figure>

3. Search for HTTP and add the green HTTP action. Configure it exactly as follows:
   * Method: `POST`
   * URI: Your platform webhook URL (from Step 1)
   * Headers: Key = `Content-Type`, Value = `application/json` *(⚠️ Ensure there are NO trailing spaces in the value)*.
   * Body: Compose the JSON payload using the Dynamic content menu to map Sentinel incident fields:

JSON

```
{
  "IncidentName": @{triggerBody()?['object']?['properties']?['title']},
  "IncidentNumber": @{triggerBody()?['object']?['properties']?['incidentNumber']},
  "Severity": @{triggerBody()?['object']?['properties']?['severity']},
  "Status": @{triggerBody()?['object']?['properties']?['status']},
  "Description": @{triggerBody()?['object']?['properties']?['description']},
  "WorkspaceId": @{triggerBody()?['workspaceId']},
  "CreatedTime": @{triggerBody()?['object']?['properties']?['createdTimeUtc']},
  "LastModifiedTime": @{triggerBody()?['object']?['properties']?['lastModifiedTimeUtc']}
}
```

4. Click Save.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FCLX7FIwAdL2ExJlK6PyD%2FEkran%20Resmi%202026-02-24%2015.53.52.png?alt=media&amp;token=7031761e-c099-41c0-a803-f8d3a9712906" alt=""><figcaption></figcaption></figure>

***

#### Step 5: Grant Permissions to Azure Security Insights (CRITICAL)

For Sentinel to automatically trigger your playbook, its background service (`Azure Security Insights`) must have explicit permission on the resource group.

1. In the Azure Portal search bar, type Resource groups and open `sentinel-rg`.
2. Click Access control (IAM) in the left menu.
3. Click + Add → Add role assignment.
4. Search for and select the Microsoft Sentinel Automation Contributor role. Click Next.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FbHWLOjdcQpCOFYqCGb5L%2FEkran%20Resmi%202026-02-24%2015.57.02.png?alt=media&amp;token=4b90690e-a11d-42e3-86f0-aec9df1b0f5f" alt=""><figcaption></figcaption></figure>

5. Under "Assign access to", select User, group, or service principal.
6. Click + Select members, search for Azure Security Insights, and select it.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F1Zd9v23U0kFd0ZTVOXkn%2FEkran%20Resmi%202026-02-24%2015.57.53.png?alt=media&amp;token=47d94de5-7e5d-4170-a566-55455dd1d085" alt=""><figcaption></figcaption></figure>

7. Click Review + assign. *(Note: If you get a "Role assignment already exists" error, you can safely skip this step).*

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Frz1Zf9auNya7exx85OOM%2FEkran%20Resmi%202026-02-24%2015.58.50.png?alt=media&amp;token=04d303ba-8ddb-4e3a-b3b5-5d933ab21bb2" alt=""><figcaption></figcaption></figure>

#### Step 6: Create a Sentinel Automation Rule

1. Return to the Microsoft Sentinel console → Automation.
2. Click + Create → Automation rule.
3. Configure the rule:
   * Trigger: `When incident is created`
   * Actions: `Run playbook`
   * Open the playbook dropdown and select your Logic App (`SentinelWebhookPlaybook`).
4. Click Apply.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FgisZZTFFx5DPT2DZbY1k%2Fimage%20(30).png?alt=media&amp;token=b829af08-bea0-4c13-ab7b-cde719d779dc" alt=""><figcaption></figcaption></figure>

***

### Testing

To verify the integration end-to-end, create a scheduled analytics rule to generate a test incident.

1. In Sentinel, navigate to Analytics. Click + Create → Scheduled query rule.
2. Set Name to `OnCall Webhook Test Alarmı` and Severity to `Medium`.
3. In the Set rule logic tab, use the following KQL query:

Code snippet:

```
print Message="OnCall Test Alarmı"
| extend TimeGenerated = now()
```

4. Set query scheduling to run every 5 Minutes and ensure "Create incidents from alerts" is Enabled. Save the rule.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FzUGTTLvtAF0BmZXxvIGP%2FEkran%20Resmi%202026-02-24%2016.09.15.png?alt=media&amp;token=e392a58e-fbec-4b01-ba35-2d3087d5ea66" alt=""><figcaption></figcaption></figure>

5. Wait up to 5 minutes. Check the Incidents page in Sentinel to confirm the incident was created.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FpQsQEysxLjr99ZqxWAuH%2FEkran%20Resmi%202026-02-24%2016.09.49.png?alt=media&amp;token=88a070c6-a901-444d-8e2b-a92b309fd922" alt=""><figcaption></figcaption></figure>

6. Verify your webhook endpoint to ensure the JSON payload was received successfully. You can also check the Logic App's Run history for a `Succeeded` status.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FWmbCybXXe9ddenI7kdbG%2FEkran%20Resmi%202026-02-24%2016.10.36.png?alt=media&amp;token=d5a9ba52-747a-4b5a-af44-7167dfb9fa4f" alt=""><figcaption></figcaption></figure>

### Troubleshooting

| **Issue**                                            | **Possible Cause**                                | **Resolution**                                                                                                                                                                                               |
| ---------------------------------------------------- | ------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| Logic App run history shows `Failed` (Bad Request)   | Format error in HTTP Headers.                     | Edit the Logic App HTTP action and ensure the `Content-Type` value is exactly `application/json` without any trailing spaces.                                                                                |
| Playbook does not appear in Automation Rule dropdown | Incorrect Playbook creation or missing IAM roles. | Ensure you created the Playbook from within Sentinel, NOT the general Logic Apps menu. Verify that `Azure Security Insights` has the `Microsoft Sentinel Automation Contributor` role on the Resource Group. |
| Incidents are created but Playbook does not trigger  | Automation rule misconfigured.                    | Verify the Automation Rule trigger is set to "When incident is created" (not Alert) and the rule is "Enabled".                                                                                               |
| Empty fields in the received alert                   | Dynamic content mismatch.                         | Open the Logic app designer and ensure the dynamic content tokens in your JSON body match the specific Sentinel incident schema fields.                                                                      |


# AWS GuardDuty Integration

AWS GuardDuty is a threat detection service that continuously monitors your AWS accounts and workloads for malicious activity and unauthorized behavior. It analyzes events from AWS CloudTrail, VPC Flow Logs, and DNS logs using machine learning, anomaly detection, and integrated threat intelligence to identify threats such as unauthorized access, data exfiltration attempts, compromised EC2 instances, and cryptocurrency mining.

This integration routes GuardDuty security findings to the alert management platform via **Amazon SNS + AWS EventBridge**. When GuardDuty detects a threat, EventBridge captures the finding and forwards it to an SNS topic, which delivers the payload to the platform's webhook endpoint. The platform maps the finding's numeric severity score to a standardized priority level and opens an alert for the on-call team.

> **Note:** GuardDuty findings are one-directional — the service does not send a separate "resolved" event when a finding is archived. Alerts created from GuardDuty findings must be manually closed in the platform after investigation.

### Integration Flow

```
AWS GuardDuty
      │
      │  Detects threat / finding
      ▼
Amazon EventBridge
      │
      │  Rule matches "GuardDuty Finding"
      ▼
Amazon SNS Topic
      │
      │  HTTPS subscription delivers payload
      ▼
Platform Webhook Endpoint
      │
      │  Schema validation + SNS Message parsing
      ▼
Alert Created → Priority mapped → On-Call Team Notified
```

### Payload Schema

GuardDuty payloads arrive as SNS notification envelopes. The `Message` field contains a JSON-serialized EventBridge event with the full finding detail nested inside.

#### Outer SNS Envelope

| Field       | Type   | Description                                                              |
| ----------- | ------ | ------------------------------------------------------------------------ |
| `Type`      | string | SNS message type (`Notification` or `SubscriptionConfirmation`)          |
| `MessageId` | string | Unique identifier for this SNS message                                   |
| `TopicArn`  | string | ARN of the SNS topic that delivered the message                          |
| `Message`   | string | **JSON-serialized EventBridge event** — parse this to access the finding |
| `Timestamp` | string | ISO 8601 timestamp when SNS delivered the message                        |
| `Subject`   | string | SNS message subject (optional)                                           |

#### Parsed `Message` Field (EventBridge Event)

| Field                | Type   | Description                                                   |
| -------------------- | ------ | ------------------------------------------------------------- |
| `version`            | string | EventBridge schema version                                    |
| `id`                 | string | Unique EventBridge event ID                                   |
| `source`             | string | Always `aws.guardduty`                                        |
| `detail-type`        | string | Always `GuardDuty Finding`                                    |
| `region`             | string | AWS region where the finding was generated                    |
| `account`            | string | AWS account ID                                                |
| `detail.id`          | string | Unique GuardDuty finding ID — used as the alert fingerprint   |
| `detail.type`        | string | Finding type (e.g., `UnauthorizedAccess:EC2/SSHBruteForce`)   |
| `detail.severity`    | number | Numeric severity score from `0.1` to `8.9`                    |
| `detail.title`       | string | Short human-readable description of the finding               |
| `detail.description` | string | Detailed explanation of the threat                            |
| `detail.accountId`   | string | AWS account where the threat was detected                     |
| `detail.region`      | string | Region where the affected resource resides                    |
| `detail.createdAt`   | string | ISO 8601 timestamp when the finding was first created         |
| `detail.updatedAt`   | string | ISO 8601 timestamp of the most recent finding update          |
| `detail.resource`    | object | Details about the affected AWS resource (EC2, IAM, S3, etc.)  |
| `detail.service`     | object | GuardDuty service metadata including action type and evidence |

### Severity Mapping

GuardDuty uses a continuous numeric severity scale. The platform maps these values to standardized priority levels as follows:

| GuardDuty Severity Range | Label    | Platform Priority |
| ------------------------ | -------- | ----------------- |
| `8.0 – 8.9`              | Critical | `CRITICAL`        |
| `7.0 – 7.9`              | High     | `HIGH`            |
| `4.0 – 6.9`              | Medium   | `MEDIUM`          |
| `0.1 – 3.9`              | Low      | `LOW`             |

> AWS currently uses severity values in the `0.1 – 8.9` range. Values `0` and `9.0 – 10.0` are reserved for future use.

### Payloads

#### Finding Detected (ALERT)

This is a real payload captured from AWS GuardDuty via SNS. The `Message` field arrives as a JSON string and must be parsed to access the finding detail.

json

```json
{
  "Type": "Notification",
  "MessageId": "a1b2c3d4-e5f6-7890-abcd-ef0123456789",
  "TopicArn": "arn:aws:sns:us-west-2:111222333444:GuardDutyAlerts",
  "Message": "{\"version\":\"0\",\"id\":\"abcd1234-5678-90ef-ghij-klmnopqrstuv\",\"detail-type\":\"GuardDuty Finding\",\"source\":\"aws.guardduty\",\"account\":\"111222333444\",\"time\":\"2026-01-15T09:42:11Z\",\"region\":\"us-west-2\",\"resources\":[],\"detail\":{\"schemaVersion\":\"2.0\",\"accountId\":\"111222333444\",\"region\":\"us-west-2\",\"id\":\"ffffeeee111122223333444455556666\",\"type\":\"UnauthorizedAccess:Runtime/TorClient\",\"severity\":4,\"createdAt\":\"2026-01-15T09:38:44.123Z\",\"updatedAt\":\"2026-01-15T09:38:44.123Z\",\"title\":\"The EC2 instance i-abcde12345 is communicating with a Tor entry node.\",\"description\":\"The process SomeRandomProcess from EC2 instance i-abcde12345 is communicating with an IP address 203.0.113.45 on the Tor Anonymizing Proxy network marked as an entry node.\",\"resource\":{\"resourceType\":\"KubernetesCluster\",\"instanceDetails\":{\"instanceId\":\"i-abcde12345\",\"instanceType\":\"t3.large\"}},\"service\":{\"serviceName\":\"guardduty\",\"action\":{\"actionType\":\"NETWORK_CONNECTION\",\"networkConnectionAction\":{\"connectionDirection\":\"OUTBOUND\",\"remoteIpDetails\":{\"ipAddressV4\":\"203.0.113.45\"}}},\"eventFirstSeen\":\"2026-01-15T09:38:44.000Z\",\"eventLastSeen\":\"2026-01-15T09:38:44.000Z\",\"archived\":false,\"count\":2}}}",
  "Timestamp": "2026-01-15T09:42:11.999Z",
  "SignatureVersion": "1",
  "SigningCertURL": "https://sns.us-west-2.amazonaws.com/SimpleNotificationService-randomcert.pem",
  "UnsubscribeURL": "https://sns.us-west-2.amazonaws.com/?Action=Unsubscribe&SubscriptionArn=arn:aws:sns:us-west-2:111222333444:GuardDutyAlerts:zzzz-yyyy-xxxx-wwww-vvvvuuuutttt"
}
```

After the platform parses the `Message` field, the key finding fields are:

json

```json
{
  "id": "abcd1111222233334444555566667777",
  "type": "UnauthorizedAccess:Runtime/TorClient",
  "title": "The EC2 instance i-fake123456 is communicating with a Tor entry node.",
  "description": "The process RandomProcessName from EC2 instance i-fake123456 is communicating with an IP address 203.0.113.77 on the Tor Anonymizing Proxy network marked as an entry node.",
  "severity": 4,
  "accountId": "111222333444",
  "region": "eu-central-1",
  "resource": {
    "resourceType": "KubernetesCluster",
    "instanceDetails": {
      "instanceId": "i-fake123456",
      "instanceType": "t3.large"
    }
  },
  "service": {
    "action": {
      "actionType": "NETWORK_CONNECTION",
      "networkConnectionAction": {
        "connectionDirection": "OUTBOUND",
        "remoteIpDetails": {
          "ipAddressV4": "203.0.113.77"
        }
      }
    },
    "eventFirstSeen": "2026-01-10T08:15:30.000Z",
    "eventLastSeen": "2026-01-10T08:15:30.000Z",
    "count": 2
  }
}
```

**Resulting alert:** Priority → `MEDIUM` (severity 5), Type → `ALERT`

### Prerequisites

Before configuring this integration, make sure you have:

* An active AWS account with GuardDuty enabled in at least one region
* Permissions to create and manage **SNS topics**, **EventBridge rules**, and **SNS subscriptions**
* A platform account with permission to create sources

### Setup

#### Step 1: Create an Alert Source on the Platform

1. Log in to the alert management platform.
2. Navigate to **Sources** → **Add Source**.
3. Select **AWS GuardDuty** as the provider.
4. Enter a name for this source (e.g., `GuardDuty – Production (us-east-1)`).
5. Paste the [https://api.itoc360.app/functions/v1/events?token=\<x-itoc-360>](https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>) URL.

#### Step 2: Create an SNS Topic

1. Log in to the **AWS Management Console**.
2. Open the **Simple Notification Service (SNS)** console.
3. In the left sidebar, click **Topics** → **Create topic**.
4. Configure the topic:
   * **Type**: Standard
   * **Name**: `GuardDutyAlerts` (or any descriptive name)
   * Leave all other settings as default.
5. Click **Create topic**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FEcQomB0NR6PNBdTunq51%2Fimage%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=bb264332-6a29-42bc-b72c-37e0db13aa2a" alt=""><figcaption></figcaption></figure>

— Create topic form with Standard type selected

#### Step 3: Subscribe the Platform Webhook to the SNS Topic

1. On the topic detail page, click **Create subscription**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F7mlrriBigcgTz8CXlO8E%2Fimage%20(2)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=fc0646ba-581a-42e0-bd4a-75a7714101ca" alt=""><figcaption></figcaption></figure>

— Topic detail page with "Create subscription" button

2. Configure the subscription:
   * **Topic ARN**: Auto-populated (your topic)
   * **Protocol**: `HTTPS`
   * **Endpoint**: Paste [https://api.itoc360.app/functions/v1/events?token=\<x-itoc360-token>](https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>) URL
   * **Enable raw message delivery**: **Leave unchecked** ← This is critical. The SNS envelope must be preserved so the platform can validate the subscription confirmation.
3. Click **Create subscription**.
4. The platform automatically confirms the subscription. Within a few seconds, the subscription status should change from **PendingConfirmation** to **Confirmed**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FXVrcYnaIxD4VaJAp7rlq%2Fimage%20(4)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=7ebdf7eb-1e61-4b78-9fd4-33f4cf6ca949" alt=""><figcaption></figcaption></figure>

— Subscription status showing "Confirmed"

> **Important:** If the subscription remains in PendingConfirmation, verify that your webhook endpoint is publicly reachable and that the platform's SNS confirmation handler is functioning.

#### Step 4: Enable AWS GuardDuty

If GuardDuty is not yet enabled in your account:

1. Open the **GuardDuty** console.
2. Click **Get started** → **Enable GuardDuty**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FbeaBZbpPPbMsCPARtuFr%2Fimage%20(5)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=30dfa3fc-f6a6-4b90-b166-4ac9436e7988" alt=""><figcaption></figcaption></figure>

&#x20;— GuardDuty welcome screen with "Enable GuardDuty" button

> If GuardDuty is already enabled, skip to Step 5.

#### Step 5: Create an EventBridge Rule

1. Open the **Amazon EventBridge** console.
2. In the left sidebar, click **Rules** (under Buses) → **Create rule**.
3. Configure the rule:
   * **Name**: `GuardDutyToSNS` (or any name)
   * **Description**: Forward GuardDuty findings to SNS
   * **Event bus**: `default`
   * **Rule type**: Rule with an event pattern
4. Click **Next**.
5. In the **Event pattern** section:
   * **Event source**: AWS events
   * **AWS service**: GuardDuty
   * **Event type**: GuardDuty Finding

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FTurwViC1pc0hPksnte8Y%2Fimage%20(6)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=4338ad32-97a3-4a57-a5bc-189cbbeb350d" alt=""><figcaption></figcaption></figure>

&#x20;— Event pattern form with GuardDuty Finding selected

6. The event pattern will be automatically populated:

json

```json
{
  "source": ["aws.guardduty"],
  "detail-type": ["GuardDuty Finding"]
}
```

> **Optional — Filter by severity:** To only forward medium, high, and critical findings (severity ≥ 4.0) to reduce noise, use a custom pattern:
>
> json
>
> ```json
> {
>   "source": ["aws.guardduty"],
>   "detail-type": ["GuardDuty Finding"],
>   "detail": {
>     "severity": [{ "numeric": [">=", 4.0] }]
>   }
> }
> ```

7. Click **Next**.
8. In the **Target** section:
   * **Target types**: AWS service
   * **Select a target**: SNS topic
   * **Topic**: Select the SNS topic created in Step 2

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FirHAlgvekzlA0xU8sfa6%2Fimage%20(7)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=5b5b9661-be2a-4a32-8822-d02e7c01d748" alt=""><figcaption></figcaption></figure>

— Target configuration with SNS topic selected

9. Click **Next** → Review → **Create rule**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FuzmxRndzhwxmOKoyvd3v%2Fimage%20(9)%20(1)%20(1).png?alt=media&amp;token=85c6d0a9-adb3-49eb-9b48-66622580bb5e" alt=""><figcaption></figcaption></figure>

&#x20;— Rule successfully created and showing as Enabled

#### Step 6: Test the Integration

1. Open the **GuardDuty** console.
2. In the left sidebar, click **Settings**.
3. Under **Sample findings**, click **Generate sample findings**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FW4n2BSYjIr5oGYNY1iis%2Fimage%20(10)%20(1)%20(1).png?alt=media&amp;token=1ff3f419-987d-47b9-b777-24209daa2cc6" alt=""><figcaption></figcaption></figure>

— GuardDuty Settings page with "Generate sample findings" button

4. Click **Findings** in the left sidebar.
5. You should see multiple sample findings (prefixed with `[SAMPLE]`) in the findings list.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fjj2Z3qlx50Xokf45PkdU%2Fimage%20(12)%20(1)%20(1).png?alt=media&amp;token=f537615e-ce5a-4d42-8ef7-7db43f9656e4" alt=""><figcaption></figcaption></figure>

— GuardDuty findings list with \[SAMPLE] findings visible<br>

6. Within a few minutes, the findings should appear as alerts on the platform.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FzppsALNIMrMnHRkhUTXj%2Fimage%20(11)%20(1)%20(1).png?alt=media&amp;token=806f4647-192a-41fc-b2f3-ccb5bb1b8cc0" alt=""><figcaption></figcaption></figure>

— Platform alerts list showing GuardDuty findings as HIGH/CRITICAL alerts

> Sample findings cover all GuardDuty finding types across EC2, IAM, S3, EKS, RDS, and more. They use placeholder values and are marked with `"sample": true` in the finding JSON.a

### Finding Types Reference

GuardDuty organizes findings into categories based on the affected AWS resource and threat type. Common finding types you may receive:

| Category                | Example Finding Type                                          | Typical Severity |
| ----------------------- | ------------------------------------------------------------- | ---------------- |
| EC2 Unauthorized Access | `UnauthorizedAccess:EC2/SSHBruteForce`                        | Medium–High      |
| EC2 Backdoor            | `Backdoor:EC2/C&CActivity.B`                                  | High             |
| IAM Reconnaissance      | `Recon:IAMUser/MaliciousIPCaller`                             | Medium           |
| IAM Unauthorized Access | `UnauthorizedAccess:IAMUser/ConsoleLoginSuccess.B`            | Medium–High      |
| S3 Data Exfiltration    | `Exfiltration:S3/ObjectRead.Unusual`                          | High             |
| S3 Policy Modification  | `Policy:S3/BucketPublicAccessGranted`                         | High             |
| EC2 Crypto Mining       | `CryptoCurrency:EC2/BitcoinTool.B`                            | High             |
| RDS Brute Force         | `CredentialAccess:RDS/AnomalousBehavior.SuccessfulBruteForce` | High–Critical    |

The full list of GuardDuty finding types is available in the [AWS GuardDuty documentation](https://docs.aws.amazon.com/guardduty/latest/ug/guardduty_finding-types-active.html).

***

### Multi-Region Setup

GuardDuty operates at the region level. If you have GuardDuty enabled in multiple AWS regions, you must repeat Steps 2–5 for each region, or use **GuardDuty multi-account / delegated administrator** setup to aggregate findings to a central account.

For multi-region setups, it is recommended to:

1. Create one SNS topic per region (e.g., `GuardDutyAlerts-us-east-1`, `GuardDutyAlerts-eu-west-1`).
2. Create separate platform sources per region for clear visibility.
3. Name each source with the region (e.g., `GuardDuty – Production (eu-west-1)`).

***

### Alert Lifecycle

| Platform Event     | Trigger                                              |
| ------------------ | ---------------------------------------------------- |
| Alert OPENED       | GuardDuty finding delivered via SNS                  |
| Alert priority set | Based on `detail.severity` numeric score             |
| Alert CLOSED       | **Manual** — GuardDuty does not send recovery events |

> After resolving a security finding in AWS (archiving it in GuardDuty), manually close the corresponding alert in the platform to keep your incident queue clean.

***

### Troubleshooting

| Problem                                   | Likely Cause                                                     | Solution                                                                      |
| ----------------------------------------- | ---------------------------------------------------------------- | ----------------------------------------------------------------------------- |
| Subscription stays in PendingConfirmation | Platform endpoint not reachable or SNS confirmation not handled  | Verify the webhook URL is correct and publicly accessible                     |
| No alerts arriving after rule creation    | EventBridge rule not matching, or SNS subscription not confirmed | Check CloudWatch metrics for the EventBridge rule; verify subscription status |
| Alerts arrive but priority is always LOW  | Severity below 4.0 or parsing error in `Message` field           | Confirm `Enable raw message delivery` is unchecked on the SNS subscription    |
| Duplicate alerts                          | EventBridge rule triggered multiple times or SNS retry           | Check EventBridge rule targets — there should be exactly one SNS target       |
| Sample findings not appearing on platform | Rule or subscription created after sample generation             | Re-generate sample findings after confirming the full integration is set up   |
| Finding type not recognized               | New GuardDuty finding type added by AWS                          | All findings are accepted; only severity affects priority mapping             |


# Google Security Command Center(SCC) Integration

## Google Security Command Center Integration

Google Cloud Security Command Center (SCC) is Google Cloud's centralized security and risk management platform. It provides threat detection, vulnerability assessment, and compliance monitoring across your Google Cloud environment.

Since SCC does not support direct outbound webhook calls, notifications are routed through Google Cloud's Pub/Sub messaging service. A Cloud Function acts as the middleware: it receives the Pub/Sub message, decodes the Base64-encoded payload, and forwards the raw SCC JSON directly to the platform's webhook endpoint. The platform then processes the payload using JSONPath-based priority mapping to create and manage alerts.

**Integration Flow**

```
SCC Finding → Pub/Sub Topic → Cloud Function → HTTP POST → Platform Webhook
```

1. Google SCC detects a security finding (e.g., a misconfiguration or active threat) in your cloud environment.
2. The SCC Continuous Export publishes the finding to a Pub/Sub topic.
3. The Cloud Function is triggered by the Pub/Sub topic, decodes the Base64-encoded message, and forwards the raw JSON payload to the platform webhook without any transformation.
4. The platform receives the payload, evaluates the `finding.severity` field via JSONPath, maps it to the internal priority scale, and creates or resolves the alert accordingly.

### Provider Configuration

The platform uses JSONPath-based priority mapping to extract the severity value directly from the raw SCC payload.

**Priority Mapping Config:**

```json
{
  "priority": {
    "field": "$.finding.severity",
    "options": [
      { "value": "CRITICAL", "label": "Critical" },
      { "value": "HIGH", "label": "High" },
      { "value": "MEDIUM", "label": "Medium" },
      { "value": "LOW", "label": "Low" }
    ],
    "mapping": {
      "CRITICAL": "CRITICAL",
      "HIGH": "HIGH",
      "MEDIUM": "MEDIUM",
      "LOW": "LOW"
    }
  }
}
```

**Status (Event Type) Mapping:**

| SCC Finding State | Platform Event Type | Platform Status |
| ----------------- | ------------------- | --------------- |
| `ACTIVE`          | ALERT               | PROBLEM         |
| `INACTIVE`        | RESOLVE             | RECOVERY        |

**Fingerprint (Correlation) Field:** `$.finding.name`

SCC assigns a unique `finding.name` to each finding. The platform uses this field to correlate ACTIVE and INACTIVE events — both payloads must contain the identical `finding.name` value for recovery to work correctly.

### Webhook Payload Schema

| Field                         | Type   | Description                                                |
| ----------------------------- | ------ | ---------------------------------------------------------- |
| `finding.name`                | string | Full resource name of the finding — correlation key        |
| `finding.category`            | string | Finding category (e.g., `OPEN_FIREWALL`, `PUBLIC_BUCKET`)  |
| `finding.severity`            | string | Severity level: `CRITICAL`, `HIGH`, `MEDIUM`, `LOW`        |
| `finding.state`               | string | Finding state: `ACTIVE`, `INACTIVE`                        |
| `finding.resourceName`        | string | Full resource name of the affected GCP resource            |
| `finding.createTime`          | string | ISO 8601 timestamp when the finding was created            |
| `finding.eventTime`           | string | ISO 8601 timestamp of the event that triggered the finding |
| `finding.sourceProperties`    | object | Additional context provided by the detection source        |
| `resource.name`               | string | Short name of the affected resource                        |
| `resource.type`               | string | GCP resource type (e.g., `google.compute.Instance`)        |
| `resource.projectDisplayName` | string | Human-readable project name                                |

### Alert Payload Examples

#### Raised (ACTIVE)

This payload is delivered when SCC detects a new security finding. The `finding.state` field is `ACTIVE`.

— ACTIVE payload received at webhook.site

```json
{
  "finding": {
    "name": "projects/YOUR_PROJECT_ID/sources/-/findings/TEST001",
    "category": "TEST_OPEN_FIREWALL",
    "severity": "HIGH",
    "state": "ACTIVE",
    "resourceName": "//compute.googleapis.com/projects/YOUR_PROJECT_ID/global/firewalls/test-firewall",
    "createTime": "2026-02-25T10:00:00Z",
    "eventTime": "2026-02-25T10:00:00Z"
  },
  "resource": {
    "name": "test-firewall",
    "type": "google.compute.Firewall",
    "projectName": "projects/YOUR_PROJECT_ID",
    "projectDisplayName": "YOUR_PROJECT_ID"
  }
}
```

#### Cleared (INACTIVE)

This payload is delivered when a finding is resolved. The `finding.state` field changes to `INACTIVE`.

— INACTIVE payload received at webhook.site

```json
{
  "finding": {
    "name": "projects/YOUR_PROJECT_ID/sources/-/findings/TEST001",
    "category": "TEST_OPEN_FIREWALL",
    "severity": "HIGH",
    "state": "INACTIVE",
    "resourceName": "//compute.googleapis.com/projects/YOUR_PROJECT_ID/global/firewalls/test-firewall",
    "createTime": "2026-02-25T10:00:00Z",
    "eventTime": "2026-02-25T10:45:00Z"
  },
  "resource": {
    "name": "test-firewall",
    "type": "google.compute.Firewall",
    "projectName": "projects/YOUR_PROJECT_ID",
    "projectDisplayName": "YOUR_PROJECT_ID"
  }
}
```

> **Important:** The `finding.name` value must be **identical** in both ACTIVE and INACTIVE payloads. The platform uses this field to match the recovery event to the original alert.

### Installation & Configuration

#### Step 1: Create an Alert Source in the Platform

1. Log in to the alert management platform.
2. Navigate to **Integrations → Add Integration**.
3. Select **Google Security Command Center** as the provider.
4. Name the integration (e.g., `Production GCP Security`).
5. Paste [https://api.itoc360.app/functions/v1/events?token=\<x-itoc360-token>](https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>) URL.

#### Step 2: Create a Pub/Sub Topic

1. In Google Cloud Console, search for **Pub/Sub** in the search bar and navigate to the service.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FukgTVh6ABHHhltmnrVTW%2Fimage%20(36).png?alt=media&amp;token=fba49421-1a97-4283-b9a9-252b2679cac1" alt=""><figcaption></figcaption></figure>

— Pub/Sub Topics page&#x20;

2. Click **+ Create Topic**.
3. Set the **Topic ID** to `scc-alerts-topic`.
4. Leave **"Add a default subscription"** checked.
5. Click **Create**.

The topic detail page will confirm creation. The full topic path is shown as `projects/YOUR_PROJECT_ID/topics/scc-alerts-topic` and the default subscription `scc-alerts-topic-sub` will appear under the Subscriptions tab.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FXVMhaEO8J8EGm8ewKP3W%2Fimage%20(37).png?alt=media&amp;token=6fe61544-9235-4e6f-8917-cc051d8f5c67" alt=""><figcaption></figcaption></figure>

— scc-alerts-topic created with default subscription visible&#x20;

#### Step 3: Create a Continuous Export in SCC

SCC Continuous Export sends all findings matching your filter to the Pub/Sub topic automatically.

> **Organization Requirement:** This step requires Organization-level access in Google Cloud. If your account does not have an organization (e.g., personal or trial projects), skip to the **Testing** section and use the manual Pub/Sub publish method to validate the integration end-to-end.

1. Navigate to **Security Command Center** in Google Cloud Console.
2. Go to **Settings → Continuous Exports** from the left menu.
3. Click **+ Create Export** and configure the following:

   * **Name:** `scc-to-webhook`

   * **Project:** Select the project where your Pub/Sub topic was created

   * **Pub/Sub topic:** `scc-alerts-topic`

   * **Filter:** Leave empty to receive all findings

   > **Important:** If you set `state="ACTIVE"` as a filter, only new findings will be published to Pub/Sub. INACTIVE (recovery) events will not be sent, and the platform will never receive recovery notifications. Leave the filter empty to receive both ACTIVE and INACTIVE events.
4. Click **Save**.

#### Step 4: Deploy the Cloud Function

The Cloud Function receives Pub/Sub messages, decodes the Base64 payload, and forwards the raw SCC JSON to the platform webhook.

**4.1 — Navigate to Cloud Functions**

Search for **Cloud Functions** in the Google Cloud Console search bar and click on **Cloud Run functions** in the results.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FnjePDK6Svu6muw5wswQx%2Fimage%20(38).png?alt=media&amp;token=42c44b27-9827-41c5-bb47-ae06aecc0c02" alt=""><figcaption></figcaption></figure>

— Cloud Functions search result \
\
**4.2 — Create the Service**

Click **+ Create Function**. On the Create service page:

* Select **"Use an inline editor to create a function"**
* **Service name:** `scc-webhook-forwarder`
* **Region:** `europe-west1` (or the same region as your Pub/Sub topic)
* **Runtime:** Node.js 24

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F5nPL1ZD5oLyYcqIcPXmB%2Fimage%20(40).png?alt=media&amp;token=b7369862-0323-4f93-8c86-0722884c6b99" alt=""><figcaption></figcaption></figure>

— Create service form with Function option selected \
\
**4.3 — Configure the Pub/Sub Trigger**

Click **+ Add trigger** and select **Cloud Pub/Sub** from the dropdown. The Eventarc trigger panel will open.

If prompted to **Enable required APIs**, click **Enable** and wait for the Eventarc API to activate.

In the Eventarc trigger panel:

* **Event provider:** Cloud Pub/Sub (already set)
* **Event type:** `google.cloud.pubsub.topic.v1.messagePublished` (already set)
* **Select a Cloud Pub/Sub topic:** Choose `scc-alerts-topic`
* Click **Grant** on the IAM role warning to allow Pub/Sub to create identity tokens

Click **Save trigger**.

The trigger configuration will now show the connected topic and service account.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fm2q2Y3DLMsMNzlRbRv46%2Fimage%20(41).png?alt=media&amp;token=59bb4391-3c74-429a-bd9f-66ad29ba20c8" alt=""><figcaption></figcaption></figure>

— Eventarc trigger configured with scc-alerts-topic \
\
The full service configuration page with trigger, runtime, and authentication settings will be visible before deployment.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FmT4KMtGU0zMWm5DC5HXi%2Fimage%20(44).png?alt=media&amp;token=e97a8ddd-9dcf-40ce-b0a2-9abb9ed96da8" alt=""><figcaption></figcaption></figure>

— Complete service configuration ready for deployment \
\
Click **Create**.

**4.4 — Add the Function Code**

After the service is created, the Source tab will open with the inline code editor.

* Set the **Function entry point** to `forwardSccToWebhook`
* Replace the contents of `index.js` with the following code:

```javascript
const https = require('https');

exports.forwardSccToWebhook = async (req, res) => {
  try {
    const body = req.body;

    // Cloud Run Eventarc: Pub/Sub message arrives in body.message.data
    const messageData = body?.message?.data || '';

    const rawSccData = messageData
      ? Buffer.from(messageData, 'base64').toString('utf8')
      : '{}';

    console.log('SCC finding received:', rawSccData.substring(0, 200));

    // Replace with your platform webhook URL from Step 1
    const webhookUrl = 'https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>';
    const url = new URL(webhookUrl);

    const options = {
      hostname: url.hostname,
      path: url.pathname + url.search,
      method: 'POST',
      headers: {
        'Content-Type': 'application/json',
        'Content-Length': Buffer.byteLength(rawSccData)
      }
    };

    await new Promise((resolve, reject) => {
      const request = https.request(options, (response) => {
        console.log(`Webhook response: ${response.statusCode}`);
        resolve();
      });
      request.on('error', reject);
      request.write(rawSccData);
      request.end();
    });

    res.status(200).send('OK');
  } catch (e) {
    console.error(`Error: ${e.message}`);
    res.status(500).send(e.message);
  }
};
```

Replace `https://YOUR_PLATFORM_WEBHOOK_URL_HERE` with the Webhook URL copied from Step 1.

Click **Save and redeploy**. Wait for all deployment steps to show green checkmarks.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F53LJb7vyi4uBUG49Kwmm%2Fimage%20(45).png?alt=media&amp;token=42f65582-3f51-4f41-8ac2-0de22acabb06" alt=""><figcaption></figcaption></figure>

— Cloud Function deployed successfully with green tick, entry point forwardSccToWebhook visible&#x20;

### Testing

#### Option A — Manual Pub/Sub Publish (Recommended)

This method bypasses SCC entirely and tests the Cloud Function → Webhook path directly. It works regardless of whether you have Organization-level access.

Open **Cloud Shell** from the Google Cloud Console toolbar and run the following commands:

**ACTIVE — Create an alert:**

```bash
gcloud pubsub topics publish scc-alerts-topic \
  --message='{"finding":{"name":"projects/YOUR_PROJECT_ID/sources/-/findings/TEST001","category":"TEST_OPEN_FIREWALL","severity":"HIGH","state":"ACTIVE","resourceName":"//compute.googleapis.com/projects/YOUR_PROJECT_ID/global/firewalls/test-firewall","createTime":"2026-02-25T10:00:00Z","eventTime":"2026-02-25T10:00:00Z"},"resource":{"name":"test-firewall","type":"google.compute.Firewall","projectName":"projects/YOUR_PROJECT_ID","projectDisplayName":"YOUR_PROJECT_ID"}}'

```

**INACTIVE — Send recovery:**

```bash
gcloud pubsub topics publish scc-alerts-topic \
  --message='{"finding":{"name":"projects/YOUR_PROJECT_ID/sources/-/findings/TEST001","category":"TEST_OPEN_FIREWALL","severity":"HIGH","state":"INACTIVE","resourceName":"//compute.googleapis.com/projects/YOUR_PROJECT_ID/global/firewalls/test-firewall","createTime":"2026-02-25T10:00:00Z","eventTime":"2026-02-25T10:45:00Z"},"resource":{"name":"test-firewall","type":"google.compute.Firewall","projectName":"projects/YOUR_PROJECT_ID","projectDisplayName":"YOUR_PROJECT_ID"}}'

```

Each command returns a `messageIds` array confirming the message was published to Pub/Sub.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FvYd5V9CtO6o2ajr3PgjZ%2Fimage%20(46).png?alt=media&amp;token=30dd653a-f0a0-464e-9558-c8bcab2bdc38" alt=""><figcaption></figcaption></figure>

— Cloud Shell with INACTIVE test command and messageIds response&#x20;

#### Option B — Verify via Cloud Function Logs

Navigate to **Cloud Run → scc-webhook-forwarder → Observability → Logs**.

Confirm the following log lines appear after each test message:

* `SCC finding received: {"finding":{"name":"projects/testproject-123456...`
* `Webhook response: 200`

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FZTut7djsomnlozbFzPzl%2Fimage%20(47).png?alt=media&amp;token=204e1142-0e5e-44da-ace0-f21620c0e739" alt=""><figcaption></figcaption></figure>

— Cloud Function Logs showing SCC finding received and Webhook response: 200&#x20;

#### Verify Alert Trigger (ACTIVE)

After the ACTIVE message is published, the platform webhook receives the full SCC JSON payload.\
\
Verify in the platform:

* A new alert was created with **Status: PROBLEM**
* The alert title reflects `finding.category` (`TEST_OPEN_FIREWALL`)
* The severity mapped correctly: `HIGH` → High

#### Verify Recovery (INACTIVE)

After the INACTIVE message is published, the platform receives the recovery payload.\
\
Verify in the platform:

* The existing alert transitioned to **Status: RECOVERY**
* The `finding.name` matched the original ACTIVE alert for correct correlation

### Verification Checklist

* An **ACTIVE** finding payload was received by the platform (status: PROBLEM).
* The payload contains the correct `finding.category`, `finding.severity`, and `resource.projectDisplayName`.
* An **INACTIVE** finding payload was received after resolution (status: RECOVERY).
* The `finding.name` field is identical in both ACTIVE and INACTIVE payloads — correlation is working.
* Cloud Function logs show no errors and `Webhook response: 200` for each delivery.

### Troubleshooting

| Issue                                | Possible Cause                            | Resolution                                                                                           |
| ------------------------------------ | ----------------------------------------- | ---------------------------------------------------------------------------------------------------- |
| SCC menu not accessible              | No Organization-level access              | SCC requires Organization access. Use Option A (manual Pub/Sub publish) to test the integration.     |
| No webhook requests received         | Cloud Function error                      | Check Cloud Function **Logs** tab for error details.                                                 |
| Recovery alerts not received         | SCC export filter set to `state="ACTIVE"` | Remove the filter in Step 3. With this filter, INACTIVE events are never published to Pub/Sub.       |
| Payload arrives empty `{}`           | Cloud Run 2nd gen message format mismatch | Ensure the code reads from `body.message.data`, not `event.data`. Use the code provided in Step 4.4. |
| Priority always falls back to MEDIUM | JSONPath misconfiguration                 | Verify the provider `priority.field` is exactly `$.finding.severity`.                                |
| Alert correlation not working        | `finding.name` differs between payloads   | The `finding.name` must be identical in both ACTIVE and INACTIVE messages.                           |
| Authentication error (401/403)       | Incorrect webhook URL or token            | Verify the `webhookUrl` in `index.js` matches the value copied from Step 1.                          |
| Cloud Function deploy error          | Wrong entry point                         | Confirm the entry point field is set to `forwardSccToWebhook`.                                       |


# DevOps and CI/CD

This category covers source control, pipeline, and infrastructure-as-code platforms. These tools send alerts to ITOC360 when builds fail, deployments break, or critical pipeline events occur — ensuring the responsible engineer is notified before an issue reaches production.

***

### Integrations in this category

| Integration         | What it monitors                                                  | Alert delivery |
| ------------------- | ----------------------------------------------------------------- | -------------- |
| **ArgoCD**          | GitOps deployment health, sync failures, application degradations | Webhook        |
| **Azure DevOps**    | Build and release pipeline failures, work item events             | Webhook        |
| **GitHub**          | Workflow run failures, security advisories, repository events     | Webhook        |
| **GitLab**          | CI/CD pipeline failures, deployment events, security findings     | Webhook        |
| **Jenkins**         | Build job failures, pipeline stage errors                         | Webhook        |
| **Terraform Cloud** | Run failures, plan errors, workspace events                       | Webhook        |

***

### How it works

CI/CD and DevOps tools emit events at every stage of the software delivery lifecycle. When a pipeline fails, a deployment is rejected, or a security advisory is published, the tool sends an event payload to your ITOC360 Source webhook URL. ITOC360 parses the event, matches it against your escalation policies, and notifies the on-call engineer responsible for that pipeline or repository.

{% hint style="info" %}
ITOC360 generates a unique webhook URL per Source. Go to **Management > Sources**, create a Source, and paste the webhook URL into your tool's webhook or notification settings.
{% endhint %}

***

### Get started


# ArgoCD Integration

[Argo CD ](https://argoproj.github.io/cd/)is a declarative GitOps continuous delivery tool for Kubernetes. It watches your Git repositories and automatically syncs the desired state into your cluster. Through its Notifications Engine, Argo CD can push webhook events to external systems like itoc360 whenever an application's sync or health status changes — making it straightforward to wire on-call alerting directly into your deployment pipeline.

### Prerequisites

* Docker Desktop installed and running
* `minikube` and `kubectl` available on your machine
* An ITOC360 source token for Argo CD

### Setting Up a Local Kubernetes Cluster

Since Argo CD runs inside Kubernetes, you need a local cluster first. Install minikube via Homebrew if you haven't already:

```bash
brew install minikube
```

Then start the cluster using Docker as the driver:

```bash
minikube start --driver=docker
```

Minikube will pull the necessary images and initialize a single-node cluster. The whole process takes a couple of minutes depending on your connection speed.

### Installing Argo CD

Create a dedicated namespace and apply the official Argo CD manifest:

```bash
kubectl create namespace argocd
kubectl apply -n argocd -f https://raw.githubusercontent.com/argoproj/argo-cd/stable/manifests/install.yaml
```

This installs all the Argo CD components — server, application controller, notifications controller, Redis, and the supporting RBAC configuration.

Wait for the server pod to become ready before proceeding:

```bash
kubectl wait --for=condition=ready pod -l app.kubernetes.io/name=argocd-server -n argocd --timeout=120s
```

Once you see `condition met`, open a port-forward so you can reach the UI locally:

```bash
kubectl port-forward svc/argocd-server -n argocd 8081:443
```

Retrieve the initial admin password:

```bash
kubectl -n argocd get secret argocd-initial-admin-secret -o jsonpath="{.data.password}" | base64 -d
```

Open `https://localhost:8081` in your browser (accept the self-signed certificate warning), log in with username `admin` and the password you just retrieved.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FRGuPI6t84wLdLYp2FNOI%2FEkran%20Resmi%202026-03-25%2013.14.31.png?alt=media&amp;token=727d24f3-1990-42e2-afb1-fae838fc93d0" alt=""><figcaption></figcaption></figure>

### Creating a Test Application

Argo CD's notification system only fires when an Application resource exists. Create one that tracks a public example repository:

```bash
kubectl apply -n argocd -f - <<EOF
apiVersion: argoproj.io/v1alpha1
kind: Application
metadata:
  name: itoc360-test
  namespace: argocd
spec:
  project: default
  source:
    repoURL: https://github.com/<your-repo-url>
    targetRevision: HEAD
    path: guestbook
  destination:
    server: https://kubernetes.default.svc
    namespace: default
  syncPolicy:
    automated:
      prune: true
      selfHeal: true
EOF
```

After a few seconds the application card appears in the Argo CD dashboard.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FVLulRDbRtZ4j6B3TxgTS%2Fimage%20(96).png?alt=media&amp;token=07958647-12af-4090-8161-2666a7669a18" alt=""><figcaption></figcaption></figure>

### Configuring the Notification Webhook

Argo CD sends notifications through the `argocd-notifications-cm` ConfigMap. Apply the following to configure the ITOC360 webhook, the message template, and the trigger rules:

```bash
kubectl apply -f - <<'EOF'
apiVersion: v1
kind: ConfigMap
metadata:
  name: argocd-notifications-cm
  namespace: argocd
data:
  service.webhook.itoc360: |
    url: https://api.itoc360.app/functions/v1/events?token=<x-itoc360-token>
    headers:
    - name: Content-Type
      value: application/json
  template.app-sync-itoc360: |
    webhook:
      itoc360:
        method: POST
        body: |
          {
            "app_name": "{{.app.metadata.name}}",
            "sync_status": "{{.app.status.sync.status}}",
            "health_status": "{{.app.status.health.status}}",
            "namespace": "{{.app.spec.destination.namespace}}",
            "server": "{{.app.spec.destination.server}}"
          }
  trigger.on-sync-itoc360: |
    - when: app.status.sync.status == 'OutOfSync' || app.status.health.status == 'Degraded'
      send: [app-sync-itoc360]
    - when: app.status.sync.status == 'Synced' && app.status.health.status == 'Healthy'
      send: [app-sync-itoc360]
EOF
```

Then subscribe the test application to the trigger:

```bash
kubectl annotate application itoc360-test -n argocd \
  notifications.argoproj.io/subscribe.on-sync-itoc360.itoc360=""
```

### How It Works

Whenever the `itoc360-test` application changes state, the notifications controller fires a POST request to your ITOC360 endpoint with a JSON body containing the application name, sync status, health status, destination namespace, and cluster server URL.

itoc360 maps these fields as follows:

* `health_status: Degraded` or `sync_status: OutOfSync` → **ALERT**, HIGH priority
* `health_status: Missing` → **ALERT**, HIGH priority
* `health_status: Progressing` → **ALERT**, MEDIUM priority
* `sync_status: Synced` and `health_status: Healthy` → **RESOLVE**

Alerts are correlated by application name and namespace, so a degraded deployment and its eventual recovery are treated as a single incident lifecycle.

### Verifying the Integration

Trigger a manual sync to confirm the webhook fires end-to-end:

```bash
kubectl patch application itoc360-test -n argocd --type merge \
  -p '{"operation":{"initiatedBy":{"username":"admin"},"sync":{"revision":"HEAD"}}}'
```

You should see the application transition through its sync phases in the Argo CD UI, and a corresponding alert appear in your ITOC360 dashboard within a few seconds.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fi5WhyN6DKJdV0rXwutgK%2Fimage%20(97).png?alt=media&amp;token=cb73010c-7883-447c-abaf-97b6f2a8ad97" alt=""><figcaption></figcaption></figure>


# Azure DevOps Integration

Azure DevOps has a feature called Service Hooks that can fire HTTP requests whenever something happens in your project — a work item gets created, a build finishes, a PR is merged, whatever you care about. This page covers wiring that up to the on-call platform.

### 1. Create an organization and project

Go to [dev.azure.com](https://dev.azure.com/) and sign in. If you've never used Azure DevOps before, you'll hit a blank slate asking you to create an organization:

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FJnvM8zkswRgqtGJRsPdG%2Fimage%20(72).png?alt=media&amp;token=8395a73b-5768-44ec-8afe-59e5256394be" alt=""><figcaption></figcaption></figure>

Click **Create new organization**, pick a name and a hosting region, and you'll land straight on the project creation form:

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FJWlLwrE4WlJH0BqVpMKh%2Fimage%20(73).png?alt=media&amp;token=8186a880-ba01-4ac2-bd8e-aa9f8461eae0" alt=""><figcaption></figcaption></figure>

Name the project whatever you like — something like `test-oncall` works fine. Keep visibility as **Private** and hit **Create project**. You'll end up here once it's ready:

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FECRcK0rRUgsDmdpmViX3%2Fimage%20(74).png?alt=media&amp;token=4767f9b3-5281-4091-aeec-4c9b1574dfe1" alt=""><figcaption></figcaption></figure>

Project Settings > Service Hooks

### 2. Open Service Hooks

Click **Project Settings** in the bottom-left corner of the screen. Under the General section on the left panel you'll find **Service hooks**. Click it.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FO1CwIEFuvNiAWMCBBLKA%2Fimage%20(75).png?alt=media&amp;token=16775cc2-0b02-4605-a539-7fe0190a912f" alt=""><figcaption></figcaption></figure>

The page is empty to start. Hit **+ Create subscription**.

***

### 3. Pick Web Hooks

A modal pops up with a list of services you can integrate with. Scroll down and select **Web Hooks** — that's the plain HTTP option that works with any endpoint, no special setup needed on either side.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fd4Qw6JNp1mLvbkrTjQBO%2Fimage%20(76).png?alt=media&amp;token=29876463-bfdc-42b3-b4d7-e698dbdb739f" alt=""><figcaption></figcaption></figure>

Click **Next**.

***

### 4. Set the trigger

Here you choose what event fires the webhook. **Work item created** is a solid starting point — every time someone opens a new bug, task, or incident, the platform gets notified right away.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FyMWOk2lurS3MkjJYh3Uv%2Fimage%20(77).png?alt=media&amp;token=caa26e73-0271-488a-b3bb-632b60ab3e39" alt=""><figcaption></figcaption></figure>

Leave both filters (`Area path` and `Work item type`) at `[Any]` unless you want to narrow it down to a specific area or item type. Click **Next**.

***

### 5. Enter the webhook URL

Paste [https://api.itoc360.app/functions/v1/events?token=\<x-itoc360-token>](https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>)  into the **URL** field. Skip the authentication fields — auth is handled via the token baked into the URL. Make sure all three dropdown values (`Resource details to send`, `Messages to send`, `Detailed messages to send`) stay on **All**, otherwise you'll get a trimmed-down payload.

Before saving, click **Test**.

***

### 6. Confirm the test result

If everything is set up correctly, you'll see this:

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F4vvae0Im5bmNQl87zIxS%2Fimage%20(78).png?alt=media&amp;token=b07747f7-19b8-46fb-a909-0a0b945725b5" alt=""><figcaption></figcaption></figure>

Close the test dialog and hit **Finish** to save the subscription. That's it — the hook is live.

***

### Field mappings

Azure DevOps doesn't give you a template editor for the payload — every event type sends a fixed JSON structure. The platform pulls the following fields out of it:

| DevOps Field                                        | Platform Field                                                |
| --------------------------------------------------- | ------------------------------------------------------------- |
| `resource.id`                                       | Fingerprint — ties together all events for the same work item |
| `resource.fields["System.State"]`                   | `Resolved` or `Closed` → RESOLVE, anything else → ALERT       |
| `resource.fields["Microsoft.VSTS.Common.Severity"]` | Priority                                                      |
| `resource.fields["System.Title"]`                   | Alert title                                                   |
| `resource.fields["System.WorkItemType"]`            | Alert context                                                 |

Severity to priority mapping:

| DevOps Severity | Platform Priority |
| --------------- | ----------------- |
| 1 - Critical    | CRITICAL          |
| 2 - High        | HIGH              |
| 3 - Medium      | MEDIUM            |
| 4 - Low         | LOW               |


# GitHub Integration

[GitHub](https://github.com/) is a code hosting and collaboration platform that supports native webhook delivery for repository events. When something happens in your repository — a push, a failed workflow, a new vulnerability alert — GitHub can send a real-time HTTP POST request to any endpoint you configure.

This integration connects GitHub to ITOC360 so that repository events automatically create or resolve incidents in your on-call workflow. No middleware or third-party service required; the webhook goes directly from GitHub to ITOC360.

### How It Works

GitHub sends a webhook payload to itoc360 every time a subscribed event occurs in your repository. The `X-GitHub-Event` header in each request identifies the event type — ITOC360 uses this to determine whether to open or resolve an incident. For events like workflow failures or vulnerability alerts, a new incident is created. When the same workflow succeeds on a subsequent run, or the vulnerability is dismissed, ITOC360 automatically resolves it.

### Prerequisites

* A GitHub repository where you have admin access
* Your ITOC360 webhook URL, generated when you create the integration

### In ITOC360

Go to **Integrations**, click **Add Integration**, and select **GitHub** from the list. Copy the webhook URL that appears — you'll paste it into GitHub in the next step.

### In GitHub

#### Step 1 — Open Webhooks Settings

Navigate to your repository on GitHub. Click **Settings** in the top navigation bar, then find **Webhooks** in the left sidebar under **Code and automation**.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fs4Nvf8SqRtRWY7XVdipt%2Fimage%20(4)%20(1)%20(1).png?alt=media&amp;token=9e2a924d-73c3-49f0-a726-8c976a6fdbee" alt=""><figcaption></figcaption></figure>

Click **Add webhook** in the top right corner.

***

#### Step 2 — Configure the Webhook

Fill in the form as follows:

* **Payload URL** — [https://api.itoc360.app/functions/v1/events?token=\<x-itoc360-token>](https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>)
* **Content type** — select `application/json`
* **Secret** — leave this empty
* **SSL verification** — leave **Enable SSL verification** selected
* **Which events would you like to trigger this webhook?** — select **Send me everything**
* Make sure **Active** is checked at the bottom

\
Click **Add webhook** to save. GitHub will immediately send a ping request to confirm the connection is working.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FziJpQsCR0Tyde4nqDDso%2FEkran%20Resmi%202026-03-27%2013.22.51.png?alt=media&amp;token=a91d4a0d-5c15-4ae2-a03d-65093327c5d8" alt=""><figcaption></figcaption></figure>

### Supported Events

ITOC360 processes the following GitHub event types:

| Event                            | Trigger                        | Resolve                          |
| -------------------------------- | ------------------------------ | -------------------------------- |
| `workflow_run`                   | Workflow fails or times out    | Workflow succeeds                |
| `deployment_status`              | Deployment errors or fails     | Deployment succeeds              |
| `check_run`                      | Check fails or requires action | Check passes                     |
| `pull_request`                   | PR opened or updated           | PR closed                        |
| `issues`                         | Issue opened                   | Issue closed                     |
| `repository_vulnerability_alert` | Vulnerability detected         | Vulnerability dismissed or fixed |
| `push`                           | Commit pushed to any branch    | —                                |
| `release`                        | Release published              | —                                |

All other event types are accepted and logged as alerts with a default priority.

### Notes

* GitHub identifies event types via the `X-GitHub-Event` request header, not the payload body. ITOC360 reads this header automatically — no additional configuration needed.
* If you want to limit noise, you can go back to the webhook settings and switch from **Send me everything** to **Let me select individual events**, then choose only the events relevant to your workflow.
* The webhook secret field is optional. If you set one in GitHub, ITOC360 will ignore it (signature verification is not enforced at the receiver).


# GitLab Integration

[GitLab](https://about.gitlab.com/) is a complete DevOps platform that covers source code management, CI/CD pipelines, and project collaboration in a single interface. Through its built-in webhook system, GitLab can push pipeline status events to external systems like itoc360 the moment something changes — no polling, no delay.

### Prerequisites

* A GitLab account with at least one project
* A `.gitlab-ci.yml` file in your repository (required for pipeline events to fire)
* An ITOC360 source token for GitLab

### Navigating to Webhook Settings

Open your GitLab project. In the left sidebar, click **Settings** to expand the section, then select **Webhooks** from the list that appears.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FJXZl49nNyUKsMxRyMCpf%2Fimage%20(4)%20(1)%20(1)%20(1).png?alt=media&amp;token=25bb984e-137d-436a-8066-793702838adc" alt=""><figcaption></figcaption></figure>

The Webhooks page will show any existing hooks or an empty state if none have been configured yet.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F5VOaPmBY7m4Mz27jcKyc%2Fimage%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=83004515-edfd-4a26-be87-a824b7740e47" alt=""><figcaption></figcaption></figure>

### Adding the Webhook

Click **Add new webhook** to open the configuration form. Fill in the fields as follows:

* **Name:** Give it a recognizable name, such as `ITOC360`
* **URL:** Your ITOC360 webhook URL with the source token as a query parameter:

```
https://api.itoc360.app/functions/v1/events?token=<x-itoc360-token>
```

* **Secret token:** Leave empty — authentication is handled via the token in the URL
* **Trigger:** Scroll down and check **Pipeline events** only

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fv9awGWnTgxnDgrRjZ8Yk%2FEkran%20Resmi%202026-03-24%2018.21.07.png?alt=media&amp;token=53480144-29f2-4556-84a1-cc58f6e7e721" alt=""><figcaption></figcaption></figure>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FlY4U0f4XDLrFTQ1LUbx8%2Fimage%20(2)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=eca731a8-ce4e-4424-81b4-e0a8ab45e522" alt=""><figcaption></figcaption></figure>

Click **Add webhook** to save.

### Adding a CI Pipeline File

GitLab only fires pipeline events when the project has an active CI configuration. If your repository doesn't already have one, navigate to **Code → Repository** in the left sidebar.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FXOPHqBi6LDugwtGMGS7i%2Fimage%20(3)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=23325860-6156-47a9-8ba4-5f5f29732157" alt=""><figcaption></figcaption></figure>

Click the **+** button and select **New file**. Name the file `.gitlab-ci.yml` and add the following content:

```yaml
test-job:
  script:
    - echo "Hello itoc360"
```

Click **Commit changes** to save the file to the repository.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F11pxWE0Pt99kzPtJoIj8%2Fimage%20(4)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=5304b534-89bd-41a1-93b1-bebe36aacc18" alt=""><figcaption></figcaption></figure>

Once committed, GitLab will automatically trigger a pipeline run, which sends a webhook event to your ITOC360 endpoint.

### Verifying the Connection

After the pipeline runs, go back to **Settings → Webhooks**. You should see a success banner at the top confirming the hook was delivered, along with your webhook listed below showing **Pipeline events** and **SSL Verification: enabled**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FryFwE9iFAkAMArbwZYWH%2FEkran%20Resmi%202026-03-24%2018.23.26.png?alt=media&amp;token=9b297410-eee4-4790-89fb-9a47131bb245" alt=""><figcaption></figcaption></figure>

### How It Works

Every time a pipeline changes state in your GitLab project, ITOC360 receives a notification. The integration uses the `object_attributes.status` field to determine alert severity and whether to open or close an alert:

* **failed** pipelines create a HIGH priority alert
* **canceled** or **skipped** pipelines create a MEDIUM or LOW priority alert
* A pipeline reaching **success** resolves the existing alert for that branch

Alerts are correlated by project ID and branch name, so a failed pipeline on `main` and its eventual successful re-run are treated as the same incident lifecycle.


# Jenkins Integration

[Jenkins](https://www.jenkins.io/) is an open-source automation server widely used for building, testing, and deploying software. Through its Notification plugin, Jenkins can send build lifecycle events to external systems — including ITOC360 — whenever a job changes state.

### Prerequisites

* A running Jenkins instance
* The **Notification Plugin** installed (available in the Jenkins plugin marketplace)
* An ITOC360 source token for Jenkins

***

### Creating a Pipeline Job

Start by navigating to the Jenkins dashboard and clicking **New Item** in the left sidebar. Enter a name for your job — something like `ITOC360` works fine — and select **Pipeline** as the item type.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FVdx18RUwJDXk12itIbwo%2Fimage%20(5)%20(1).png?alt=media&amp;token=1a483877-ed51-4418-886f-7a3d846bf6af" alt=""><figcaption></figcaption></figure>

Once you've selected Pipeline, click **OK** to proceed to the configuration page.

### Configuring the Notification Endpoint

On the job configuration page, scroll down to the **Job Notifications** section. Click **Add Endpoint** to reveal the endpoint settings. Fill in the fields as follows:

* **Format:** JSON
* **Protocol:** HTTP
* **Event:** All Events
* **URL Source:** Plain Text
* **URL:** ITOC360 webhook URL with the token appended as a&#x20;

The URL should look like this:

```
https://api.itoc360.app/functions/v1/events?token=<x-itoc360-token>
```

Leave Timeout at the default (30000 ms) and Retries at 0 unless you have a specific reason to change them.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FSs2yXlA3cgUOIOR7lQKi%2Fimage%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=573c0679-7e44-4d75-b7e4-772a41d8897b" alt=""><figcaption></figcaption></figure>

***

### Adding the Pipeline Script

Scroll down to the **Pipeline** section. Make sure the Definition is set to **Pipeline script**, then paste the following into the Script field:

```groovy
pipeline {
    agent any
    stages {
        stage('Test') {
            steps {
                echo 'Build active'
            }
        }
    }
}
```

This is a minimal pipeline that runs a single stage. In a real setup, this would contain your actual build and test steps. The important part for ITOC360 is the Notification endpoint you configured above — it fires regardless of what the pipeline does.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F2HWC5eNcNcDJINNzvHVF%2Fimage%20(2)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=d3e67e34-d218-40d0-97c7-26923c0398b4" alt=""><figcaption></figcaption></figure>

Click **Save** when done.

### How It Works

Once the job is saved, Jenkins will send a notification to your ITOC360 endpoint at each phase of the build lifecycle: **QUEUED**, **STARTED**, **COMPLETED**, and **FINALIZED**. ITOC360 uses the `build.phase` and `build.status` fields to determine whether the event is an alert or a resolution:

* A build reaching **FINALIZED** with status **SUCCESS** is treated as a **RESOLVE**
* Any other phase or a failed build is treated as an **ALERT**

Priority is mapped from the `build.status` field. Failed builds come in as HIGH priority, unstable and aborted builds as MEDIUM, and successful builds as LOW.

### Testing the Integration

To verify everything is wired up correctly, go back to the job page and click **Build Now** in the left sidebar. Jenkins will immediately queue and run the pipeline, sending notifications to your itoc360 endpoint at each phase transition. You should see a new alert appear in your itoc360 dashboard within a few seconds, with the source set to your Jenkins integration and the provider shown as Jenkins.


# Terraform Cloud/Terraform Enterprise Integration

[Terraform Cloud](https://developer.hashicorp.com/terraform) is HashiCorp's managed infrastructure automation platform that lets teams collaborate on Terraform runs, manage state remotely, and enforce policies across their infrastructure. It supports workspace-level webhook notifications that fire on run events — making it easy to route pipeline failures, plan results, and apply outcomes directly into ITOC360.

### In ITOC360

Go to Sources, click **Create Source**, and select **Terraform Cloud** from the list. Once the source is created, copy the webhook URL and token from the source detail page — you will need these when configuring Terraform Cloud.

### In Terraform Cloud

Open your workspace and navigate to **Settings → Notifications** from the left sidebar.\ <br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F2LDG5r26pQPGyFbzscJb%2Fimage%20(4)%20(1).png?alt=media&amp;token=8b6fa06a-5955-421d-86ba-ee3cd7bc07f5" alt=""><figcaption></figcaption></figure>

Click **Create a Notification** in the top right corner. On the form that appears, select **Webhook** as the destination type. Give the notification a name and paste your ITOC360 webhook URL into the **Webhook URL** field, appending your source token as a query parameter:

```
https://api.itoc360.app/functions/v1/events?token=<x-itoc360-token>
```

Leave the **Token** field empty. Under **Run Events**, select **All events** so that ITOC360 receives notifications for every stage of a run. Click **Create a notification** to save.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FunKW5F5fCRVlluFOao6A%2Fimage%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=06993b7d-40db-440c-9a02-cc35e2af04b6" alt=""><figcaption></figcaption></figure>

Terraform Cloud will immediately send a verification request to your webhook URL. If ITOC360 responds with a success, the notification will be enabled automatically and appear in your notifications list.\ <br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FiTudF6ZvrcueJm0D7S1y%2Fimage%20(122).png?alt=media&amp;token=f4037da7-153c-4779-8c4a-42dc38a7b151" alt=""><figcaption></figcaption></figure>

***

### Notes

* Terraform Cloud sends a separate notification for each run stage: Created, Planning, Needs Attention, Applying, Completed, and Errored. ITOC360 treats a run as resolved only when it reaches the **Applied** (completed) state.
* The **Token** field in Terraform Cloud is used for HMAC-SHA512 request signing and is separate from your ITOC360 source token. You do not need to fill it in for ITOC360 to work.
* Notifications are workspace-specific. If you have multiple workspaces, you will need to create a notification configuration in each one.


# Error Tracking and Uptime

This category covers error monitoring, uptime checking, and API testing platforms. These tools detect application errors, service outages, and failing health checks — and send alerts to ITOC360 so the responsible engineer is notified the moment something goes wrong.

***

### Integrations in this category

| Integration       | What it monitors                                                | Alert delivery |
| ----------------- | --------------------------------------------------------------- | -------------- |
| **Sentry**        | Application exceptions, performance regressions, release health | Webhook        |
| **Rollbar**       | Real-time error tracking across web and mobile applications     | Webhook        |
| **Pingdom**       | Website uptime, page speed, transaction monitoring              | Webhook        |
| **StatusCake**    | Uptime, SSL expiry, page speed, and domain monitoring           | Webhook        |
| **Postman**       | API monitor test failures, response time thresholds             | Webhook        |
| **Statuspage.io** | Public status page incidents and component degradations         | Webhook        |

***

### How it works

Error tracking and uptime tools run continuous checks against your applications, endpoints, and APIs. When a check fails, an error threshold is exceeded, or a service goes down, the tool sends an alert to your ITOC360 Source webhook URL. ITOC360 routes the alert through your escalation policy and notifies the on-call engineer so they can respond before users are impacted.

{% hint style="info" %}
ITOC360 generates a unique webhook URL per Source. Go to **Management > Sources**, create a Source, and paste the webhook URL into your tool's alert notification settings.
{% endhint %}

***

### Get started


# Pingdom Integration

[Pingdom](https://www.pingdom.com/) is an uptime and performance monitoring tool that checks whether your websites and services are accessible. When a check changes state — going down or coming back up — Pingdom can send an HTTP POST request to a webhook URL of your choice. This page explains how to connect Pingdom to ITOC360 so that downtime alerts are routed directly into your on-call workflows.

### How It Works

Pingdom monitors your endpoints at regular intervals from multiple probe locations around the world. When it detects that a site has gone down (or recovered), it fires a webhook notification to any integration you have configured on that check. No scripting or custom payload mapping is required — you simply provide ITOC360's webhook URL, and Pingdom handles the rest.

### Prerequisites

* A Pingdom account (Starter plan or higher)
* An ITOC360 account with at least one active on-call schedule

### Step 1 — Add ITOC360 as a Webhook Integration

Open your Pingdom dashboard and navigate to **Settings → Integrations** from the left sidebar.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F7jD0UNaLpnFAgsTORtYU%2Fimage%20(94).png?alt=media&amp;token=4151a70e-0e13-4953-b495-62d4b9aeb2a1" alt=""><figcaption></figcaption></figure>

Click **Add Integration**, select **Webhook** as the integration type, then fill in the form:

<table><thead><tr><th>Field</th><th width="423.634521484375">Value</th></tr></thead><tbody><tr><td>Name</td><td>ITOC360 </td></tr><tr><td>URL</td><td><a href="https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>">https://api.itoc360.app/functions/v1/events?token=&#x3C;x-itoc360-token></a></td></tr><tr><td>Active</td><td>✅ Checked</td></tr></tbody></table>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FDlwqdYoOj0wLvXDYOUsW%2FEkran%20Resmi%202026-03-23%2015.36.50.png?alt=media&amp;token=a8f00c0d-a95a-4df5-9fff-802f415022bb" alt=""><figcaption></figcaption></figure>

Click **Save integration** to confirm.

### Step 2 — Connect the Integration to Your Checks

The webhook you just created must be linked to each uptime check you want to monitor. Open a check (or create a new one) via **Synthetics → Uptime → Add new**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FVmdLOtLDueAHkEOtNz4K%2FEkran%20Resmi%202026-03-23%2015.38.01.png?alt=media&amp;token=6991c712-1764-4a55-8d4d-412a9754a41b" alt=""><figcaption></figcaption></figure>

Scroll down to the **Alerting Settings** section and configure check importance and who should be notified.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FRXMdd7OjmQlIMvdJsGQd%2FEkran%20Resmi%202026-03-23%2015.38.53.png?alt=media&amp;token=9126dc1b-fb82-4bad-b85f-276dc0bbea01" alt=""><figcaption></figcaption></figure>

Continue scrolling to the **Connect Integrations** section at the bottom of the form. Your newly created webhook will appear in the list — make sure it is selected.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FsZbvUDiG6tg3vFaCnj12%2FEkran%20Resmi%202026-03-23%2015.42.38.png?alt=media&amp;token=af59894a-5197-4bee-a335-9551a08ab496" alt=""><figcaption></figcaption></figure>

Click **Create check** (or **Save** if editing an existing check).

***

### Step 3 — Verify the Connection

To confirm that alerts are reaching ITOC360, trigger a test alert from the Pingdom integrations page or briefly pause and resume the check. Within a few minutes, a new alert should appear in your ITOC360 alert feed.

A successful Pingdom webhook payload looks like this:

```json
{
  "version": 1,
  "check_id": 14401378,
  "check_name": "My Website",
  "check_type": "HTTP",
  "check_params": {
    "hostname": "mywebsite.com",
    "full_url": "http://mywebsite.com/",
    "port": 80
  },
  "importance_level": "HIGH",
  "previous_state": "UP",
  "current_state": "DOWN",
  "state_changed_utc_time": "2026-03-23T12:27:50",
  "description": "Non-recoverable failure in name resolution",
  "first_probe": {},
  "second_probe": {}
}
```

***

### Priority Mapping

ITOC360 maps Pingdom's `importance_level` field to alert priorities as follows:

| Pingdom Importance | itoc360 Priority |
| ------------------ | ---------------- |
| LOW                | LOW              |
| MEDIUM             | MEDIUM           |
| HIGH               | HIGH             |

You can adjust the importance level of any check under **Alerting Settings → Check importance** when creating or editing a check.

### Troubleshooting

**Alerts are not appearing in** ITOC360 Make sure the ITOC360 webhook integration is actually selected under **Connect Integrations** on the specific check. Adding an integration to Pingdom does not automatically attach it to existing checks — you need to link it manually per check.

**Receiving email alerts but no webhook calls** This is the same issue as above. Email notifications and webhook integrations are configured separately in Pingdom. Check that the webhook is connected to the check in addition to your email notification settings.

**Duplicate alerts for the same incident** If multiple checks monitor the same host, each one will fire its own webhook on a state change. Consider consolidating overlapping checks or using tags to distinguish them in ITOC360.


# Postman Monitors Integration

[Postman](https://www.postman.com/) is an API development and testing platform that lets you run collections of HTTP requests automatically on a schedule using monitors. When a monitor run finishes, Postman can send the results directly to any webhook endpoint — including ITOC360.

This integration uses Postman's native **Webhooks** integration to forward monitor run results to ITOC360. No scripting or custom code required — you connect once and every subsequent monitor run is automatically reported.

### How It Works

After each monitor run, Postman sends a JSON payload containing run metrics such as the number of failed tests, errors, and total latency to your ITOC360 webhook URL. ITOC360 evaluates those metrics and opens an incident when tests fail, then resolves it automatically when the monitor passes again.

**Try the API in Postman**

Explore the ITOC360 API with ready-to-use requests for alert ingestion and incident management:

[![Run In Postman](https://run.pstmn.io/button.svg)](https://god.gw.postman.com/run-collection/56096420-0bf8b92e-4bf5-4a19-8627-bb76ace25100?action=collection%2Ffork\&source=rip_markdown\&collection-url=entityId%3D56096420-0bf8b92e-4bf5-4a19-8627-bb76ace25100%26entityType%3Dcollection%26workspaceId%3D0f414c22-0621-4764-adcb-d3b1b2d5ec18)

Browse our full public workspace on the [Postman API Network](https://www.postman.com/itoc360/itoc360/collection/vwhrxhw/itoc360-api).

### Prerequisites

* A Postman account with at least one monitor configured
* Your ITOC360 webhook URL, generated when you create the integration

### In ITOC360

Go to **Integrations**, click **Add Integration**, and select **Postman Monitors** from the list. Copy the webhook URL that appears — you'll need it in the next steps.

### In Postman

#### Step 1 — Open Integrations

Click your workspace name or avatar in the top left, then select **Integrations** from the left sidebar menu.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F5TOjgvkex2xP0njpCZEG%2Fimage%20(104).png?alt=media&amp;token=65123aff-8d45-4bc4-87c9-4486f6c908e1" alt=""><figcaption></figcaption></figure>

On the Integrations page, search for **web** in the search bar and click the **Webhooks** tile.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F4YEQ5oWw3JtEznFciyNv%2Fimage%20(105).png?alt=media&amp;token=98bdbd86-5e99-4dcf-8d45-6c06340223cd" alt=""><figcaption></figcaption></figure>

#### Step 2 — Add a Webhook Integration

The Webhooks page lists three types of integrations. Click **Add Integration** next to **Post monitoring results**.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FxfncuDpEDPPpvfTi0huL%2Fimage%20(106).png?alt=media&amp;token=03dff112-605b-46d8-8f72-bf279fba5d8a" alt=""><figcaption></figcaption></figure>

Fill in the form as follows:

* **Nickname** — give it a recognizable name, such as `ITOC360`
* **Choose workspace** — select the workspace where your monitor lives
* **Choose Monitor** — select the monitor whose results you want to forward
* **Webhook URL** — [https://api.itoc360.app/functions/v1/events?token=\<x-itoc360-token>](https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>)
* **Configure when monitor runs must be notified** — select **Notify for all completed monitor runs** so that both failures and recoveries are sent to ITOC360

Click **Add Integration** to save.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FjU4WaDsCWP5YB3g4EWr6%2Fimage%20(107).png?alt=media&amp;token=5f53223e-8f9b-479b-a9d4-c0a118f4e473" alt=""><figcaption></figcaption></figure>

### Alert Behavior

| Condition                              | itoc360 Action        |
| -------------------------------------- | --------------------- |
| `failedTests > 0` or `errors > 0`      | Opens an incident     |
| `failedTests === 0` and `errors === 0` | Resolves the incident |

ITOC360 uses the monitor's unique identifier to match open and resolved events together, so the same monitor's failures and recoveries are always linked to the same incident.

### Notes

* Make sure to select **Notify for all completed monitor runs** rather than the default option. Without this, ITOC360 will not receive recovery payloads and incidents will never resolve automatically.
* If you have multiple monitors, add a separate webhook integration for each one and point them all at the same ITOC360 webhook URL.

### Resources

* ITOC360 on the Postman API Network: [postman.com/itoc360](https://www.postman.com/itoc360)
* Ready-to-use API collection: fork it from our public workspace to send test alerts in seconds


# Rollbar Integration

### Overview

[Rollbar](https://rollbar.com/) is an error monitoring and tracking platform that captures exceptions, errors, and log messages from your applications in real time. By configuring a webhook notification channel in Rollbar, you can forward error alerts directly to ITOC360 and trigger your on-call escalation policies the moment a new issue is detected.

### Provider Configuration & Mapping

ITOC360 uses the `event_name` field from the Rollbar webhook payload to determine the alert type.

| Rollbar Event      | ITOC360 Type |
| ------------------ | ------------ |
| `new_item`         | ALERT        |
| `reactivated_item` | ALERT        |
| `reopened_item`    | ALERT        |
| `occurrence`       | ALERT        |
| `item_velocity`    | ALERT        |
| `exp_repeat_item`  | ALERT        |
| `resolved_item`    | RESOLVE      |

Priority is mapped from the `level` field on the item:

| Rollbar Level   | ITOC360 Priority |
| --------------- | ---------------- |
| `20` (debug)    | LOW              |
| `30` (warning)  | MEDIUM           |
| `40` (error)    | HIGH             |
| `50` (critical) | CRITICAL         |

### Setup Instructions

#### Step 1: Get Your Webhook URL and Token

1. Log in to your ITOC360 platform.
2. Go to **Sources → Add Source**.
3. Select **Rollbar** as your provider.
4. Save the configuration and copy the generated **Token**.

#### Step 2: Open Your Rollbar Project

1. Log in to your Rollbar account.
2. From the left sidebar, click **Projects** and select your project.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FtsvxSw6DOJSpfV1iunxn%2Fimage%20(12).png?alt=media&amp;token=dc367b88-3e2e-4864-8eb1-c3658b328ed2" alt=""><figcaption></figcaption></figure>

#### Step 3: Configure the Webhook

1. Inside your project, go to **Settings → Notifications**.
2. Under **Available Channels**, click **Webhook**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FObOr9JR0JuLMykZBfHm8%2Fimage%20(1)%20(1).png?alt=media&amp;token=da89a402-1bce-4fba-97c0-63b8ec9c1ab2" alt=""><figcaption></figcaption></figure>

3. In the **URL** field, paste your ITOC360 webhook URL in the following format:

   ```
   https://api.itoc360.app/functions/v1/events?token=<x-itoc360-token>
   ```
4. Click **Save Settings**. The webhook status will change to **Enabled**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FHqwuOlxKASxQwYzfHzwR%2Fimage%20(2)%20(1).png?alt=media&amp;token=e91bf0bf-a248-4116-a139-498ed9d324bd" alt=""><figcaption></figcaption></figure>

#### Step 4: Verify the Rules

Rollbar automatically creates default notification rules when you enable the webhook. Make sure the following rules are active:

* **New Item → Post to Webhook** — triggers when a new error is detected
* **Item Reactivated → Post to Webhook** — triggers when a previously resolved error recurs
* **Item Resolved → Post to Webhook** — triggers when an item is resolved, which automatically closes the alert in ITOC360

You can add, edit, or remove rules from the same Webhook settings page based on your team's alerting preferences.

#### Step 5: Verify the Integration

Trigger a test error in your application or use Rollbar's **Send Test Notification** button on the Webhook settings page. The alert should appear in ITOC360 under the source you created.

When the item is resolved in Rollbar, ITOC360 will automatically close the corresponding alert.


# Sentry Integration

[Sentry](https://sentry.io/welcome/) is an error tracking and performance monitoring platform that helps development teams catch and fix issues in real time. With this integration, you can forward Sentry issue events directly into ITOC360 as alerts — so when something breaks in production, your on-call team gets notified immediately through the usual escalation flow.

The integration works through Sentry's Internal Integration mechanism. Every time an issue is created, resolved, assigned, or changes state, Sentry sends a webhook to ITOC360. From there, ITOC360 handles the rest.

### Setting Up the Integration in Sentry

#### Step 1 — Create a New Internal Integration

Log into your Sentry account and head over to **Settings → Developer Settings → Custom Integrations**. You'll see a **Create New Integration** button in the top right corner. Click it and select **Internal Integration** when prompted.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fvnvu62kvtogDtUwqyhfw%2Fimage%20(3)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=ca3702c1-a1be-40e0-bae4-21dcb197549f" alt=""><figcaption></figcaption></figure>

#### Step 2 — Configure the Integration

Fill in the integration details on the form that appears:

* **Name** — Give it a recognizable name like ITOC360
* **Webhook URL** — Paste your ITOC360 webhook URL here. You can find this in ITOC360 under Sources, after creating a Sentry source. The URL follows this format:

```
https://api.itoc360.app/functions/v1/events?token=<x-itoc360-token>
```

Leave everything else as is for now.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FmTIQ4qvJv0k8nGIO2PEo%2FEkran%20Resmi%202026-03-18%2023.42.30.png?alt=media&amp;token=571e81f2-ae53-458f-b56d-0a72f6740acd" alt=""><figcaption></figcaption></figure>

#### Step 3 — Enable Issue Webhooks

Scroll down on the same page. Under the **Permissions** section, find **Issue & Event** and set it to **Read** — this is required before you can enable webhooks.

Then, under the **Webhooks** section, check the **issue** box. This tells Sentry to send a webhook to ITOC360 whenever an issue is created, resolved, assigned, archived, or unresolved.

Once everything looks good, hit **Save Changes**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FTmqr5KSnmql50kqcQ6GG%2Fimage%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=a16001ba-55bb-4335-9259-1e7bebe36d90" alt=""><figcaption></figcaption></figure>

### Setting Up an Alert Rule in Sentry

The integration alone isn't enough — you also need to tell Sentry when to actually fire the webhook. This is done through Alert Rules.

#### Step 4 — Go to Alerts

In Sentry, navigate to **Issues → Configure → Alerts** from the left sidebar.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FCcB6utW3DvccnLPJ9xpB%2Fimage%20(2)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=c1c1a74a-ad3c-4511-8894-5d11463914dd" alt=""><figcaption></figcaption></figure>

#### Step 5 — Create a New Alert Rule

Click the **Create Alert** button in the top right corner of the Alerts page.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F0vIS7QuGb27iTkUrLPhC%2Fimage%20(4)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=1955ddcd-389d-4c4f-a19d-851e7422aae5" alt=""><figcaption></figcaption></figure>

#### Step 6 — Configure the Alert Rule

On the New Alert Rule page:

1. **Select an environment and project** — Choose the Sentry project you want to monitor
2. **Set conditions** — Under the WHEN block, select **"A new issue is created"** as the trigger
3. **Set actions** — Under the THEN block, click **Add action** and select **"Send a notification via itoc360"**

Once you've set this up, you can click **Send Test Notification** to verify the connection is working. If everything is configured correctly, you'll see a new alert appear in ITOC360 shortly after.

Save the rule when you're done.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FxYGMFA4dDq233oe0ni1E%2Fimage%20(5)%20(1)%20(1).png?alt=media&amp;token=ed960f18-8614-4309-b399-16e186b96d7a" alt=""><figcaption></figcaption></figure>

### How It Works

Once the integration is active, Sentry will send a webhook to itoc360 for every issue event. itoc360 maps the incoming payload to a standardized alert format:

| Sentry Action | itoc360 Event |
| ------------- | ------------- |
| `created`     | ALERT         |
| `assigned`    | ALERT         |
| `unresolved`  | ALERT         |
| `archived`    | ALERT         |
| `resolved`    | RESOLVE       |

Priority is determined from the `priority` field in the Sentry payload:

| Sentry Priority | itoc360 Priority |
| --------------- | ---------------- |
| `low`           | LOW              |
| `medium`        | MEDIUM           |
| `high`          | HIGH             |
| `critical`      | CRITICAL         |

***

### Notes

* Issue webhooks cover state changes on existing issues. If you want ITOC360 to catch issues the moment they're created, make sure your alert rule includes the **"A new issue is created"** condition.
* The same issue will always map to the same alert in ITOC360 — so if it gets triggered, resolved, and triggered again, each cycle creates a new incident correctly without duplication.
* You can create multiple alert rules pointing to ITOC360 for different projects or conditions.


# StatusCake Integration

[StatusCake](https://www.statuscake.com/) is an uptime and performance monitoring tool that tracks whether your websites, APIs, and servers are reachable. When a monitored endpoint goes down or comes back up, StatusCake can notify any webhook URL you configure — including ITOC360.

This integration connects StatusCake to itoc360 through a Contact Group. Every time a test fails or recovers, ITOC360 receives the alert automatically and creates or resolves the corresponding incident.

### How It Works

StatusCake sends an HTTP POST request with form-encoded data to your ITOC360 webhook URL whenever a test changes state. The `Status` field in the payload tells ITOC360 whether the endpoint is `DOWN` (open an incident) or `UP` (resolve it). The combination of test name and URL is used to match open and resolved incidents together.

### Prerequisites

* A StatusCake account
* Your ITOC360 webhook URL, generated when you create the integration

### In ITOC360

Go to **Sources**, click **Create Source** , and select **StatusCake** from the list. Copy the webhook URL that appears — you'll need it in the next step.

### In StatusCake

#### Step 1 — Create a Contact Group

In the left sidebar, go to **Alerting → Contact Groups**, then click **New Contact Group**.

Fill in the form as follows:

* **Group Name** — give it a recognizable name, like `itoc360`
* **Enable Repeat Alert** — leave this disabled (the toggle should show "Disabled")
* **Webhook URL** — [https://api.itoc360.app/functions/v1/events?token=\<x-itoc360-token>](https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>)
* **Webhook Request Method** — select **POST**

You can ignore the Email and SMS fields.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FSupjKMrix76bnxw9GgII%2Fimage%20(2)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=c374dd47-79da-46f5-a2f5-4e70e0e48ced" alt=""><figcaption></figcaption></figure>

Click **Save Contact Group**.

#### Step 2 — Create an Uptime Test

In the left sidebar, go to **Monitoring → Uptime**, then click **New Uptime Test** on the right side of the page.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FtxPDKxl914dTHHs5oeuI%2Fimage%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=6b7595a3-802b-4343-8603-70a859f8a5c2" alt=""><figcaption></figcaption></figure>

Fill in the test details:

* **URL** — the endpoint you want to monitor ([https://api.itoc360.app/functions/v1/events?token=\<x-itoc-360>](https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>))
* **Test Name** — a descriptive name for the test
* **Who to Alert (Contact Groups)** — select the Contact Group you created in Step 1 (e.g. `ITOC360`)
* **Check Rate** — choose how often StatusCake should check the endpoint; **15 MIN** is a reasonable default for most use cases

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fym6B62uDKEZ5BHc7tURx%2FEkran%20Resmi%202026-03-30%2014.24.59.png?alt=media&amp;token=96602e59-ab81-4fb2-bd27-c57c7f271e4e" alt=""><figcaption></figcaption></figure>

Scroll down and click **Create Test**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F4XzpB2NVBKB10LQkEGH5%2Fimage%20(3)%20(1)%20(1)%20(1).png?alt=media&amp;token=c374227c-3b68-4d0f-b515-cd929accbe74" alt=""><figcaption></figcaption></figure>

### Alert Behavior

| Status | itoc360 Action                 |
| ------ | ------------------------------ |
| `DOWN` | Opens a new incident           |
| `UP`   | Resolves the existing incident |

StatusCake identifies which test triggered the webhook using the test name and monitored URL — ITOC360 uses these together as the incident fingerprint, so open and resolved events are always matched correctly.

### Notes

* StatusCake sends webhook payloads as `application/x-www-form-urlencoded`, not JSON. itoc360 handles this automatically.
* If you want to monitor multiple endpoints, create a separate Uptime Test for each one and assign the same Contact Group to all of them.
* The **Enable Repeat Alert** option in the Contact Group should stay disabled to avoid duplicate incidents in ITOC360 for the same outage.


# Statuspage.io Integration

Atlassian [Statuspage](https://www.atlassian.com/software/statuspage) is a communication tool that lets teams publish real-time service health information to their users. It supports outbound webhook notifications whenever an incident is created, updated, or resolved — and whenever a component's operational status changes. This integration pipes those events directly into ITOC360 so your on-call team stays in the loop without having to monitor a separate status page.

### In Statuspage.io

The webhook subscription lives under your page's **Subscribers** section. Navigate there from the left sidebar, then switch to the **Webhook** tab.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FXPtuzsDPM1oC2EIWwH4w%2Fimage%20(128).png?alt=media&amp;token=918948dc-1d0c-4f27-ab49-e886ce5818fe" alt=""><figcaption></figcaption></figure>

Click the **Options** button in the top right and select **Add subscriber**. In the modal that appears, make sure the subscriber type is set to **Webhook**, then paste your ITOC360 webhook URL into the **Endpoint URL** field.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fxgt7uS22cv1jw7aL1bhB%2FEkran%20Resmi%202026-04-02%2013.27.36.png?alt=media&amp;token=0211a1f0-828b-4e16-8299-a4d4bb8ec31a" alt=""><figcaption></figcaption></figure>

Your endpoint URL follows this format:

```
https://api.itoc360.app/functions/v1/events?token=<x-itoc360-token>
```

Hit **Add subscriber** to save. Statuspage will immediately begin sending webhook payloads to that URL whenever activity occurs on your page.

#### Triggering an incident

To verify the integration is working, head to **Incidents** in the left sidebar and click **Create incident**. Give it a name, select at least one affected component, check **Send notifications**, and hit **Create**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FvshzmcIN3RzB02AR83tB%2Fimage%20(129).png?alt=media&amp;token=3cc9e45a-9628-4fa9-9506-35f267349849" alt=""><figcaption></figcaption></figure>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FbPiGQBOi6mz6o45FggPg%2Fimage%20(131).png?alt=media&amp;token=e5878ca5-8cc7-4cbb-9620-8d9980f303db" alt=""><figcaption></figcaption></figure>

Statuspage sends a webhook for each status transition — so you will see a payload when the incident is created as `investigating`, and another when you move it through `identified`, `monitoring`, or `resolved`.

#### Updating a component status

Component-level status changes also trigger webhooks independently of incidents. Go to **Components** in the sidebar, find the component you want to update, and click **Edit** next to it.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FExN6Br0Eb9eF5791AJ12%2Fimage%20(130).png?alt=media&amp;token=1cf1b9ca-bc21-41b0-9d26-747869296e76" alt=""><figcaption></figcaption></figure>

On the edit screen, open the **Status** dropdown. You can set the component to any of the available states — Operational, Degraded performance, Partial outage, Major outage, or Under maintenance.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FrCTCmJEdCoMxjYqjpRA7%2Fimage%20(132).png?alt=media&amp;token=8925bb51-4cf6-493d-b503-d05dc379adb8" alt=""><figcaption></figcaption></figure>

Changing the status and saving fires a `component_update` webhook event. Setting it back to **Operational** will trigger a resolve event in ITOC360.

### In ITOC360

Go to **Sources**, click **Create Source**, and select **Statuspage.io** from the list. Copy the webhook URL shown on the source detail page and use it as the endpoint when adding your subscriber in Statuspage, as described above.

ITOC360 handles both event types automatically. Incident events are resolved when the incident status reaches `resolved`. Component events are resolved when the component returns to `operational`. The priority level is derived from the incident's impact field — `none` maps to Low, `minor` to Medium, `major` to High, and `critical` to Critical. Component status changes without an associated incident default to Medium priority.


# Workflow and Automation

This category covers workflow automation platforms, project management tools, and communication services. These integrations allow alerts to reach ITOC360 from business applications and automation pipelines — extending on-call coverage beyond traditional infrastructure monitoring.

***

### Integrations in this category

| Integration       | What it monitors or triggers                             | Alert delivery |
| ----------------- | -------------------------------------------------------- | -------------- |
| **Zapier**        | Automated workflow triggers from 5,000+ connected apps   | Webhook        |
| **n8n**           | Self-hosted workflow automation events and failures      | Webhook        |
| **Jira**          | Issue creation, status transitions, priority escalations | Webhook        |
| **Twilio**        | Programmable communications errors and alert events      | Webhook        |
| **MongoDB Atlas** | Database performance, replica set health, cluster alerts | Webhook        |
| **Salesforce**    | CRM workflow failures, critical record events            | Webhook        |

***

### How it works

Workflow and automation platforms generate events when business processes fail, data conditions are met, or integrations break. These events are forwarded to ITOC360 via webhook, where they are matched against escalation policies and routed to the on-call engineer. This allows teams to extend incident management beyond infrastructure — covering business-critical applications and automated pipelines.

{% hint style="info" %}
ITOC360 generates a unique webhook URL per Source. Go to **Management > Sources**, create a Source, and paste the webhook URL into your automation platform's outbound webhook or action settings.
{% endhint %}

***

### Get started


# Jira Inbound Integration

[Jira](https://www.atlassian.com/software/jira) is a project and issue tracking platform used by software teams to manage tasks, bugs, and feature work. It supports native webhooks that fire whenever an issue is created, updated, or deleted — making it straightforward to forward those events to ITOC360 in real time.

This integration creates an alert in ITOC360 whenever a Jira issue is opened or moved to an active status, and automatically resolves it when the issue is marked as Done, closed, or resolved.

### How It Works

Jira sends an HTTP POST request to your ITOC360 webhook URL every time a subscribed issue event occurs. The payload includes the full issue details — summary, status, priority, and the user who triggered the change. ITOC360 uses the issue's status to decide whether to open or resolve an alert, and uses the issue key (e.g. `KAN-5`) as the fingerprint to match events belonging to the same issue together.

### Prerequisites

* A Jira Cloud account with admin access
* Your ITOC360 webhook URL, generated when you create the source

### In ITOC360

Go to **Sources**, click **Create Source**, and select **Jira** from the list. Copy the webhook URL that appears — you'll need it in the next steps.

### In Jira

#### Step 1 — Open System Settings

Click the gear icon in the top right corner of Jira, then select **System** from the settings menu.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FodG5bJxr0O23vyyyZURt%2Fimage%20(109).png?alt=media&amp;token=5cb438b2-c52a-4508-a68b-2c4d62be8f0c" alt=""><figcaption></figcaption></figure>

In the left sidebar, scroll down to the **Advanced** section and click **WebHooks**.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FTCTGHd3IgYGJ5IEaTKgE%2Fimage%20(110).png?alt=media&amp;token=c3ea0123-6e93-49e4-810a-584741fe17d5" alt=""><figcaption></figcaption></figure>

#### Step 2 — Create a Webhook

On the WebHooks page, click **+ Create a WebHook** in the top right corner.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FJNI71ihlxFbjyzlUX7eW%2Fimage%20(111).png?alt=media&amp;token=d60e46bf-2810-4798-b3e2-3089381a07f4" alt=""><figcaption></figcaption></figure>

Fill in the form as follows:

* **Name** — give it a recognizable name like `itoc360`
* **Status** — leave as **Enabled**
* **URL** — [https://api.itoc360.app/functions/v1/events?token=\<x-itoc360-token>](https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>)
* **Secret** — leave blank\ <br>

  <figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FW0vTbGhHGJOV16NkqEZ9%2FEkran%20Resmi%202026-03-30%2019.53.08.png?alt=media&amp;token=ce8b20e2-2e99-43fc-8e79-0eae690f87c5" alt=""><figcaption></figcaption></figure>

***

#### Step 3 — Select Events

Scroll down to the **Issue** section and check **created**, **updated**, and **deleted**. Leave the JQL field set to **All issues** unless you want to scope the webhook to a specific project.

Click **Create** to save.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FkJ5x8TRf0zuN8DMuPzQo%2Fimage%20(113).png?alt=media&amp;token=c592cbde-be13-44ec-b913-a9503c0b5a55" alt=""><figcaption></figcaption></figure>

### Alert Behavior

| Event                                                   | itoc360 Action             |
| ------------------------------------------------------- | -------------------------- |
| Issue created                                           | Opens an alert             |
| Issue updated → status becomes Done / Closed / Resolved | Resolves the alert         |
| Issue deleted                                           | Resolves the alert         |
| Issue updated → any other change                        | Opens or updates the alert |

The alert priority is mapped from the Jira issue priority field.

| Jira Priority | itoc360 Priority |
| ------------- | ---------------- |
| Critical      | CRITICAL         |
| High          | HIGH             |
| Medium        | MEDIUM           |
| Low           | LOW              |

### Notes

* ITOC360 uses the Jira issue key (e.g. `KAN-5`) as the unique fingerprint. If the same issue transitions through multiple statuses, all events are grouped under the same alert.
* If you want to limit notifications to a specific project, add a JQL filter like `project = KAN` in the webhook configuration.
* You can create multiple webhooks pointing to different ITOC360 sources if you want to separate alerts by project or team.


# Linear Integration

### Overview

[Linear](https://linear.app/) is a modern issue tracking tool built for high-performance software teams. This integration listens for Linear webhooks and turns issue activity into actionable alerts on the platform.

Whenever a new issue is created or an existing one is updated, the platform opens an alert. When the issue is marked as **Done** or **Canceled**, the alert is automatically resolved.

This is useful when your engineering team uses Linear to track production incidents, bugs, or urgent tasks, and you want that activity to flow into the same on-call and escalation workflows you already use for monitoring alerts.

### Integration Flow

1. An issue is created or updated in Linear — manually by a team member, via API, or through another automation.
2. Linear sends a webhook POST request to the platform endpoint, signed with an HMAC signature.
3. The platform classifies the event:
   * `create` on an Issue → opens a new alert
   * `update` that leaves the issue open → keeps the alert open (updates the timeline)
   * `update` that moves the issue to a completed or canceled state → resolves the alert
   * `remove` (issue deleted) → resolves the alert
4. The alert's priority is derived from the Linear issue's **priority** field and mapped to an internal priority level.

### Webhook Payload Schema

```json
{
  "action": "create | update | remove",
  "type": "Issue",
  "actor": {
    "id": "string",
    "name": "string",
    "email": "string",
    "url": "string",
    "type": "user"
  },
  "createdAt": "ISO8601 timestamp",
  "data": {
    "id": "uuid",
    "identifier": "string",
    "number": 0,
    "title": "string",
    "description": "string",
    "priority": 0,
    "priorityLabel": "string",
    "state": {
      "id": "uuid",
      "name": "string",
      "type": "unstarted | started | completed | canceled | triage",
      "color": "string"
    },
    "team": {
      "id": "uuid",
      "key": "string",
      "name": "string"
    },
    "labels": [
      {"id": "uuid", "name": "string", "color": "string"}
    ],
    "assignee": {"id": "uuid", "name": "string", "email": "string"},
    "url": "string",
    "completedAt": "ISO8601 timestamp"
  },
  "updatedFrom": {},
  "url": "string",
  "organizationId": "uuid",
  "webhookTimestamp": 0,
  "webhookId": "uuid"
}
```

Only payloads with `type: "Issue"` are processed. Comment, Project, and other resource types are ignored.

### Setup

#### Step 1 — Create an Alert Source on the Platform

1. Navigate to **Sources → Add Source**.
2. Search for **Linear** and select it.
3. Give the source a name and click **Save**.
4. Copy the **ITOC360 URL** and **Token**&#x20;

#### Step 2 — Open Linear Settings

In your Linear workspace, click the workspace avatar in the top-left and select **Settings**. You can also use the keyboard shortcut **G** then **S**.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FrOZHlg3ck2Fo4B4n98G4%2Fimage%20(154).png?alt=media&amp;token=03e20268-119a-48fc-97fa-ab8eb61fe7ea" alt=""><figcaption></figcaption></figure>

#### Step 3 — Go to the API Section

In the Settings sidebar, scroll to **Administration** and click **API**. This page shows your OAuth applications, webhooks, and API keys.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FwBDDuxXYeW2f2Yj6FsmO%2Fimage%20(155).png?alt=media&amp;token=9a44e806-bdbd-427b-afc5-9b81e2d81409" alt=""><figcaption></figcaption></figure>

#### Step 4 — Create a Webhook

Under the **Webhooks** section, click **+ New webhook**. Fill in the form:

* **Label** — a descriptive name, for example `itoc360`.
* **URL** — [https://api.itoc360.app/functions/v1/events?token=\<x-itoc360-token>](https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>)
* **Data change events** — enable **Issues**. You can also enable **Comments** if you want comment activity to flow through, but only Issue events are processed by this integration.
* **Team selection** — choose `All public teams` or a specific team depending on scope.

Click **Create webhook**.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FR6WORBYj7VZnKkQ4ENcQ%2Fimage%20(156).png?alt=media&amp;token=93462cbb-9d3b-43d9-8d8f-4d206f474f16" alt=""><figcaption></figcaption></figure>

> Linear will display a **Signing secret** on the webhook detail page. Store it securely — it is used to verify that incoming webhooks genuinely come from Linear. You can also reveal or rotate it later from the same page.

#### Step 5 — Verify the Webhook

After creation, you will land on the webhook detail page. Confirm:

* **Delivery status** is `Enabled`.
* **URL** : [https://api.itoc360.app/functions/v1/events?token=\<x-itoc-360>](https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>)
* **Data change events** shows `Issue` (and `Comment` if you enabled it).
* **Receive events from** matches your team selection.

The **Delivery failures** section at the bottom will remain empty as long as the platform is reachable \
and responds with a 2xx status.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F2EibgrGyGSik32nlZzuw%2Fimage%20(157).png?alt=media&amp;token=5235ea37-b8bf-44d8-b556-5935e0b52dcd" alt=""><figcaption></figcaption></figure>

#### Step 6 — Trigger a Test Issue

Create a new issue in Linear to verify the end-to-end flow:

1. Open any team's issue view and click **New issue** (or press **C**).
2. Give it a title, description, priority, and assignee.
3. Click **Create issue**.

\
Within a second or two, the alert should appear on the platform under the source you created in Step 1. Change the issue's state to **Done** to confirm that the alert is automatically resolved.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FFdLRtgWsQMS66Yl32W59%2Fimage%20(158).png?alt=media&amp;token=538bd154-404d-4af2-b262-5e328310752c" alt=""><figcaption></figcaption></figure>

### Event Behavior

The platform processes Linear events using the `action` field and the issue's state.

| Linear Event                              | Platform Behavior                                 |
| ----------------------------------------- | ------------------------------------------------- |
| `action: create`                          | Opens a new alert                                 |
| `action: update`, state still open        | Appends an event to the existing alert's timeline |
| `action: update`, `state.type: completed` | Resolves the alert                                |
| `action: update`, `state.type: canceled`  | Resolves the alert                                |
| `action: remove`                          | Resolves the alert                                |
| Any event with `type != "Issue"`          | Ignored                                           |

All events from the same Linear issue are linked to the same alert through a fingerprint derived from the issue's UUID. This means priority changes, title edits, description updates, and state transitions all flow into a single alert — no duplicates.

### Sample Payloads

The following payloads were captured during integration testing.

**ALERT — issue created with Urgent priority:**

```json
{
  "action": "create",
  "actor": {
    "id": "1cbbf81a-29db-4874-87b3-e1d0c64dd8b9",
    "name": "abc@.com.tr",
    "email": "abc@.com.tr",
    "type": "user"
  },
  "createdAt": "2026-04-17T14:06:27.112Z",
  "data": {
    "id": "5cc28a8c-7259-4548-8c93-1c98ada785cb",
    "identifier": "ITO-5",
    "number": 5,
    "title": "Production API responding with 500 errors",
    "description": "Multiple 500 errors reported on /api/orders endpoint since 14:30. Investigating.",
    "priority": 1,
    "priorityLabel": "Urgent",
    "state": {
      "id": "8eef44ea-edc9-4f7e-8d3a-1c446c510fe6",
      "name": "Todo",
      "type": "unstarted",
      "color": "#e2e2e2"
    },
    "team": {"id": "9ede9327-af3e-468a-9b22-9181453feb1b", "key": "ITO", "name": "Itoc360space"},
    "labels": [{"id": "2d90f79a-73dc-4879-a6de-db5c93e71a91", "name": "Bug", "color": "#EB5757"}],
    "url": "https://linear.app/itoc360space/issue/ITO-5/production-api-responding-with-500-errors"
  },
  "type": "Issue",
  "organizationId": "d05809de-2327-4443-a202-e96ec357a5e4",
  "webhookTimestamp": 1776434787544,
  "webhookId": "a32c7c48-0b88-4baf-87d9-468c8e4dea48"
}
```

**RESOLVE — issue moved to Done:**

```json
{
  "action": "update",
  "actor": {
    "id": "1cbbf81a-29db-4874-87b3-e1d0c64dd8b9",
    "name": "abc@.com.tr",
    "email": "abc@.com.tr",
    "type": "user"
  },
  "createdAt": "2026-04-17T14:08:09.041Z",
  "data": {
    "id": "5cc28a8c-7259-4548-8c93-1c98ada785cb",
    "identifier": "ITO-5",
    "title": "Production API responding with 500 errors",
    "priority": 2,
    "priorityLabel": "High",
    "completedAt": "2026-04-17T14:08:09.026Z",
    "state": {
      "id": "f2ea18b1-0b90-46d1-b9c3-0daae99ceffc",
      "name": "Done",
      "type": "completed",
      "color": "#5e6ad2"
    },
    "url": "https://linear.app/itoc360space/issue/ITO-5/production-api-responding-with-500-errors"
  },
  "updatedFrom": {
    "stateId": "8eef44ea-edc9-4f7e-8d3a-1c446c510fe6",
    "completedAt": null
  },
  "type": "Issue",
  "organizationId": "d05809de-2327-4443-a202-e96ec357a5e4",
  "webhookTimestamp": 1776434889612,
  "webhookId": "a32c7c48-0b88-4baf-87d9-468c8e4dea48"
}
```

### Field Mapping Reference

| Payload Field        | Description                                                                     |
| -------------------- | ------------------------------------------------------------------------------- |
| `action`             | Event type: `create`, `update`, or `remove`                                     |
| `type`               | Resource type. Only `Issue` is processed                                        |
| `data.id`            | Issue UUID — used to fingerprint and deduplicate all events from the same issue |
| `data.identifier`    | Human-readable key (e.g., `ITO-5`) — shown in the alert title                   |
| `data.title`         | Issue title — shown in the alert title                                          |
| `data.priority`      | Integer priority from Linear — used for priority mapping                        |
| `data.priorityLabel` | Human-readable priority (`Urgent`, `High`, etc.)                                |
| `data.state.type`    | State category — `completed` and `canceled` trigger resolution                  |
| `data.state.name`    | Human-readable state name (`Todo`, `In Progress`, `Done`)                       |
| `data.completedAt`   | ISO 8601 timestamp set when the issue is completed                              |
| `data.url`           | Direct link back to the issue in Linear                                         |
| `data.team`          | Team that owns the issue                                                        |
| `data.labels`        | Labels attached to the issue                                                    |
| `data.assignee`      | User assigned to the issue                                                      |
| `actor`              | User or agent that triggered the event                                          |
| `updatedFrom`        | Previous values for fields that changed in this event (update events only)      |

### Priority Mapping

Linear uses integer priority values. The platform maps them to internal priorities as follows:

| Linear `priority` | Linear Label | Platform Priority |
| ----------------- | ------------ | ----------------- |
| `1`               | Urgent       | CRITICAL          |
| `2`               | High         | HIGH              |
| `3`               | Medium       | MEDIUM            |
| `4`               | Low          | LOW               |
| `0`               | No priority  | MEDIUM (default)  |

You control the issue priority in Linear. Changing an issue's priority after the alert is opened appends an update to the alert's timeline.

### RESOLVE Detection

The platform resolves an alert when Linear sends an update where the issue's `state.type` is `completed` (Done and custom done-category states) or `canceled`. It also resolves the alert when the issue is deleted (`action: remove`).

The resolve event is matched to the original alert using a fingerprint derived from the Linear issue's UUID (`data.id`), which is stable across the entire lifecycle of the issue. As long as the issue is not recreated, the fingerprint will match and the alert will be closed cleanly.

If the same issue is later reopened (moved from Done back to a non-completed state), the platform treats that as a new alert, since the previous alert is already resolved.


# MongoDB Atlas Integration

Forward database and infrastructure alerts from [MongoDB](https://www.mongodb.com/cloud/atlas/register) Atlas directly into itoc360 to keep your on-call team in the loop whenever something goes wrong with your clusters.

### Overview

MongoDB Atlas is a fully managed cloud database platform that monitors your deployments and fires alerts when conditions cross defined thresholds — things like a host going down, replica set losing its primary, or replication lag climbing too high. These alerts can be routed to external systems via webhook, which is exactly how ITOC360 receives them.

When Atlas opens an alert, ITOC360 creates a new incident. When Atlas closes it — because the condition resolved on its own or you fixed it — ITOC360 automatically resolves the incident. No manual cleanup required.

### Step 1 — Configure the Webhook in Atlas Integrations

Every Atlas project has a single shared webhook endpoint used across all alert rules. You need to set this up before creating any alert rules.

1. In your Atlas project, open **Project Settings** (the gear icon next to the project name in the sidebar).
2. Click **Integrations** in the left menu.
3. Scroll down to the **Webhook Settings** card and click **Configure**.

The integrations page lists all the third-party services Atlas supports — Datadog, Splunk, OpsGenie, and others. The **Webhook Settings** card at the bottom right is what you need.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FuKSCX5aP9gjsJy10hu1Y%2Fimage%20(6)%20(1).png?alt=media&amp;token=71066d08-d301-4478-ac6e-aa0e97b6581a" alt=""><figcaption></figcaption></figure>

4. In the **Webhook Configuration** dialog, paste your ITOC360 source webhook URL ([https://api.itoc360.app/functions/v1/events?token=\<x-itoc360-token>](https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>)) into the **Webhook URL** field. Leave **Webhook Secret** blank.
5. Click **Save**.<br>

   <figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fya8nxzonYFs0yRc9gMAV%2FEkran%20Resmi%202026-03-18%2000.00.24.png?alt=media&amp;token=2e44d732-a99f-4a21-abdd-a11bcb761d63" alt=""><figcaption></figcaption></figure>

> **Note:** Paste the full itoc360 webhook URL including the token query parameter into the Webhook URL field, for example `https://<your-url>/functions/v1/integrations?token=<your-token>`. Atlas does not support custom request headers on webhooks, so the token must be included in the URL itself.

***

### Step 2 — Create an Alert Rule

Now that the webhook destination is set, you can configure which conditions trigger notifications.

1. In the left sidebar, navigate to **Alerts** — you can also reach it by appending `#/alerts` to your project URL.
2. The **Project Alerts** page shows three tabs: Open Alerts, Closed Alerts, and Alert Settings. Click **Add New Alert** to create a new rule.<br>

   <figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FQu5FcXA3K704Hz9vHW2v%2FEkran%20Resmi%202026-03-18%2000.01.47.png?alt=media&amp;token=69fc7ef9-ba20-45e5-8aa1-d2d599b62a62" alt=""><figcaption></figcaption></figure>
3. In the **Create a New Alert** panel, fill in the three sections:
   * **Category and Condition** — pick the type of resource to monitor (Host, Replica Set, Cluster, etc.) and the specific condition that should trigger the alert. For example, `Host → Host is down` fires whenever a host in your cluster becomes unreachable.
   * **Select Target** — choose **Any Host** to apply the rule to all hosts, or narrow it down with **Hosts where…** if you only want to cover a specific subset.
   * **Add Notification Method** — click **Add Notifier** and select **Webhook**. The URL you configured in Step 1 will be used automatically. You can also keep the default **Atlas Project** notifier to receive email alerts alongside the webhook.
4. Click **Save**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FDC0HA549nPybDCxatOp1%2Fimage%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1)%20(1).png?alt=media&amp;token=082570a3-d1e6-4097-bd45-d821b0219dad" alt=""><figcaption></figcaption></figure>

\
From this point on, whenever Atlas detects that the condition is met, it sends a POST request to your ITOC360 source and an incident opens. When the condition clears, Atlas sends another notification and the incident closes automatically.

### How Alerts Map to Incidents

ITOC360 reads the `status` field in the Atlas webhook payload to decide what to do:

| Atlas `status` | ITOC360 Action                      |
| -------------- | ----------------------------------- |
| `OPEN`         | Opens a new incident                |
| `CLOSED`       | Resolves the corresponding incident |

The match between an open and a resolve notification is based on the `id` field — Atlas uses the same alert ID for both the trigger and the resolution, so ITOC360 always closes the right incident.

### Priority Mapping

ITOC360 uses the `typeName` field to determine incident priority:

| Atlas `typeName` | ITOC360 Priority |
| ---------------- | ---------------- |
| `CLUSTER`        | Critical         |
| `HOST`           | High             |
| `REPLICA_SET`    | High             |
| `AGENT`          | Medium           |

To customize these mappings per source, go to **Sources → Edit → Priority Mapping**.

### Troubleshooting

**Webhook fires but no incident appears in** ITOC360

Check logs for validation errors. Confirm that the webhook URL in Atlas matches exactly what is shown on your ITOC360 source page, token included. A mismatch in a single character will return a 401 or 404.

**Alert opens but never resolves automatically**

Atlas sends a `CLOSED` notification only when the underlying condition actually resolves — for example, when a downed host comes back online. If the host stays down, the alert stays open. You can manually resolve it in ITOC360 in the meantime.

**Only one webhook URL allowed per project**

If you need to route different alert types to different ITOC360 sources, the cleanest approach is to create separate Atlas projects and configure each one with its own webhook URL.


# n8n Integration

#### Overview

[n8n](https://n8n.io/) is an open-source workflow automation platform that lets you connect any app or service using visual, no-code workflows. By adding an HTTP Request node to any n8n workflow, you can send alerts directly to ITOC360 and trigger your on-call escalation policies in real time.

#### Provider Configuration & Mapping

ITOC360 uses the `severity` field from the incoming payload to determine alert priority.

Priority Mapping:

| Payload Value | ITOC360 Priority |
| ------------- | ---------------- |
| `low`         | LOW              |
| `medium`      | MEDIUM           |
| `high`        | HIGH             |
| `critical`    | CRITICAL         |

#### Required Payload Format

Your HTTP Request node must send a JSON body in the following structure:

```json
{
  "event_type": "alert",
  "title":      "High CPU Usage on prod-01",
  "message":    "CPU usage exceeded 90% threshold",
  "severity":   "critical",
  "host":       "prod-01",
  "source":     "my-workflow-name",
  "timestamp":  "2026-04-06T10:00:00Z"
}
```

To resolve an existing alert, send the same payload with `event_type` set to `resolve`. The `host`, `title`, and `source` values must match the original alert exactly so ITOC360 can correlate and close it.

```json
{
  "event_type": "resolve",
  "title":      "High CPU Usage on prod-01",
  "message":    "CPU usage back to normal",
  "severity":   "critical",
  "host":       "prod-01",
  "source":     "my-workflow-name",
  "timestamp":  "2026-04-06T10:05:00Z"
}
```

#### Setup Instructions

**Step 1: Get Your ITOC360 source token**

1. Log in to your ITOC360 platform.
2. Go to **Sources → Add Source**.
3. Select **n8n** as your provider.

**Step 2: Create a New Workflow**

1. Log in to your n8n instance.
2. Go to **Workflows** and click **Add Workflow → Start from scratch**.
3. Click **Add first step** and search for **Manual Trigger**. Select it as your starting node.
4. Click the **+** button to the right of the Manual Trigger node, search for **HTTP Request**, and select it.

You should now have a two-node workflow like this:

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FG68WPcsjJPx1f8F72NLy%2Fimage%20(144).png?alt=media&amp;token=51146104-f156-4f21-a8eb-4e4e55179dda" alt=""><figcaption></figcaption></figure>

**Step 3: Configure the HTTP Request Node**

Click on the **HTTP Request** node to open its settings panel.

1. **Method:** `POST`
2. **URL:** [https://api.itoc360.app/functions/v1/events](https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>)
3. **Authentication:** `None`
4. **Send Headers:** Toggle **on**.
5. Click **Add Header** and fill in:
   * **Name:** `x-itoc360-token`
   * **Value:** Paste your token from Step 1.
6. **Send Body:** Toggle **on**.
7. **Body Content Type:** `JSON`
8. **Specify Body:** `Using JSON`

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fe9gqJvmXiWyl5D4fyGCL%2Fimage%20(145).png?alt=media&amp;token=949a4d1c-e35c-43f5-b373-e4c3147ae492" alt=""><figcaption></figcaption></figure>

**Step 4: Add the Payload**

Scroll down to the **JSON** field and paste the following:

```json
{
  "event_type": "alert",
  "title":      "High CPU Usage on prod-01",
  "message":    "CPU usage exceeded 90% threshold",
  "severity":   "critical",
  "host":       "prod-01",
  "source":     "my-workflow-name",
  "timestamp":  "2026-04-06T10:00:00Z"
}
```

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FGlVrJSlg5c3WaBxWfqEH%2FEkran%20Resmi%202026-04-06%2012.34.32.png?alt=media&amp;token=cf47cf44-c477-4bca-8d23-2536108c4216" alt=""><figcaption></figcaption></figure>

Replace the field values with your own dynamic expressions or static test values.

**Step 5: Test the Workflow**

1. Click **Test workflow** in the top right corner.
2. Both nodes should turn green, confirming a successful delivery.

Once testing is complete, replace the Manual Trigger with the actual trigger that fits your use case — such as a Schedule, Webhook, or any app event node — and publish your workflow.


# Twilio Alerts Integration

[Twilio Alarms ](https://www.twilio.com/en-us)is a monitoring feature built into the Twilio Console that lets you set thresholds on error and warning activity across your account. When the number of errors in a given time window exceeds your threshold, Twilio fires a notification — including a webhook request to any URL you configure.

This integration receives those webhook notifications and creates alerts in ITOC360 automatically. Since Twilio Alarms notify you when error volume spikes rather than on individual events, each alarm maps to a single incident in ITOC360.

### How It Works

Twilio monitors error and warning activity across your account. When the number of occurrences of a configured error code (or any error) exceeds your defined threshold within the selected time window, Twilio fires the alarm and sends a POST request to your ITOC360 webhook URL. ITOC360 opens an incident for that alarm and keeps it open until the same alarm fires again or you resolve it manually.

### Prerequisites

* A Twilio account
* Your ITOC360 source token

### In ITOC360

Go to **Integrations**, click **Add Integration**, and select **Twilio Alarms** from the list. Copy the webhook URL that appears — you'll need it in the next step.

### In Twilio

#### Step 1 — Open Manage Alarms

In the Twilio Console, click the **Monitor** tab at the top of the left sidebar. Under **Alarms**, click **Manage alarms**.

If you haven't created any alarms yet, the page will show an empty state. Click **Create alarm** in the top right corner.\ <br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FRcRarwapZBpskEfpmAST%2Fimage%20(2)%20(1)%20(1)%20(1).png?alt=media&amp;token=6d5e5205-4b9d-4ecb-b8d1-2db2de8e9ca8" alt=""><figcaption></figcaption></figure>

#### Step 2 — Configure the Alarm

The alarm creation form has four steps. Fill them in as follows:

**Step 1 — Select a target metric** Choose the error code you want to monitor. Select **Any Warning or Error** to catch all issues, or pick a specific error code from the dropdown if you want to monitor a particular failure type.

**Step 2 — Define activation threshold** Set the **Alarm threshold** to the minimum number of errors that should trigger the alarm. A threshold of `1` means the alarm fires as soon as a single matching error occurs. Choose a **Time period** that matches how quickly you want to be notified — **Every 5 minutes** gives the fastest response.

**Step 3 — Choose a notification method** Check **Enable webhook** and paste your ITOC360 webhook URL ([https://api.itoc360.app/functions/v1/events?token=\<x-itoc360-token>](https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>)) into the field that appears. You can leave email notifications unchecked.

**Step 4 — Name it** Give the alarm a descriptive name like `ITOC360` so it's easy to identify later.

Click **Save** when done.<br>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FZDPamgUZS33QqrNPBSEO%2FEkran%20Resmi%202026-03-30%2016.40.29.png?alt=media&amp;token=03076437-21ad-4c11-b1c8-44985ca1a617" alt=""><figcaption></figcaption></figure>

### Alert Behavior

Every time this alarm fires, ITOC360 opens a new alert. The priority of the alert is determined by the time window configured for the alarm — shorter windows indicate more urgent conditions.

| Time period      | Priority |
| ---------------- | -------- |
| Every 5 minutes  | CRITICAL |
| Every 15 minutes | HIGH     |
| Every 1 hour     | MEDIUM   |
| Every 12 hours   | LOW      |
| Every 24 hours   | LOW      |

### Notes

* Twilio Alarms do not send a recovery payload when conditions return to normal. Incidents opened by this integration will remain open until you resolve them manually in ITOC360, or until your team acknowledges and closes them.
* You can create multiple alarms for different error codes and point them all at the same ITOC360 webhook URL. Each alarm will open a separate incident based on its unique alarm SID.
* The alarm fires when the threshold is **met or exceeded** within the time window, not just on the first occurrence.


# Twilio Errors Integration

[Twilio's](https://www.twilio.com/en-us) Debugger webhook notifies you in real time whenever an error or warning occurs in your Twilio account — a failed SMS delivery, an invalid API request, a webhook timeout, or any other issue Twilio detects while processing your traffic.

This integration forwards those notifications to ITOC360, opening an alert every time Twilio records a new error or warning event.

### How It Works

Twilio fires an HTTP POST request to your configured webhook URL each time a Debugger event occurs. The payload includes the event's severity level (`ERROR` or `WARNING`), a unique event identifier, and a nested JSON object with product-specific details such as the affected resource SID and error code. ITOC360 receives this payload and creates an alert immediately.

### Prerequisites

* A Twilio account
* Your ITOC360 source token

### In ITOC360

Go to **Sources**, click **Create Source**, and select **Twilio Errors** from the list. Copy the webhook URL that appears — you'll need it in the next step.

### In Twilio

#### Step 1 — Open the Debugger Webhook Settings

In the Twilio Console, click the **Monitor** tab. In the left sidebar, expand **Logs → Errors**, then click **Webhook**.

Paste your ITOC360 webhook URL into the **Webhook URL(**[**https://api.itoc360.app/functions/v1/events?token=\<x-itoc360-token>**](https://api.itoc360.app/functions/v1/events?token=<x-itoc-360>)**)** field and click **Save**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FjDPEYueXPlLdEWk5Ww5x%2Fimage%20(108).png?alt=media&amp;token=03534467-460d-4b53-9d17-86a033863286" alt=""><figcaption></figcaption></figure>

***

### Alert Behavior

| Level     | itoc360 Action | Priority |
| --------- | -------------- | -------- |
| `ERROR`   | Opens an alert | HIGH     |
| `WARNING` | Opens an alert | MEDIUM   |

Twilio Errors does not send a recovery payload — alerts opened by this integration remain open until you resolve them manually in ITOC360.

### Notes

* Every individual error or warning event creates a separate alert. If your account generates high error volumes, consider using **Twilio Alarms** instead — it aggregates errors over a time window and notifies only when a threshold is exceeded, reducing noise.
* The `Payload` field in each webhook contains a JSON string with product-specific details like the error code and affected resource SID. This data is visible in the alert metadata inside itoc360.
* Twilio recommends migrating to **Twilio Event Streams** for more scalable error monitoring. The Debugger webhook remains fully functional but Event Streams provides more flexibility for high-volume accounts.


# Zapier Integration

[Zapier](https://zapier.com/) is a no-code automation platform that connects thousands of apps through workflows called Zaps. Each Zap consists of a trigger — an event in one app — followed by one or more actions that run in response.

ITOC360 has a native Zapier app, so you can pick **ITOC360** as an action in any Zap and route events from thousands of tools straight into your on-call pipeline. No webhook URLs to copy around, no JSON to hand-craft — connect once with a source token and map your fields.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FAUrdNZbxKFwNevGvFCb4%2F22_1-giris-canvas.png?alt=media&amp;token=e792dd09-7af2-4257-945d-114a377e1bdd" alt="" width="563"><figcaption></figcaption></figure>

### In ITOC360

Go to **Sources**, click **Create Source**, and select **Zapier** from the list. Once the source is created, open its detail page and copy the **token** — you will paste it into Zapier in a moment.

### In Zapier

#### Step 1 — Create a new Zap

Click the **+ Create** button in the top left corner and select **Zaps** from the dropdown.

> **Want to skip setup?** Use our ready-made template: [Send daily heartbeat alerts to ITOC360](https://zapier.com/apps/itoc360/integrations/schedule/255731674/send-daily-heartbeat-alerts-to-itoc360) — it creates the Zap with all fields pre-configured; you only connect your ITOC360 account.

#### Step 2 — Set up your trigger

Choose whatever app and event fits your workflow — a failed deployment, a form submission, a new row in a spreadsheet, or anything else. For a quick test, **Schedule by Zapier** works fine.

#### Step 3 — Add the ITOC360 action

Click the **Action** step and type **ITOC360** into the search box. Select the ITOC360 app, then pick **Send Alert** as the event.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FY7eTnH5wzI71vCBcHDxd%2F23_2-step3-app-arama.png?alt=media&amp;token=331bb88f-9c05-4ae1-8633-9bbe59c2a7f6" alt="" width="563"><figcaption></figcaption></figure>

#### Step 4 — Connect your ITOC360 account

When prompted, click **Connect** and paste the source token you copied earlier. That's the only credential Zapier needs — one connection can be reused across all your Zaps.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FR4H924IWUIZpvxpRQYwD%2F24_3-step4-connect-token.png?alt=media&amp;token=2a53ad03-86db-4f01-a0b0-b702a545cf7b" alt=""><figcaption></figcaption></figure>

#### Step 5 — Configure the alert

Fill in the fields, mapping values from your trigger step where it makes sense:

| Field                | Description                                                                                                                                                           |
| -------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Title**(required)  | Short summary of the alert.                                                                                                                                           |
| **Status**(required) | **Trigger (open alert)** to create a new alert, **Resolve** to close an existing one.                                                                                 |
| **Deduplication ID** | A stable identifier for the alert. Send the same value in the trigger and resolve payloads so ITOC360 can match them. If left empty, ITOC360 falls back to the title. |
| **Severity**         | `Critical`, `High`, `Medium`, or `Low`. Defaults to `Medium`.                                                                                                         |
| **Message**          | A longer description with any context your on-call engineer will thank you for.                                                                                       |

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FRGFH2GxY56ME3JWibI0p%2F25_4-step5-configure.png?alt=media&amp;token=469cc358-dc12-40d5-b8bf-d2dd9d7e1f5b" alt="" width="563"><figcaption></figcaption></figure>

#### Step 6 — Test and publish

Click **Test step**. If everything is wired up correctly, Zapier shows the created event in the **Data out** tab, and the alert appears in your ITOC360 dashboard within seconds. Click **Publish** to activate the Zap.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FgFq1IZYSzti5bg4qS7B9%2F26_5-step6-test-dataout-BLURRED.png?alt=media&amp;token=5e14f6de-5753-476a-b039-76f6f4cd770e" alt="" width="563"><figcaption></figcaption></figure>

### Resolving alerts

To close an alert automatically, send a second event with **Status** set to **Resolve** and the same **Deduplication ID** as the original alert. You can do this from a separate Zap, or add a path within the same Zap that fires when your trigger reports recovery. ITOC360 correlates the two events and resolves the open alert.

### Notes

* One ITOC360 connection can be shared by any number of Zaps — you don't need a separate source per workflow.
* Events with the same deduplication ID are grouped together, so repeated triggers won't flood your on-call team with duplicates.
* The ITOC360 app is currently in beta on the Zapier App Directory. Everything is fully functional; the badge just means we're gathering usage before the official listing.

### Alternative: Webhooks by Zapier

If you prefer working with raw webhooks — or you're on a Zapier workflow that already uses them — you can still send events through the generic **Webhooks by Zapier** action instead of the native app.

Add a **Webhooks by Zapier** action with **POST** as the event, and configure it as follows:

**URL** — your ITOC360 webhook URL with the source token appended:

```
https://api.itoc360.app/functions/v1/events?token=<x-itoc360-token>
```

**Payload Type** — `Json`

**Data** — the following key-value pairs:

| Key        | Value                                                         |
| ---------- | ------------------------------------------------------------- |
| `title`    | The alert title (required)                                    |
| `status`   | `trigger` for new alerts, `resolve` for recoveries (required) |
| `message`  | A description of what happened                                |
| `id`       | A unique identifier for deduplication                         |
| `severity` | `critical`, `high`, `medium`, or `low`                        |

Make sure **Wrap Request In Array** is set to **No**.

Note that Webhooks by Zapier is only available on paid Zapier plans, while the native ITOC360 action works on every plan — one more reason to prefer the app.


# Getting started with the ITOC360 mobile app

With the ITOC360 mobile app, you can stay on top of incident response wherever you are. View your dashboard at a glance, track incoming incidents, acknowledge or silence alerts, and follow each incident's escalation timeline — all from your phone. Push notifications keep you informed in real time, and critical alerts can break through Do Not Disturb so an urgent incident never goes unnoticed.

### Download the app for iOS

Download the ITOC360 app from the App Store.

1. Open the **App Store** on your device.
2. Search for ITOC360 and tap **Get**.
3. Wait for the installation to finish.

> App Store link: [ITOC360 on the App Store](https://apps.apple.com/app/itoc360/id6775279282)

### Download the app for Android

Install the ITOC360 app from the Google Play Store.

1. Open the **Play Store** on your device.
2. Search for ITOC360 and tap **Install**.
3. Launch the app once the download completes.

> Play Store link: [ITOC360 on Google Play](https://play.google.com/store/apps/details?id=com.itoc360.app)

### Login

Sign in to your ITOC360 account:

1. Enter your **email** and **password**.
2. Tap **Sign In**.

If you don't have an ITOC360 account yet, ask your team administrator for an invitation, or create one from the ITOC360 web application.

[The app also supports Google, Microsoft, and Slack sign-in. Note that the mobile app offers sign-in only — create your account on the web first. See Single sign-on / SSO.](/users-and-access-management/single-sign-on-sso)

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FYDP8QeqXfuS1UKks3SZv%2F07_IMG_9577.png?alt=media&amp;token=becb2852-5ced-4b00-aa62-57b592fcd4c7" alt="" width="563"><figcaption></figcaption></figure>

### Two-factor authentication

If two-factor authentication is enabled on your account, you'll be asked to verify after entering your password.

1. Enter the **6-digit verification code**.
2. Tap **Continue**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FJvBBlFaiVG5BsWFTwvY0%2F08_IMG_9578.png?alt=media&amp;token=22482448-2265-45a6-94e4-92ad86e84412" alt="" width="563"><figcaption></figcaption></figure>

### Enable push notifications

Push notifications make sure you're alerted the moment an incident is assigned to you. The first time you open the app, ITOC360 automatically registers your device for push notifications — just tap **Allow** when your device asks for notification permission.

Once registered, your device appears as a confirmed **Push** channel under **Settings → Channels**, so there's nothing else to set up.

> If you tapped **Don't Allow** by mistake, enable notifications for itoc360 in your device's system settings, then reopen the app.

### Dashboard

After signing in, the dashboard gives you an at-a-glance overview of your environment:

* **Total Alerts**, **Total Incidents**, **Total Users**, and **Total Sources**, each with a recent activity trend.
* **Open incidents** — a quick count of currently open incidents, with a **View** shortcut.
* **Recent Incidents** — the latest incidents with their status and source. Tap **See All** to open the full list.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FiHJzRdMYVnS3EBP0OL0j%2Fimage.png?alt=media&amp;token=ce46730d-ca44-460b-a5a7-cf70562e01e5" alt="" width="563"><figcaption></figcaption></figure>

### View incidents

Tap **Incidents** in the bottom navigation bar to see all incidents. Each entry shows the incident ID, the source that triggered it, the source type (for example Zabbix), the current status, and when it was last updated. Use the filter icon in the top-right corner to narrow the list.

Tap any incident to open its details.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FKuZFkH5Lntrb7rsKLPwb%2F04_IMG_9574.png?alt=media&amp;token=bb044933-a459-40e4-9ce3-f670eaec584f" alt="" width="563"><figcaption></figcaption></figure>

### Respond to an incident

Opening an incident shows its ID, title, originating source, and current status. From here you can:

* **Acknowledge** — let your team know you're on it and pause further escalation.
* **Silence Alert** — temporarily suppress notifications for the alert (see below).

The **Activities** tab shows the incident's full history: created, triggered, escalated, and closed events with timestamps.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FGCOLnPrkz1GZBH947nej%2F02_IMG_9572%202.png?alt=media&amp;token=6393b57f-56d8-4def-987d-59825ed8af3f" alt="" width="563"><figcaption></figcaption></figure>

### Follow the escalation timeline

Open the **Timeline** tab inside an incident to see how it escalated, level by level. Each escalation level shows its scheduled, started, and completed times, along with every notification that was sent — including the recipient and the channel used (email, SMS, or phone).

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FjKSffTqUe0YO8GbHZbdl%2Fimage.png?alt=media&amp;token=61289745-7c36-4681-8b13-8f9d1779b3de" alt="" width="563"><figcaption></figcaption></figure>

### Silence an alert

Silencing lets you temporarily stop notifications for an alert without closing the incident. While silenced, the alert still appears, but the incident cannot be opened and no one receives a notification.

1. Open the incident and tap **Silence Alert**.
2. Choose a **duration**: 15m, 1h, 4h, 24h, or **Custom**.
3. Optionally add a **description** explaining why you're silencing it.
4. Tap **Silence**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FK5HXiKHhCqEsiLHAB6XX%2F03_IMG_9573.png?alt=media&amp;token=d0f0116e-7b57-4501-9dd0-82bf3ab6d82b" alt="" width="563"><figcaption></figcaption></figure>

### Manage notification channels

Notification channels are the addresses and devices ITOC360 uses to reach you. Open **Settings → Channels** to see your channels. Each one shows its type (push, phone, SMS, or email), its value, and its confirmation status.

#### Add a channel

1. On the **Channels** screen, tap the **+** button.
2. Choose a **Type**: Email, Phone, SMS, or Push.
3. Enter a **Label** and the **Value** (for example, an email address or phone number).
4. Select a **Locale** (English or Turkish).
5. Tap **Add channel**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FxSGNEe0HJxb5AXnlheQA%2Fimage.png?alt=media&amp;token=7c616e8c-4493-4a61-9e0c-4d5d58cc2531" alt="" width="563"><figcaption></figcaption></figure>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FdrbgE4rJVwEYbIGZxSo4%2F16_IMG_9588.png?alt=media&amp;token=3f8e2bb7-4dca-4285-9d6f-c2ca80119b43" alt="" width="563"><figcaption></figcaption></figure>

### Settings

The **Settings** tab gives you access to your account and preferences:

* **Channels** — manage your notification channels.
* **One-Time Password (OTP)** — manage two-factor authentication.
* **Dark mode** — switch between light and dark appearance.
* **Documentations**, **Terms of Service**, and **Privacy Policy** under Helpful Resources.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F8O9jv6RYwxhSP4nmNeFN%2Fimage.png?alt=media&amp;token=083b722f-f340-4c67-bd9c-3ca1415748ba" alt="" width="563"><figcaption></figcaption></figure>


# Organization Settings

The Organization dashboard is the administrative hub of your ITOC360 workspace. Here, you can manage your company profile, onboard new team members, verify domains, and track your subscription usage.

#### Accessing Organization Settings

To access these settings:

1. Click on your **User Profile** at the bottom of the left sidebar.
2. Select **Organization** from the pop-up menu.

#### 1. General

This tab allows you to manage the core identity of your workspace.

* **Name:** The display name of your organization (e.g., "Acme Corp").
* **Slug:** The unique URL identifier for your organization.
* **Leave Organization:** A destructive action allowing you to remove yourself from the workspace.
  * ***Warning:*** This action cannot be undone.

#### 2. Verified Domains

For enhanced security and streamlined onboarding, you can verify your corporate domains.

* **Add Domain:** Enter your company's domain name (e.g., `acmecorp.com`) to claim ownership.

#### 3. Members

This tab provides a roster of all active users currently in your workspace.

* **Member List:** View details of current users, including their names and email addresses.

#### 4. Invites

To grow your team, use the Invites tab to send access links to new colleagues.

* **Send an Invite:** Enter the email address of the person you wish to invite and click the Invite button.
* **Track Status:** The list below shows pending invitations. You can see who sent the invite and its current status (e.g., Pending, Accepted).

#### 5. Subscription

This section gives you full transparency into your billing plan and usage limits.

* **Current Plan:** Displays your active tier (e.g., Business (Growth)) and its status.
* **Cost Breakdown:** Shows the price per user and the total monthly cost.
* **Current Period:** Indicates the billing cycle dates (e.g., January 30 - February 28).
* **Usage & Limits:** A visual progress bar showing how many team member seats you have utilized versus your plan's limit (e.g., "1 / 5 Team Members").
  * ***Pro Tip:*** Check this bar before inviting new members to ensure you have available seats.

#### 6. Billing

Clicking the **Billing** tab redirects you to our secure customer portal (powered by Stripe).

Since financial data is sensitive, all payment operations are handled in this dedicated environment. Here you can:

* **Manage Subscription:** View your current plan details or use the **Cancel Subscription** button if needed.
* **Payment Methods:** Update your credit card information, remove expired cards, or add new payment methods.
* **Billing Information:** Edit your tax ID, billing email, and invoice address.
* **Invoice History:** View and download past invoices with a single click. The history shows dates, amounts, and payment statuses (e.g., "Paid").


# Roles & Permissions

Every user in your ITOC360 organization has a role, and that role decides what they can see and do from acknowledging an incident to changing the subscription. ITOC360 ships with three built-in roles that cover most teams, and if none of them is quite right, you can build your own role by picking exactly the permissions it should include.

You'll find everything under **Management → Roles & Permissions**.

Creating and managing custom roles is available on the **Advanced** and **Premium** plans. The three built-in roles are available on every plan.

### Built-in roles

**Admin** has every permission. Admins are the only ones who can delete things (sources, teams, schedules, escalation policies, channels, domains, maintenance windows, roles), change the plan or payment method, and assign a role to a user. Keep this role for the small group of people who genuinely need to run the organization.

**Manager** is the day-to-day operator. Managers can create and edit almost everything, acknowledge incidents, silence alerts, and invite new users — but they cannot delete anything, cannot touch billing beyond viewing it, and cannot assign roles to other users. This is the right fit for team leads and senior on-call engineers.

**Viewer** is read-only. Viewers can see alerts, incidents, sources, schedules, teams, escalation policies, channels, domains, maintenance windows, roles, and the billing overview — but they can't change any of it, and they can't acknowledge incidents or silence alerts. Useful for stakeholders who want visibility without the risk of a stray click.

Built-in roles can't be edited or deleted. If you need something between Manager and Viewer, create a custom role instead.

### Permissions reference

The tables below show what each built-in role can do. When you create a custom role, these same permissions are the ones you toggle on and off.

#### Alerts

| Permission     | Admin | Manager | Viewer |
| -------------- | ----- | ------- | ------ |
| View alerts    | ✅     | ✅       | ✅      |
| Silence alerts | ✅     | ✅       | —      |

#### Incidents

| Permission            | Admin | Manager | Viewer |
| --------------------- | ----- | ------- | ------ |
| View incidents        | ✅     | ✅       | ✅      |
| Acknowledge incidents | ✅     | ✅       | —      |

#### Sources

| Permission                              | Admin | Manager | Viewer |
| --------------------------------------- | ----- | ------- | ------ |
| View monitoring sources                 | ✅     | ✅       | ✅      |
| Create new sources                      | ✅     | ✅       | —      |
| Edit source settings and configurations | ✅     | ✅       | —      |
| Remove sources                          | ✅     | —       | —      |

#### Escalations

| Permission                                         | Admin | Manager | Viewer |
| -------------------------------------------------- | ----- | ------- | ------ |
| View escalation policies                           | ✅     | ✅       | ✅      |
| Create new escalation policies                     | ✅     | ✅       | —      |
| Edit escalation policy settings and configurations | ✅     | ✅       | —      |
| Remove escalation policies                         | ✅     | —       | —      |

#### Schedules

| Permission                                | Admin | Manager | Viewer |
| ----------------------------------------- | ----- | ------- | ------ |
| View schedules                            | ✅     | ✅       | ✅      |
| Create new schedules                      | ✅     | ✅       | —      |
| Edit schedule settings and configurations | ✅     | ✅       | —      |
| Remove schedules                          | ✅     | —       | —      |

#### Teams

| Permission                            | Admin | Manager | Viewer |
| ------------------------------------- | ----- | ------- | ------ |
| View teams                            | ✅     | ✅       | ✅      |
| Create new teams                      | ✅     | ✅       | —      |
| Edit team settings and configurations | ✅     | ✅       | —      |
| Remove teams                          | ✅     | —       | —      |

#### Channels

| Permission                               | Admin | Manager | Viewer |
| ---------------------------------------- | ----- | ------- | ------ |
| View notification channels               | ✅     | ✅       | ✅      |
| Create new notification channels         | ✅     | ✅       | —      |
| Edit channel settings and configurations | ✅     | ✅       | —      |
| Remove notification channels             | ✅     | —       | —      |

#### Maintenances

| Permission                                          | Admin | Manager | Viewer |
| --------------------------------------------------- | ----- | ------- | ------ |
| View maintenance windows                            | ✅     | ✅       | ✅      |
| Create new maintenance windows                      | ✅     | ✅       | —      |
| Edit maintenance window settings and configurations | ✅     | ✅       | —      |
| Remove maintenance windows                          | ✅     | —       | —      |

#### Domains

| Permission                              | Admin | Manager | Viewer |
| --------------------------------------- | ----- | ------- | ------ |
| View domains                            | ✅     | ✅       | ✅      |
| Create new domains                      | ✅     | ✅       | —      |
| Edit domain settings and configurations | ✅     | ✅       | —      |
| Remove domains                          | ✅     | —       | —      |

#### Roles

| Permission                                                                       | Admin | Manager | Viewer |
| -------------------------------------------------------------------------------- | ----- | ------- | ------ |
| View roles, their assigned permissions, and the assignable permissions catalogue | ✅     | ✅       | ✅      |
| Create new roles within the tenant                                               | ✅     | ✅       | —      |
| Edit roles and their permission assignments                                      | ✅     | ✅       | —      |
| Remove roles from the tenant                                                     | ✅     | —       | —      |

#### Users and invitations

| Permission                            | Admin | Manager | Viewer |
| ------------------------------------- | ----- | ------- | ------ |
| Invite users to tenants               | ✅     | ✅       | —      |
| Assign a role to a user in own tenant | ✅     | —       | —      |

#### Billing

| Permission                                                             | Admin | Manager | Viewer |
| ---------------------------------------------------------------------- | ----- | ------- | ------ |
| View the subscription, plan usage, and invoices                        | ✅     | ✅       | ✅      |
| Change the plan, seats, or payment method, and cancel the subscription | ✅     | —       | —      |

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FCiKwOthuusdUW6XLKWEG%2F43_Ekran%20Resmi%202026-09-01%2015.05.39.png?alt=media&amp;token=55c37425-41b8-4cd3-9f18-3f989c84f1b8" alt=""><figcaption></figcaption></figure>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FZKBbYL6BpHXSv4nBmKhc%2F44_Ekran%20Resmi%202026-09-01%2015.06.13.png?alt=media&amp;token=c91a5d5b-5d7b-4365-9b61-599944b26c14" alt=""><figcaption></figcaption></figure>

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2F4zf8dgckJKj2VaGZkQBt%2F45_Ekran%20Resmi%202026-09-01%2015.06.44.png?alt=media&amp;token=8a1aa569-ce17-4e5e-999d-7d3eb0b19522" alt=""><figcaption></figcaption></figure>

Notice the split in the **Roles** table: a Manager can create and edit roles, but cannot assign a role to a user or delete a role. Those two actions stay with **Admins**.

### Creating a custom role

1. Go to **Management → Roles & Permissions**.
2. Click **Create Role** in the top right.
3. Give the role a name that describes the job, not the person — `Network On-Call`, `Read-only Auditor`, `Billing Owner`.
4. Toggle on the permissions the role should have. Permissions are grouped by area, so start with the group you care about most.
5. Save the role.

The new role appears as a column in the permissions table alongside Admin, Manager, and Viewer, and becomes selectable everywhere a role is chosen.

A few things worth keeping in mind while you pick permissions:

* **Grant the view permission for anything you grant edit on.** A role that can edit schedules but can't view them will hit dead ends in the UI.
* **Delete is always the sharpest edge.** Removing a source, schedule, or escalation policy is not recoverable, so hand out the remove permissions deliberately.
* **Think about who can hand out power.** A role with *Create new roles*, *Edit roles*, and *Assign a role to a user* can effectively promote anyone, including itself.

### Assigning a role to a user

1. Go to **Management → Users**.
2. Find the user and change their role.

Only a role with **Assign a role to a user in own tenant** can do this — by default, Admin.

Role changes take effect on the user's next page load; they don't need to sign out and back in.

### Choosing a role when you invite someone

The invitation form now includes a role selector, so new users land with the right permissions from their very first login instead of being fixed up afterwards.

1. Go to **Organization → Invites** and start a new invitation.
2. Enter the email address.
3. Pick the role from the dropdown — built-in and custom roles both appear here.
4. Send the invitation.

Inviting requires the **Invite users to tenants** permission, which Admin and Manager both have.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FQ3O4b8LOEqOp027RuFp6%2F46_Ekran%20Resmi%202026-09-01%2015.21.28.png?alt=media&amp;token=ea090cb9-6dd1-4e02-ae9a-269a9713089f" alt=""><figcaption></figcaption></figure>

### Editing and deleting a role

Open a custom role from **Roles & Permissions** to change its name or adjust its permissions. Changes apply to everyone already holding that role, so a permission you switch off disappears for those users right away.

Deleting a role needs the **Remove roles from the tenant** permission. Built-in roles cannot be deleted.

### Filtering the table

The permissions table can get long — it covers every permission in the product across every role. Use the search box to filter by permission name, and the **View** control to show or hide role columns so you can compare just the two roles you're interested in.


# Single sign-on / SSO

ITOC360 supports single sign-on (SSO) with three identity providers: **Google**, **Microsoft**, and **Slack**.

SSO removes the need to manage a separate ITOC360 password. You can use it to create a brand-new account or to sign in to an account you already have.

| Provider  | Sign up | Sign in | Web | Mobile |
| --------- | ------- | ------- | --- | ------ |
| Google    | Yes     | Yes     | Yes | Yes    |
| Microsoft | Yes     | Yes     | Yes | Yes    |
| Slack     | Yes     | Yes     | Yes | Yes    |

> **One account, one identity.** ITOC360 matches SSO logins by email address. If an ITOC360 account already exists with the email address returned by your provider, that account is used — a duplicate account is never created. See **Account linking** below.

### Before you begin

* You need an active Google, Microsoft (personal or work/school), or Slack account.
* Any email domain is accepted. A corporate or educational address is not required — personal addresses such as `name@gmail.com` work exactly the same way. Only addresses from known spam or disposable domains are rejected.
* For Slack, you must be a member of at least one Slack workspace. Slack requires a workspace to be selected during authorization; this is Slack's own behaviour and cannot be skipped.

### Signing up with SSO (Web)

Use this flow if you do not have an ITOC360 account yet.

1. Go to the ITOC360 sign-in page and click **Sign up**.
2. Under **OR CONTINUE WITH**, choose **Continue with Google**, **Continue with Microsoft**, or **Continue with Slack**.
3. Complete the provider's authorization screen. See **Provider-specific screens** below.
4. You are returned to ITOC360 and the onboarding flow starts, because a new SSO user does not belong to an organization yet.
5. Follow onboarding to create your organization, then continue to the **Quickstart Guide**.

> **Note:** If an ITOC360 account already exists with the same email address, you are not taken to onboarding. You are signed in to the existing account instead, and the provider is linked to it.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FvnneYKv0PfAUoXUQWRpQ%2F40_Ekran%20Resmi%202026-08-12%2015.50.30.png?alt=media&amp;token=655120aa-5c01-497d-b3ae-e8d9a7f5aee1" alt=""><figcaption></figcaption></figure>

### Signing in with SSO (Web)

1. Go to the ITOC360 sign-in page.
2. Click **Continue with Google**, **Continue with Microsoft**, or **Continue with Slack**.
3. Select your account on the provider's screen and approve access.
4. You are returned to ITOC360 and land on your dashboard.

If two-factor authentication is enabled on your account, you are still prompted for your MFA code after the SSO step. See **SSO and MFA** below.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FwDzY2Mf5zjazIHj5tKOC%2F34_Ekran%20Resmi%202026-08-12%2015.03.03.png?alt=media&amp;token=cd6672c7-2f35-4cc8-bd32-e8c18747a450" alt=""><figcaption></figcaption></figure>

### Provider-specific screens

#### Google

Google opens `accounts.google.com` with a **Choose an account** list showing every Google account signed in on the device, under the heading *Continue to ITOC360*.

1. Select the account you want to use.
2. If the account has never authorized ITOC360, approve the consent screen.

Accounts marked as signed out require you to enter your Google password first.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FGHYXwe3oEHFDPPRBWuKp%2Fimg.png?alt=media&amp;token=e2e235b4-7fbe-42c7-b454-5a1dd875bf12" alt="" width="563"><figcaption></figcaption></figure>

#### Microsoft

Microsoft opens `login.microsoftonline.com` with a **Pick an account** list.

1. Choose your account, or select **Use another account** to sign in with a different one.
2. Approve the permissions request if this is your first time.

Both personal Microsoft accounts and work/school (Entra ID) accounts are supported. Work/school accounts may additionally require your tenant administrator to consent to the ITOC360 application.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FwrrXJwjSz8gwDuR65TAV%2Fimg2.png?alt=media&amp;token=1cfba8e6-7d5d-4e7f-97b2-d44ab49f012b" alt="" width="563"><figcaption></figcaption></figure>

#### Slack

Slack opens **Sign in to ITOC360 with Slack**, where you select a Slack account or workspace.

The consent screen explains that your Slack account details are used to establish a verified connection between an existing ITOC360 account and Slack, to create a new ITOC360 account if you do not have one, and to enable ITOC360 features inside Slack such as configurable notifications, rich link previews, and quick actions. Slack shares your name, email address, profile image, user ID, and team ID with ITOC360.

1. Select the workspace you want to authorize. Workspace selection is mandatory — Slack does not offer a workspace-free login.
2. Click **Accept and Continue**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FQi0J0MEmI2YokOjvN29m%2F38_IMG_1758.png?alt=media&amp;token=43d2722f-a61f-4ff1-84e7-0809949f462f" alt="" width="563"><figcaption></figcaption></figure>

### Signing in with SSO (Mobile)

The ITOC360 mobile app uses the same accounts and the same backend as the web app. Any account that works on the web works on mobile, and vice versa.

1. Open the ITOC360 app and go to the **Welcome back** screen.
2. Below the **OR** divider, tap the **Google**, **Microsoft**, or **Slack** icon.
3. The provider's page opens in an in-app browser (`accounts.google.com`, `login.microsoftonline.com`, or `itoc360.slack.com`).
4. Select your account and approve access.
5. The browser closes and you are signed in.

*Mobile sign-in screen. The three SSO providers appear as icons below the **OR** divider.*

> **Note:** The mobile app shows sign-in buttons only — there is no separate mobile sign-up screen. Create your account and organization once on the web, then sign in on mobile with the same provider.

For everything else about the app, see **Getting started with the ITOC360 mobile app**.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2FvS3SIcV6g5PqJNL0701b%2F36_IMG_1756.png?alt=media&amp;token=c3beda22-8dc0-426f-a12c-6e030c5893a8" alt="" width="563"><figcaption></figcaption></figure>

### Account linking

ITOC360 identifies you by the email address your provider returns.

* **If that email address already belongs to an ITOC360 user**, the provider is linked to that existing user. You are signed in to your current account with your organization, teams, schedules, and escalation policies intact. No second account is created and no data is duplicated.
* **If the email address is not in use**, a new user is created and onboarding starts so you can set up an organization.

Linking happens in one of two ways:

* **Automatically**, the first time you sign in with a provider whose email address matches an existing ITOC360 user.
* **Manually**, from **Account → Security → Connected accounts**, at any time. See **Managing connected accounts** below.

#### Your existing password keeps working

Linking a provider does not disable password login. Once Google is linked to a password-based account, both methods remain valid — sign in with the provider or with your email and password, whichever is convenient.

#### Every provider can be linked to the same account

All three providers match on email address, so they can all point at one ITOC360 user. If your account was created with Google and you later click **Continue with Slack** while your Slack account uses the same email address, you are signed in to the same ITOC360 user. Nothing is duplicated and nothing needs to be merged afterwards.

In practice a single account can be reached four ways: email and password, Google, Microsoft, and Slack — as long as the email address is the same everywhere.

#### Example

Your ITOC360 account is `johndoe@example.com`, created with an email and password. You click **Continue with Google** and pick your `johndoe@example.com` Google account. ITOC360 recognizes the address, links Google to your existing user, and signs you in — same account, same organization, same password as before.

### Managing connected accounts

You do not have to wait until your next sign-in to link a provider. Linked sign-in methods are listed and managed under your account settings.

1. Open **Account** from the sidebar.
2. Switch to the **Security** tab.
3. Scroll to **Connected accounts**.

Each provider is listed with its current state. Providers that are not yet linked show **Not connected** with a **Connect** button.

<figure><img src="https://4108595529-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FimJRSa33y5Ej6rwXrBeA%2Fuploads%2Fl1f61ear7XcclXAcKyD4%2F39_Ekran%20Resmi%202026-08-12%2015.33.01.png?alt=media&amp;token=cfd74888-5686-44be-a889-bab40dec46ff" alt=""><figcaption></figcaption></figure>

***Account → Security → Connected accounts.** Sign-in methods linked to your account.*

#### Connecting a provider

1. Click **Connect** next to the provider you want to add.
2. Complete the provider's authorization screen.
3. You are returned to the **Security** tab and the provider is shown as connected.

From that point on, the provider's button on the sign-in page takes you straight into this account.

> **Note:** The same **Security** tab also holds **Change Password**, **Multi-factor (SMS)**, and **Multi-factor (TOTP)**. Adding an SSO provider does not affect either MFA method. See **Two-factor authentication / MFA**.

### Setting a password for an SSO account

If your account was created through SSO and you also want to sign in with an email and password:

1. On the sign-in page, click **Forgot password?**
2. Enter the email address associated with your SSO account.
3. Open the reset link sent to that address and choose a password.

You can then use either method to sign in.

### SSO and MFA

SSO does not replace ITOC360's two-factor authentication. If MFA is enabled on your account, you are prompted for your authenticator or SMS code after the provider returns you to ITOC360.

To enable, change, or recover MFA, see **Two-factor authentication / MFA**.

### Troubleshooting

| Symptom                                                                 | Cause                                                                                                       | What to do                                                                                                                                    |
| ----------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------- |
| Signed in but landed on onboarding unexpectedly                         | The provider returned an email address that is not attached to any ITOC360 user, so a new user was created. | Sign out of the provider and retry with the account whose address matches your ITOC360 user. Contact Support if a duplicate user was created. |
| Sign-up rejected with an email error                                    | The address belongs to a domain blocked as spam or disposable.                                              | Use a different address. Any regular personal, corporate, or educational domain is accepted.                                                  |
| Microsoft returns a consent or admin-approval error                     | Your work/school tenant requires administrator consent for third-party applications.                        | Ask your Microsoft tenant administrator to approve ITOC360, or sign in with a personal Microsoft account.                                     |
| Slack asks for a workspace and you have none                            | Slack authorization always requires a workspace.                                                            | Join or create a Slack workspace, or use Google or Microsoft instead.                                                                         |
| Provider page does not close on mobile                                  | The in-app browser lost the callback.                                                                       | Close the browser sheet, return to the app, and tap the provider icon again.                                                                  |
| Cannot find where to manage linked providers                            | The list is on the **Security** tab, not the **Profile** tab.                                               | Go to **Account → Security → Connected accounts**.                                                                                            |
| Provider shows **Not connected** even though you have signed in with it | The provider returned a different email address, so it was linked to a different ITOC360 user.              | Click **Connect** on this account to link it explicitly, then contact Support about the duplicate user.                                       |
| Still prompted for a code after SSO                                     | Expected behaviour — MFA is enabled on the account.                                                         | Enter your MFA code. See **Two-factor authentication / MFA**.                                                                                 |

Anything not covered here: **Contacting Support**.


# Two-factor authentication / MFA

Securing your ITOC360 account is critical to preventing unauthorized access to your monitoring and incident management workflows.

This section allows you to manage your login security settings, including enabling Two-Factor Authentication (MFA) and updating your account Password.

#### Accessing Security Settings

To configure these options:

1. Click on your **Profile Icon** in the navigation bar.
2. Select your **Profile**.
3. Navigate to the **Security** tab.

#### Enabling Two-Factor Authentication (MFA)

ITOC360 supports two robust methods for MFA. Enabling either method adds an extra layer of security, requiring both your password and a unique verification code to log in.

**Option 1: TOTP (Authenticator App) -&#x20;*****Recommended***

Time-based One-Time Passwords (TOTP) generate a code that refreshes every 30 seconds via a mobile app. This method works even without cellular signal.

1. In the **Security** tab, locate the MFA section.
2. Select **TOTP** as your method.
3. A QR Code will appear on the screen.
4. Open your preferred authenticator app (e.g., Google Authenticator, Microsoft Authenticator, Authy) on your mobile device.
5. Scan the QR code with the app.
6. Enter the 6-digit code displayed in your app into ITOC360 to verify and activate the setup.

**Option 2: SMS Authentication**

Receive verification codes directly to your mobile phone via text message.

1. In the **Security** tab, select **SMS** as your MFA method.
2. Enter your mobile phone number (including country code).
3. Click **Send Code**.
4. Enter the verification code sent to your phone to confirm and activate SMS MFA.

> **Note:** The phone number used for MFA is for login security only. It does not automatically register this number as a "Channel" for incident alerts. You must configure alerts separately in the *Channels* menu.

[MFA applies to every sign-in method, including Google, Microsoft, and Slack. See Single sign-on / SSO.](/users-and-access-management/single-sign-on-sso)

#### Changing Your Password

You can also update your login credentials directly from the **Security** dashboard.

1. Navigate to the **Change Password** section.
2. **Current Password:** Enter your existing password to verify your identity.
3. **New Password:** Enter your new, strong password.
4. **Confirm Password:** Re-enter the new password to prevent typos.
5. Click **Save** to finalize the change.

> Security Tip: We recommend using a password manager and creating a password with a mix of uppercase letters, lowercase letters, numbers, and symbols.


# Contacting Support

{% hint style="info" %}
**Get help on the first reply.** A clear report (the right link, the channel that misbehaved, and what you expected to happen) lets our team reproduce and resolve your issue without a back-and-forth. This page covers how to reach us and exactly what to send.
{% endhint %}

***

#### How to reach us

Email us at [**support@itoc360.com**](mailto:support@itoc360.com).

We respond to every request and triage by impact. To help us prioritize correctly, tell us how the issue affects you. For example, "no on-call coverage in production right now" versus "a question about configuring a schedule."

{% hint style="warning" %}
For issues affecting **live on-call coverage** (missed pages, escalations not firing), start your subject line with `[URGENT]` so it routes to the front of the queue.
{% endhint %}

***

#### What to include in your request

The more of the following you can give us up front, the faster we can resolve your ticket. You don't need every item. Send what's relevant to your situation.

**The affected alert or incident**

* The **incident link**: open the incident in ITOC360 and copy the URL from your browser address bar.
* The **alert** that misbehaved, or the **date, time, and timezone** you expected a notification to fire.

**What happened vs. what you expected**

A one-line contrast is usually enough, for example:

* "Alert created but no SMS arrived."
* "Voice call rang the wrong responder."
* "Escalation skipped Level 1 and went straight to Level 2."
* "Slack notification posted twice."

**The notification channel involved**

Tell us which channel misbehaved (**voice call, SMS, or email**) and, for voice/SMS, the country the number is registered in. This narrows down delivery-side issues quickly.

**Routing and schedule context**

* The **escalation policy** and **on-call schedule** that were active at the time.
* The **Source** that produced the alert (Prometheus Alertmanager, Grafana, Zabbix, Datadog, custom webhook, etc.).
* Any recent change you made to channels, schedules, escalation policies, or sources before the issue started.

**For sign-in problems**

* Your **sign-in method** (Google, email + password, or SSO).
* Whether signing in at [itoc360.app](https://itoc360.app) from a desktop browser works.
* Whether two-factor authentication is enabled on the account.

**What you've already tried**

A quick note on the steps you took (re-sending a test alert, re-verifying a channel, checking the escalation policy) saves us from suggesting things you've already ruled out.

{% hint style="success" %}
**Optional, but very helpful:** a screenshot or screen recording of the failure, and a copy of the relevant **Activity Log** entry (see below).
{% endhint %}

***

#### Where to find the details we ask for

Most of what we need is already recorded inside ITOC360:

| What we ask for                  | Where to find it                                                                                              |
| -------------------------------- | ------------------------------------------------------------------------------------------------------------- |
| Incident link                    | Open the incident under **Monitoring > Incidents** and copy the browser URL                                   |
| Notification delivery status     | The incident **Activity Log**, which shows every notification sent, the channel used, and the delivery result |
| Channel verification status      | **Management > Channels**                                                                                     |
| Which policy handled the alert   | **Management > Escalations**                                                                                  |
| Which integration sent the alert | The **Source** detail page under **Management > Sources**                                                     |

<details>

<summary>Tip: copy the Activity Log entry</summary>

The Activity Log is the single most useful thing you can attach. It tells us whether a notification was generated, which channel it targeted, and whether delivery succeeded or failed. That immediately tells us if the issue is in routing, in the channel, or downstream at the carrier.

</details>

***

{% content-ref url="<https://docs.itoc360.com/communication-and-shift-management/channels>" %}
<https://docs.itoc360.com/communication-and-shift-management/channels>
{% endcontent-ref %}

{% content-ref url="<https://docs.itoc360.com/on-call-management-and-escalations/escalations>" %}
<https://docs.itoc360.com/on-call-management-and-escalations/escalations>
{% endcontent-ref %}